

kornia.morphology#
- kornia.morphology.dilation(tensor, kernel, structuring_element=None, origin=None, border_type='geodesic', border_value=0.0, max_val=1e4, engine='auto')[source]#
Return the dilated image applying the same kernel in each channel.
The kernel must have 2 dimensions.
- Convention:
dilationreflects the structuring element: it is the Minkowski dilation \(\delta_B f(x) = \max_{b \in B} f(x - b)\), as inscipy.ndimage;erosion()does not reflect.border_type="geodesic"ignores the pixels outside the image; the other modes carry torch’s pad names. Conventions & Pitfalls maps both, and the kernel conventions, onto scipy, scikit-image and OpenCV.Under
geodesica window with no kernel cell inside the image is empty and returns the reduction identity,-infhere and+infinerosion(), as scipy and scikit-image do; so does every window of a kernel with no non-zero cell. The composite operations inherit these infinities.
- Parameters:
tensor (
Tensor) – Floating-point image with shape \((B, C, H, W)\); any other dtype raises aTypeError.kernel (
Tensor) – Positions of non-infinite elements of a flat structuring element. Non-zero values give the set of neighbors of theorigincell over which the operation is applied, and their magnitude is ignored. Its shape is \((k_h, k_w)\), laid over the image’s \((H, W)\) axes. For a full neighborhood pass akernelof all ones.structuring_element (
Optional[Tensor], optional) – Non-flat structuring element, added to the neighbor values before the maximum indilation()and subtracted before the minimum inerosion(). Its shape must equalkernel’s, and any other shape raises aValueError. Default:Noneorigin (
Optional[List[int]], optional) –[row, col]index of the structuring-element cell placed on the output pixel. Default:None, which uses[k_h // 2, k_w // 2]for odd and for even sizes alike ([1, 1]for a \(2 \times 2\) kernel).border_type (
str, optional) – How the image borders are handled. Default:geodesic, which ignores the values that are outside the image when applying the operation. The other accepted values are thetorch.nn.functional.pad()modesconstant,reflect,replicateandcircular.reflectandcircularadditionally require the pad the kernel needs to stay below the image size (reflect) or at most match it (circular), and raise an error otherwise. Any other value raises aValueError.border_value (
float, optional) – Value to fill past edges of input. It is used only whenborder_typeisconstant; undergeodesicthe pixels outside the image are excluded instead, and underreflect,replicateandcircularit is ignored. Default:0.0max_val (
float, optional) – No effect; excluded kernel cells andgeodesicpadding use the reduction identity \(\mp\infty\). Retained for backward compatibility. Default:1e4engine (
str, optional) –"unfold","convolution","shift"or"auto"(default). The"unfold"and"shift"engines compute the same max-plus expression and, for finite inputs, return equal output; only the sign of a zero can differ, because a backend’smax/minmay return either tied operand, and because without astructuring_elementforward-only"shift"skips adding the zero offsets, which turn a-0.0pixel into+0.0indilation()with"unfold"."auto"picks"unfold"on CUDA, and off CUDA the exact"shift"engine, except that a CPU call which computes in float32 or float64 (the image dtype, or the wider dtype ofstructuring_element, else ofkernel) and records a backward graph takes"unfold", where"shift"is slower."convolution"runs through the backend’sconv2dand inherits its precision: a float32 convolution that computes in reduced precision (macOS CPU, CUDA with TF32 enabled) rounds the output."shift"takes a running max or min over the \(k_h k_w\) shifted views of the padded image. It is exact, and forward-only it needs no \(k_h k_w\)-sized intermediate; under autograd it instead saves \(2 (k_h k_w - 1)\) output-sized tensors for the backward pass, which is more memory than"unfold", not less. Default:"auto"
- Return type:
- Returns:
Dilated image with shape \((B, C, H, W)\).
Note
See a working example here.
Example
>>> tensor = torch.rand(1, 3, 5, 5)
>>> kernel = torch.ones(3, 3)
>>> dilated_img = dilation(tensor, kernel)
- kornia.morphology.erosion(tensor, kernel, structuring_element=None, origin=None, border_type='geodesic', border_value=0.0, max_val=1e4, engine='auto')[source]#
Return the eroded image applying the same kernel in each channel.
The kernel must have 2 dimensions.
- Convention:
As
dilation(), except thaterosiondoes not reflect the structuring element: it is the Minkowski erosion \(\varepsilon_B f(x) = \min_{b \in B} f(x + b)\), as inscipy.ndimageand OpenCV.structuring_elementis subtracted before the minimum.
- Parameters:
tensor (
Tensor) – Floating-point image with shape \((B, C, H, W)\); any other dtype raises aTypeError.kernel (
Tensor) – Positions of non-infinite elements of a flat structuring element. Non-zero values give the set of neighbors of theorigincell over which the operation is applied, and their magnitude is ignored. Its shape is \((k_h, k_w)\), laid over the image’s \((H, W)\) axes. For a full neighborhood pass akernelof all ones.structuring_element (
Optional[Tensor], optional) – Non-flat structuring element, added to the neighbor values before the maximum indilation()and subtracted before the minimum inerosion(). Its shape must equalkernel’s, and any other shape raises aValueError. Default:Noneorigin (
Optional[List[int]], optional) –[row, col]index of the structuring-element cell placed on the output pixel. Default:None, which uses[k_h // 2, k_w // 2]for odd and for even sizes alike ([1, 1]for a \(2 \times 2\) kernel).border_type (
str, optional) – How the image borders are handled. Default:geodesic, which ignores the values that are outside the image when applying the operation. The other accepted values are thetorch.nn.functional.pad()modesconstant,reflect,replicateandcircular.reflectandcircularadditionally require the pad the kernel needs to stay below the image size (reflect) or at most match it (circular), and raise an error otherwise. Any other value raises aValueError.border_value (
float, optional) – Value to fill past edges of input. It is used only whenborder_typeisconstant; undergeodesicthe pixels outside the image are excluded instead, and underreflect,replicateandcircularit is ignored. Default:0.0max_val (
float, optional) – No effect; excluded kernel cells andgeodesicpadding use the reduction identity \(\mp\infty\). Retained for backward compatibility. Default:1e4engine (
str, optional) –"unfold","convolution","shift"or"auto"(default). The"unfold"and"shift"engines compute the same max-plus expression and, for finite inputs, return equal output; only the sign of a zero can differ, because a backend’smax/minmay return either tied operand, and because without astructuring_elementforward-only"shift"skips adding the zero offsets, which turn a-0.0pixel into+0.0indilation()with"unfold"."auto"picks"unfold"on CUDA, and off CUDA the exact"shift"engine, except that a CPU call which computes in float32 or float64 (the image dtype, or the wider dtype ofstructuring_element, else ofkernel) and records a backward graph takes"unfold", where"shift"is slower."convolution"runs through the backend’sconv2dand inherits its precision: a float32 convolution that computes in reduced precision (macOS CPU, CUDA with TF32 enabled) rounds the output."shift"takes a running max or min over the \(k_h k_w\) shifted views of the padded image. It is exact, and forward-only it needs no \(k_h k_w\)-sized intermediate; under autograd it instead saves \(2 (k_h k_w - 1)\) output-sized tensors for the backward pass, which is more memory than"unfold", not less. Default:"auto"
- Return type:
- Returns:
Eroded image with shape \((B, C, H, W)\).
Note
See a working example here.
Example
>>> tensor = torch.rand(1, 3, 5, 5)
>>> kernel = torch.ones(5, 5)
>>> output = erosion(tensor, kernel)
- kornia.morphology.opening(tensor, kernel, structuring_element=None, origin=None, border_type='geodesic', border_value=0.0, max_val=1e4, engine='auto')[source]#
Return the opened image, (that means, dilation after an erosion) applying the same kernel in each channel.
The kernel must have 2 dimensions.
- Convention:
openingisdilation(erosion(tensor))with the same arguments in both halves. As onlydilation()reflects the kernel, it is a morphological opening (anti-extensive and idempotent) for an asymmetric kernel too, undergeodesicorcircular; a non-flatstructuring_elementorengine="convolution"holds both properties only to roundoff, andconstant,reflectandreplicatecan break them.
- Parameters:
tensor (
Tensor) – Floating-point image with shape \((B, C, H, W)\); any other dtype raises aTypeError.kernel (
Tensor) – Positions of non-infinite elements of a flat structuring element. Non-zero values give the set of neighbors of theorigincell over which the operation is applied, and their magnitude is ignored. Its shape is \((k_h, k_w)\), laid over the image’s \((H, W)\) axes. For a full neighborhood pass akernelof all ones.structuring_element (
Optional[Tensor], optional) – Non-flat structuring element, added to the neighbor values before the maximum indilation()and subtracted before the minimum inerosion(). Its shape must equalkernel’s, and any other shape raises aValueError. Default:Noneorigin (
Optional[List[int]], optional) –[row, col]index of the structuring-element cell placed on the output pixel. Default:None, which uses[k_h // 2, k_w // 2]for odd and for even sizes alike ([1, 1]for a \(2 \times 2\) kernel).border_type (
str, optional) – How the image borders are handled. Default:geodesic, which ignores the values that are outside the image when applying the operation. The other accepted values are thetorch.nn.functional.pad()modesconstant,reflect,replicateandcircular.reflectandcircularadditionally require the pad the kernel needs to stay below the image size (reflect) or at most match it (circular), and raise an error otherwise. Any other value raises aValueError.border_value (
float, optional) – Value to fill past edges of input. It is used only whenborder_typeisconstant; undergeodesicthe pixels outside the image are excluded instead, and underreflect,replicateandcircularit is ignored. Default:0.0max_val (
float, optional) – No effect; excluded kernel cells andgeodesicpadding use the reduction identity \(\mp\infty\). Retained for backward compatibility. Default:1e4engine (
str, optional) –"unfold","convolution","shift"or"auto"(default). The"unfold"and"shift"engines compute the same max-plus expression and, for finite inputs, return equal output; only the sign of a zero can differ, because a backend’smax/minmay return either tied operand, and because without astructuring_elementforward-only"shift"skips adding the zero offsets, which turn a-0.0pixel into+0.0indilation()with"unfold"."auto"picks"unfold"on CUDA, and off CUDA the exact"shift"engine, except that a CPU call which computes in float32 or float64 (the image dtype, or the wider dtype ofstructuring_element, else ofkernel) and records a backward graph takes"unfold", where"shift"is slower."convolution"runs through the backend’sconv2dand inherits its precision: a float32 convolution that computes in reduced precision (macOS CPU, CUDA with TF32 enabled) rounds the output."shift"takes a running max or min over the \(k_h k_w\) shifted views of the padded image. It is exact, and forward-only it needs no \(k_h k_w\)-sized intermediate; under autograd it instead saves \(2 (k_h k_w - 1)\) output-sized tensors for the backward pass, which is more memory than"unfold", not less. Default:"auto"
- Return type:
- Returns:
Opened image with shape \((B, C, H, W)\).
Note
See a working example here.
Example
>>> tensor = torch.rand(1, 3, 5, 5)
>>> kernel = torch.ones(3, 3)
>>> opened_img = opening(tensor, kernel)
- kornia.morphology.closing(tensor, kernel, structuring_element=None, origin=None, border_type='geodesic', border_value=0.0, max_val=1e4, engine='auto')[source]#
Return the closed image, (that means, erosion after a dilation) applying the same kernel in each channel.
The kernel must have 2 dimensions.
- Convention:
closingiserosion(dilation(tensor))with the same arguments in both halves. As onlydilation()reflects the kernel, it is a morphological closing (extensive and idempotent) for an asymmetric kernel too, undergeodesicorcircular; a non-flatstructuring_elementorengine="convolution"holds both properties only to roundoff, andconstant,reflectandreplicatecan break them.
- Parameters:
tensor (
Tensor) – Floating-point image with shape \((B, C, H, W)\); any other dtype raises aTypeError.kernel (
Tensor) – Positions of non-infinite elements of a flat structuring element. Non-zero values give the set of neighbors of theorigincell over which the operation is applied, and their magnitude is ignored. Its shape is \((k_h, k_w)\), laid over the image’s \((H, W)\) axes. For a full neighborhood pass akernelof all ones.structuring_element (
Optional[Tensor], optional) – Non-flat structuring element, added to the neighbor values before the maximum indilation()and subtracted before the minimum inerosion(). Its shape must equalkernel’s, and any other shape raises aValueError. Default:Noneorigin (
Optional[List[int]], optional) –[row, col]index of the structuring-element cell placed on the output pixel. Default:None, which uses[k_h // 2, k_w // 2]for odd and for even sizes alike ([1, 1]for a \(2 \times 2\) kernel).border_type (
str, optional) – How the image borders are handled. Default:geodesic, which ignores the values that are outside the image when applying the operation. The other accepted values are thetorch.nn.functional.pad()modesconstant,reflect,replicateandcircular.reflectandcircularadditionally require the pad the kernel needs to stay below the image size (reflect) or at most match it (circular), and raise an error otherwise. Any other value raises aValueError.border_value (
float, optional) – Value to fill past edges of input. It is used only whenborder_typeisconstant; undergeodesicthe pixels outside the image are excluded instead, and underreflect,replicateandcircularit is ignored. Default:0.0max_val (
float, optional) – No effect; excluded kernel cells andgeodesicpadding use the reduction identity \(\mp\infty\). Retained for backward compatibility. Default:1e4engine (
str, optional) –"unfold","convolution","shift"or"auto"(default). The"unfold"and"shift"engines compute the same max-plus expression and, for finite inputs, return equal output; only the sign of a zero can differ, because a backend’smax/minmay return either tied operand, and because without astructuring_elementforward-only"shift"skips adding the zero offsets, which turn a-0.0pixel into+0.0indilation()with"unfold"."auto"picks"unfold"on CUDA, and off CUDA the exact"shift"engine, except that a CPU call which computes in float32 or float64 (the image dtype, or the wider dtype ofstructuring_element, else ofkernel) and records a backward graph takes"unfold", where"shift"is slower."convolution"runs through the backend’sconv2dand inherits its precision: a float32 convolution that computes in reduced precision (macOS CPU, CUDA with TF32 enabled) rounds the output."shift"takes a running max or min over the \(k_h k_w\) shifted views of the padded image. It is exact, and forward-only it needs no \(k_h k_w\)-sized intermediate; under autograd it instead saves \(2 (k_h k_w - 1)\) output-sized tensors for the backward pass, which is more memory than"unfold", not less. Default:"auto"
- Return type:
- Returns:
Closed image with shape \((B, C, H, W)\).
Note
See a working example here.
Example
>>> tensor = torch.rand(1, 3, 5, 5)
>>> kernel = torch.ones(3, 3)
>>> closed_img = closing(tensor, kernel)
- kornia.morphology.gradient(tensor, kernel, structuring_element=None, origin=None, border_type='geodesic', border_value=0.0, max_val=1e4, engine='auto')[source]#
Return the morphological gradient of an image.
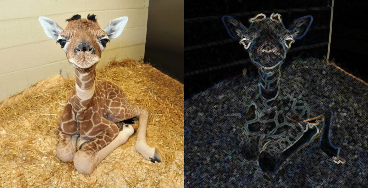
That means, (dilation - erosion) applying the same kernel in each channel. The kernel must have 2 dimensions.
- Convention:
gradientisdilation(tensor) - erosion(tensor)with the same arguments; seedilation().
- Parameters:
tensor (
Tensor) – Floating-point image with shape \((B, C, H, W)\); any other dtype raises aTypeError.kernel (
Tensor) – Positions of non-infinite elements of a flat structuring element. Non-zero values give the set of neighbors of theorigincell over which the operation is applied, and their magnitude is ignored. Its shape is \((k_h, k_w)\), laid over the image’s \((H, W)\) axes. For a full neighborhood pass akernelof all ones.structuring_element (
Optional[Tensor], optional) – Non-flat structuring element, added to the neighbor values before the maximum indilation()and subtracted before the minimum inerosion(). Its shape must equalkernel’s, and any other shape raises aValueError. Default:Noneorigin (
Optional[List[int]], optional) –[row, col]index of the structuring-element cell placed on the output pixel. Default:None, which uses[k_h // 2, k_w // 2]for odd and for even sizes alike ([1, 1]for a \(2 \times 2\) kernel).border_type (
str, optional) – How the image borders are handled. Default:geodesic, which ignores the values that are outside the image when applying the operation. The other accepted values are thetorch.nn.functional.pad()modesconstant,reflect,replicateandcircular.reflectandcircularadditionally require the pad the kernel needs to stay below the image size (reflect) or at most match it (circular), and raise an error otherwise. Any other value raises aValueError.border_value (
float, optional) – Value to fill past edges of input. It is used only whenborder_typeisconstant; undergeodesicthe pixels outside the image are excluded instead, and underreflect,replicateandcircularit is ignored. Default:0.0max_val (
float, optional) – No effect; excluded kernel cells andgeodesicpadding use the reduction identity \(\mp\infty\). Retained for backward compatibility. Default:1e4engine (
str, optional) –"unfold","convolution","shift"or"auto"(default). The"unfold"and"shift"engines compute the same max-plus expression and, for finite inputs, return equal output; only the sign of a zero can differ, because a backend’smax/minmay return either tied operand, and because without astructuring_elementforward-only"shift"skips adding the zero offsets, which turn a-0.0pixel into+0.0indilation()with"unfold"."auto"picks"unfold"on CUDA, and off CUDA the exact"shift"engine, except that a CPU call which computes in float32 or float64 (the image dtype, or the wider dtype ofstructuring_element, else ofkernel) and records a backward graph takes"unfold", where"shift"is slower."convolution"runs through the backend’sconv2dand inherits its precision: a float32 convolution that computes in reduced precision (macOS CPU, CUDA with TF32 enabled) rounds the output."shift"takes a running max or min over the \(k_h k_w\) shifted views of the padded image. It is exact, and forward-only it needs no \(k_h k_w\)-sized intermediate; under autograd it instead saves \(2 (k_h k_w - 1)\) output-sized tensors for the backward pass, which is more memory than"unfold", not less. Default:"auto"
- Return type:
- Returns:
Gradient image with shape \((B, C, H, W)\).
Note
See a working example here.
Example
>>> tensor = torch.rand(1, 3, 5, 5)
>>> kernel = torch.ones(3, 3)
>>> gradient_img = gradient(tensor, kernel)
- kornia.morphology.top_hat(tensor, kernel, structuring_element=None, origin=None, border_type='geodesic', border_value=0.0, max_val=1e4, engine='auto')[source]#
Return the top hat transformation of an image.
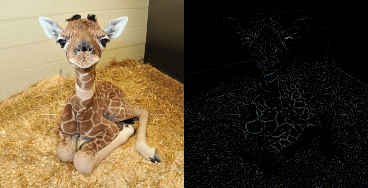
That means, (image - opened_image) applying the same kernel in each channel. The kernel must have 2 dimensions.
See
opening()for details.- Convention:
top_hatistensor - opening(tensor)with the same arguments.
- Parameters:
tensor (
Tensor) – Floating-point image with shape \((B, C, H, W)\); any other dtype raises aTypeError.kernel (
Tensor) – Positions of non-infinite elements of a flat structuring element. Non-zero values give the set of neighbors of theorigincell over which the operation is applied, and their magnitude is ignored. Its shape is \((k_h, k_w)\), laid over the image’s \((H, W)\) axes. For a full neighborhood pass akernelof all ones.structuring_element (
Optional[Tensor], optional) – Non-flat structuring element, added to the neighbor values before the maximum indilation()and subtracted before the minimum inerosion(). Its shape must equalkernel’s, and any other shape raises aValueError. Default:Noneorigin (
Optional[List[int]], optional) –[row, col]index of the structuring-element cell placed on the output pixel. Default:None, which uses[k_h // 2, k_w // 2]for odd and for even sizes alike ([1, 1]for a \(2 \times 2\) kernel).border_type (
str, optional) – How the image borders are handled. Default:geodesic, which ignores the values that are outside the image when applying the operation. The other accepted values are thetorch.nn.functional.pad()modesconstant,reflect,replicateandcircular.reflectandcircularadditionally require the pad the kernel needs to stay below the image size (reflect) or at most match it (circular), and raise an error otherwise. Any other value raises aValueError.border_value (
float, optional) – Value to fill past edges of input. It is used only whenborder_typeisconstant; undergeodesicthe pixels outside the image are excluded instead, and underreflect,replicateandcircularit is ignored. Default:0.0max_val (
float, optional) – No effect; excluded kernel cells andgeodesicpadding use the reduction identity \(\mp\infty\). Retained for backward compatibility. Default:1e4engine (
str, optional) –"unfold","convolution","shift"or"auto"(default). The"unfold"and"shift"engines compute the same max-plus expression and, for finite inputs, return equal output; only the sign of a zero can differ, because a backend’smax/minmay return either tied operand, and because without astructuring_elementforward-only"shift"skips adding the zero offsets, which turn a-0.0pixel into+0.0indilation()with"unfold"."auto"picks"unfold"on CUDA, and off CUDA the exact"shift"engine, except that a CPU call which computes in float32 or float64 (the image dtype, or the wider dtype ofstructuring_element, else ofkernel) and records a backward graph takes"unfold", where"shift"is slower."convolution"runs through the backend’sconv2dand inherits its precision: a float32 convolution that computes in reduced precision (macOS CPU, CUDA with TF32 enabled) rounds the output."shift"takes a running max or min over the \(k_h k_w\) shifted views of the padded image. It is exact, and forward-only it needs no \(k_h k_w\)-sized intermediate; under autograd it instead saves \(2 (k_h k_w - 1)\) output-sized tensors for the backward pass, which is more memory than"unfold", not less. Default:"auto"
- Return type:
- Returns:
Top hat transformed image with shape \((B, C, H, W)\).
Note
See a working example here.
Example
>>> tensor = torch.rand(1, 3, 5, 5)
>>> kernel = torch.ones(3, 3)
>>> top_hat_img = top_hat(tensor, kernel)
- kornia.morphology.bottom_hat(tensor, kernel, structuring_element=None, origin=None, border_type='geodesic', border_value=0.0, max_val=1e4, engine='auto')[source]#
Return the bottom hat transformation of an image.
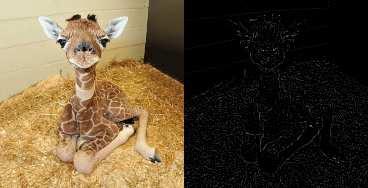
That means, (closed_image - image) applying the same kernel in each channel. The kernel must have 2 dimensions.
See
closing()for details.- Convention:
bottom_hatisclosing(tensor) - tensorwith the same arguments.
- Parameters:
tensor (
Tensor) – Floating-point image with shape \((B, C, H, W)\); any other dtype raises aTypeError.kernel (
Tensor) – Positions of non-infinite elements of a flat structuring element. Non-zero values give the set of neighbors of theorigincell over which the operation is applied, and their magnitude is ignored. Its shape is \((k_h, k_w)\), laid over the image’s \((H, W)\) axes. For a full neighborhood pass akernelof all ones.structuring_element (
Optional[Tensor], optional) – Non-flat structuring element, added to the neighbor values before the maximum indilation()and subtracted before the minimum inerosion(). Its shape must equalkernel’s, and any other shape raises aValueError. Default:Noneorigin (
Optional[List[int]], optional) –[row, col]index of the structuring-element cell placed on the output pixel. Default:None, which uses[k_h // 2, k_w // 2]for odd and for even sizes alike ([1, 1]for a \(2 \times 2\) kernel).border_type (
str, optional) – How the image borders are handled. Default:geodesic, which ignores the values that are outside the image when applying the operation. The other accepted values are thetorch.nn.functional.pad()modesconstant,reflect,replicateandcircular.reflectandcircularadditionally require the pad the kernel needs to stay below the image size (reflect) or at most match it (circular), and raise an error otherwise. Any other value raises aValueError.border_value (
float, optional) – Value to fill past edges of input. It is used only whenborder_typeisconstant; undergeodesicthe pixels outside the image are excluded instead, and underreflect,replicateandcircularit is ignored. Default:0.0max_val (
float, optional) – No effect; excluded kernel cells andgeodesicpadding use the reduction identity \(\mp\infty\). Retained for backward compatibility. Default:1e4engine (
str, optional) –"unfold","convolution","shift"or"auto"(default). The"unfold"and"shift"engines compute the same max-plus expression and, for finite inputs, return equal output; only the sign of a zero can differ, because a backend’smax/minmay return either tied operand, and because without astructuring_elementforward-only"shift"skips adding the zero offsets, which turn a-0.0pixel into+0.0indilation()with"unfold"."auto"picks"unfold"on CUDA, and off CUDA the exact"shift"engine, except that a CPU call which computes in float32 or float64 (the image dtype, or the wider dtype ofstructuring_element, else ofkernel) and records a backward graph takes"unfold", where"shift"is slower."convolution"runs through the backend’sconv2dand inherits its precision: a float32 convolution that computes in reduced precision (macOS CPU, CUDA with TF32 enabled) rounds the output."shift"takes a running max or min over the \(k_h k_w\) shifted views of the padded image. It is exact, and forward-only it needs no \(k_h k_w\)-sized intermediate; under autograd it instead saves \(2 (k_h k_w - 1)\) output-sized tensors for the backward pass, which is more memory than"unfold", not less. Default:"auto"
- Return type:
- Returns:
Bottom hat transformed image with shape \((B, C, H, W)\).
Note
See a working example here.
Example
>>> tensor = torch.rand(1, 3, 5, 5)
>>> kernel = torch.ones(3, 3)
>>> bottom_hat_img = bottom_hat(tensor, kernel)
- kornia.morphology.reconstruction(seed, mask, kernel=None, method='dilation', num_iters=None, check_every=4, engine='auto')[source]#
Return the morphological reconstruction of
seedbounded bymask, applied to each channel.Reconstruction by dilation repeats the geodesic dilation \(\min(\delta_B(x), \text{mask})\), starting from \(\min(\text{seed}, \text{mask})\), until the result stops changing. Reconstruction by erosion is its dual, \(-\text{reconstruction}(-\text{seed}, -\text{mask})\). See L. Vincent, “Morphological grayscale reconstruction in image analysis: applications and efficient algorithms”, IEEE TIP 1993. Under autograd every step keeps its intermediates, so memory grows with the number of steps.
- Convention:
Matches
skimage.morphology.reconstruction: the defaultkernelis a \(3 \times 3\) square, its center cell is always part of the neighborhood, and both methods spread a pixel’s value to the kernel’s offsets, asdilation()does. scikit-image’sdilationspreads the other way, but itsreconstructionagrees. The image border isgeodesic. Unlike scikit-image, aseedabovemask(below it for"erosion") is clipped tomaskinstead of raising.
- Parameters:
seed (
Tensor) – Floating-point starting image with shape \((B, C, H, W)\).mask (
Tensor) – Floating-point image bounding the reconstruction, with the same shape asseed.kernel (
Optional[Tensor], optional) – Offsets from the center that a pixel’s value spreads to in one step, with shape \((k_h, k_w)\) and odd sizes. Non-zero cells mark an offset; their magnitude and dtype are ignored. Default:None, which uses a \(3 \times 3\) square.method (
str, optional) –"dilation"(default) or"erosion". Default:"dilation"num_iters (
Optional[int], optional) – Number of steps to run. Default:None, which runs until the result stops changing. That can take far more steps than \(\max(H, W)\) whenmaskhas winding paths. A fixed count always runs that many steps, even past convergence. It has no data-dependent exit, sotorch.compilecaptures it as one graph, but the loop is unrolled and compile time grows with the count.check_every (
int, optional) – Number of steps between convergence checks whennum_itersisNone. Each check syncs the device with the host, and steps past convergence are wasted, so a larger value suits inputs that take many steps. For inputs without NaN, the output does not depend on it. Default:4.engine (
str, optional) –"unfold","shift"or"auto"(default), passed todilation()."convolution"is rejected: it is not exact on every backend, and an inexact step can keep the loop from converging. Default:"auto"
- Return type:
- Returns:
Reconstructed image with shape \((B, C, H, W)\) and the promoted dtype of
seedandmask.- Raises:
TypeCheckError – if
seed,maskorkernelis not a tensor.ShapeError – if
seedis not 4-dimensional,maskhas another shape, orkernelis not 2-dimensional.ValueCheckError – if
engineis"convolution", also with checks disabled.BaseError – if
seedormaskis not floating point, akernelsize is even,methodorengineis not one of the values above,num_itersis negative, orcheck_everyis not positive.
Example
>>> mask = torch.rand(1, 3, 5, 5)
>>> seed = mask * 0.5
>>> output = reconstruction(seed, mask)