

kornia.geometry.transform#
The functions in this section warp, resize, crop, flip and register 2D images and 3D volumes. The warps take a
matrix that maps source pixels to destination pixels (warp_perspective(), warp_affine() and their 3D
forms), except homography_warp() and homography_warp3d(), which take a destination→source homography in
normalized \([-1, 1]\) coordinates by default. The 2D image transforms rotate(), translate(),
scale() and shear() take parameters instead of a matrix and affine() takes a matrix, all at the
image size; resize() and rescale() change the size. align_corners defaults differ between these
functions; see Conventions & Pitfalls.
Warp operators#
Warp images (B, C, H, W) or volumes (B, C, D, H, W) to the output size dsize by a source→destination
pixel homography (warp_perspective(), warp_perspective3d()) or affine matrix (warp_affine(),
warp_affine3d()), or by a destination→source homography in normalized coordinates (homography_warp(),
homography_warp3d()). Sample an image at per-pixel source coordinates with remap(), or warp it by
thin-plate-spline control points with warp_image_tps() (and points with warp_points_tps()).
warp_grid() and warp_grid3d() return the warped sampling grid without sampling.
- kornia.geometry.transform.warp_perspective(src, M, dsize, mode='bilinear', padding_mode='zeros', align_corners=True, fill_value=None)[source]#
Warp an image by a source→destination homography in pixel coordinates.
out = warp_perspective(src, M, dsize)takes images(B, C, H, W)and one(B, 3, 3)homography per image that maps source pixels to destination pixels, and returns the(B, C, h, w)destination images fordsize = (h, w). Pixel centres are integers, so an identityMwith a smallerdsizereturns the top-leftdsizewindow of the image, not a resized image. This is the warp for the homographies thatget_perspective_transform(),find_homography_dlt()andRANSACreturn; for a destination→source homography in normalized \([-1, 1]\) coordinates, usehomography_warp(), and for a(B, 2, 3)affine matrix,warp_affine().Each output pixel
(x, y)samples the source at the inverse ofMapplied to it:\[\text{dst} (x, y) = \text{src} \left( \frac{M^{-1}_{11} x + M^{-1}_{12} y + M^{-1}_{13}}{M^{-1}_{31} x + M^{-1}_{32} y + M^{-1}_{33}} , \frac{M^{-1}_{21} x + M^{-1}_{22} y + M^{-1}_{23}}{M^{-1}_{31} x + M^{-1}_{32} y + M^{-1}_{33}} \right )\]- Convention:
See Conventions & Pitfalls for transform direction, pixel centres, normalized coordinates and
align_cornerssampling rules.Mis the source→destination pixel homography(B, 3, 3)(contrasthomography_warp(), which by default consumes destination→source normalized)Mhas the batch ofsrc: a(1, 3, 3)Mis not shared by a larger batch, as it is inwarp_affine()a nonzero scalar multiple of
Mdescribes the same warp; uniformly small or large nonzero entries are rescaled toward unit magnitude before the coordinate change and inversiona one-pixel source axis is sampled like a longer one, so positions outside it get
padding_mode. Underalign_corners=True, wheregrid_samplealone would land them all on that pixel,'zeros'and'fill'read it as the first of two pixels, the second holding the padding (#6433)srcsets the dtype: a float32Mwith a float64srcsamples in float64, and a float64Mwith a float32srcraisesRuntimeErrora caller’s autocast region does not change the matrix arithmetic or the sampling grid, outside TorchScript (in the region, a
srcandMthat mix float32 and half dtypes run in float32)a zero output dimension returns an autograd-connected empty tensor; negative output dimensions raise
ValueError
- Parameters:
src (
Tensor) – input image with shape(B, C, H, W).M (
Tensor) – transformation matrix with shape(B, 3, 3).dsize (
tuple[int,int]) – size of the output image (height, width).mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'|'fill'. Default:"zeros"align_corners (
bool, optional) – interpolation flag. Default:Truefill_value (
Optional[Tensor], optional) – torch.Tensor of shape(C)or(1)that fills the padding area, or any shape that broadcasts to the output(B, C, h, w)without changing it, such as a per-sample(B, C, 1, 1)fill. Defaults to zeros. Default:None
- Return type:
- Returns:
the warped input image
(B, C, h, w), spatial sizes given bydsize.
See also
homography_warp(): a destination→source homography, normalized to \([-1, 1]\) by default.warp_perspective3d(): the same warp for(B, C, D, H, W)volumes by(B, 4, 4)homographies.warp_affine(): a(B, 2, 3)affine matrix instead, where a single(1, 2, 3)one serves a batch.get_perspective_transform(): the homography that maps four source points onto four destination points.remap(): sample at given per-pixel source coordinates instead of by a matrix.crop_by_transform_mat(): dispatches to this warp orwarp_affine()by matrix shape, casting the matrix to the image dtype and broadcasting a batch-1 matrix.normalize_homography():Min normalized \([-1, 1]\) coordinates, the conversion this warp applies before sampling.
Example
>>> img = torch.rand(1, 4, 5, 6)
>>> H = torch.eye(3)[None]
>>> out = warp_perspective(img, H, (4, 2), align_corners=True)
>>> print(out.shape)
torch.Size([1, 4, 4, 2])
Note
See a working example here.
- kornia.geometry.transform.warp_perspective3d(src, M, dsize, flags='bilinear', border_mode='zeros', align_corners=False)[source]#
Warp a volume by a source→destination 4x4 homography in voxel coordinates.
out = warp_perspective3d(src, M, dsize)takes volumes(B, C, D, H, W)and one(B, 4, 4)homography per volume that maps source voxels(x, y, z)to destination voxels, and returns the(B, C, d, h, w)destination volumes fordsize = (d, h, w);flagsis the interpolation mode andborder_modethe padding mode. Passalign_corners=True: at the defaultFalsethe sampling grid is corner-aligned whilegrid_samplereads half-voxel coordinates, so even an identityMresamples the volume (#4503). For images, usewarp_perspective(); for a(B, 3, 4)affine matrix,warp_affine3d().Each output voxel samples the source at:
\[\text{dst}(x, y, z) = \text{src}\left( \pi\left( M^{-1} \cdot (x, y, z, 1)^{T} \right) \right)\]where \(\pi\) divides by the fourth (homogeneous) coordinate.
- Convention:
Mis the source→destination pixel homography(B, 4, 4), with the batch ofsrc; an unbatched(4, 4)Mis accepted for a single volumealign_corners:
Falseby default (differs from the 2Dwarp_perspective(), whose default isTrue)border_mode:
'zeros'by defaultunder
align_corners=True, a one-voxel source axis is sampled like a longer one, so positions outside it getborder_mode:'zeros'reads it as the first of two voxels, the second holding the padding (#6433)a caller’s autocast region does not change the matrix arithmetic or the sampling grid, outside TorchScript (in the region, a
srcandMthat mix float32 and half dtypes run in float32)a zero output dimension returns an autograd-connected empty tensor; negative output dimensions raise
ValueError
- Parameters:
src (
Tensor) – input image with shape(B, C, D, H, W).M (
Tensor) – transformation matrix with shape(B, 4, 4).dsize (
tuple[int,int,int]) – size of the output image (depth, height, width).flags (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"border_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – interpolation flag. Default:False
- Return type:
- Returns:
the warped input image
(B, C, d, h, w), spatial sizes given bydsize.
See also
warp_perspective(): the 2D warp of images by(B, 3, 3)homographies.warp_affine3d(): a(B, 3, 4)affine matrix, correct at its defaultalign_corners=True.homography_warp3d(): a destination→source homography, in normalized coordinates by default.get_perspective_transform3d(): the homography that maps box corners onto box corners.
- kornia.geometry.transform.warp_affine(src, M, dsize, mode='bilinear', padding_mode='zeros', align_corners=True, fill_value=None)[source]#
Warp an image by a source→destination affine matrix in pixel coordinates.
out = warp_affine(src, M, dsize)takes images(B, C, H, W)and(B, 2, 3)affine matrices that map source pixels to destination pixels, and returns the(B, C, h, w)destination images fordsize = (h, w). A single(1, 2, 3)matrix serves every image of a non-empty batch. BuildMwithget_rotation_matrix2d(), or take the top two rowsM[:, :2]of the(B, 3, 3)matrix ofget_affine_matrix2d();invert_affine_transform()gives the matrix that warps back. To keep the input size, useaffine(), or pass an angle, a shift or a scale instead of a matrix torotate(),translate()orscale(); for a(B, 3, 3)homography, usewarp_perspective().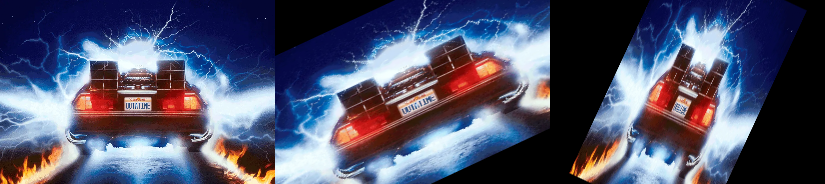
Each output pixel
(x, y)samples the source at:\[\text{dst}(x, y) = \text{src} \left( M^{-1}_{11} x + M^{-1}_{12} y + M^{-1}_{13} , M^{-1}_{21} x + M^{-1}_{22} y + M^{-1}_{23} \right )\]where \(M^{-1}\) is the inverse of the \(3 \times 3\) homogeneous extension of
M.- Convention:
See Conventions & Pitfalls for transform direction, pixel centres, normalized coordinates and
align_cornerssampling rules.Mis the source→destination pixel affine matrix(B, 2, 3)a one-pixel source axis is sampled like a longer one, so positions outside it get
padding_mode. Underalign_corners=True, wheregrid_samplealone would land them all on that pixel,'zeros'and'fill'read it as the first of two pixels, the second holding the padding (#6433)srcsets the dtype: a float32Mwith a float64srcsamples in float64, and a float64Mwith a float32srcraisesRuntimeErrora caller’s autocast region does not change the matrix arithmetic or the sampling grid, outside TorchScript (in the region, a
srcandMthat mix float32 and half dtypes run in float32)a zero output dimension returns an autograd-connected empty tensor; negative output dimensions raise
ValueError
- Parameters:
src (
Tensor) – input torch.Tensor of shape(B, C, H, W).M (
Tensor) – affine transformation of shape(B, 2, 3), or(1, 2, 3)for the whole batch.dsize (
tuple[int,int]) – size of the output image (height, width).mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'|'fill'. Default:"zeros"align_corners (
bool, optional) – mode for grid_generation. Default:Truefill_value (
Optional[Tensor], optional) – torch.Tensor of shape(C)or(1)that fills the padding area, or any shape that broadcasts to the output(B, C, h, w)without changing it, such as a per-sample(B, C, 1, 1)fill. Defaults to zeros. Default:None
- Return type:
- Returns:
the warped torch.Tensor with shape
(B, C, h, w), spatial sizes given bydsize.
See also
warp_perspective(): a(B, 3, 3)homography per image, for perspective warps.warp_affine3d(): the same warp for(B, C, D, H, W)volumes by(B, 3, 4)matrices.affine(): keeps the input size and also takes an unbatched(C, H, W)image.invert_affine_transform(): the destination→source matrix, to warp back.get_affine_matrix2d(): a(B, 3, 3)matrix from translation, rotation, scale and shear; pass itsM[:, :2].crop_by_transform_mat(): calls this warp for a(B, 2, 3)matrix after casting it to the image dtype, andwarp_perspective()for a(B, 3, 3)one.
Example
>>> img = torch.rand(1, 4, 5, 6)
>>> A = torch.eye(2, 3)[None]
>>> out = warp_affine(img, A, (4, 2), align_corners=True)
>>> print(out.shape)
torch.Size([1, 4, 4, 2])
Note
See a working example here.
- kornia.geometry.transform.warp_affine3d(src, M, dsize, flags='bilinear', padding_mode='zeros', align_corners=True)[source]#
Warp a volume by a source→destination 3x4 affine matrix in voxel coordinates.
out = warp_affine3d(src, M, dsize)takes volumes(B, C, D, H, W)and one(B, 3, 4)affine matrix per volume that maps source voxels(x, y, z)to destination voxels, and returns the(B, C, d, h, w)destination volumes fordsize = (d, h, w);flagsis the interpolation mode. Keep the defaultalign_corners=True: atFalsethe matrix is normalized for corner-aligned voxels whilegrid_samplereads half-voxel ones, so a translation oftvoxels moves the volumet * size / (size - 1)voxels along that axis (#4503). For a(B, 4, 4)homography, usewarp_perspective3d(); for images,warp_affine(); to keep the input size,affine3d().Warning
This API signature it is experimental and might suffer some changes in the future.
- Convention:
align_corners:
Trueby defaultpadding_mode:
'zeros'by defaultMhas the batch ofsrc: one matrix is not shared by a larger batchunder
align_corners=True, a one-voxel source axis is sampled like a longer one, so positions outside it getpadding_mode:'zeros'reads it as the first of two voxels, the second holding the padding (#6433)a caller’s autocast region does not change the matrix arithmetic or the sampling grid (there, a
srcandMthat mix float32 and half dtypes run in float32)an empty batch returns shape
(0, C, d, h, w)with gradients connected to both inputs even when a source spatial dimension is zeroa zero output dimension returns an autograd-connected empty tensor; negative output dimensions raise
ValueErrora nonempty batch requires positive source spatial dimensions for a nonempty output
- Parameters:
src (
Tensor) – input torch.Tensor of shape(B, C, D, H, W).M (
Tensor) – affine transformation matrix of shape(B, 3, 4).dsize (
tuple[int,int,int]) – size of the output image (depth, height, width).flags (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – mode for grid_generation. Default:True
- Returns:
the warped 3d torch.tensor with shape
(B, C, d, h, w), spatial sizes given bydsize.- Return type:
See also
warp_affine(): the 2D warp of images by(B, 2, 3)matrices.warp_perspective3d(): a(B, 4, 4)homography; its defaultalign_corners=Falseresamples even an identity.affine3d(): keeps the input size and accepts an unbatched(C, D, H, W)volume.get_projective_transform(): the(B, 3, 4)matrix of a rotation and a scale about a centre.crop_by_transform_mat3d(): calls this warp with the top three rows of a(B, 3, 4)or(B, 4, 4)matrix, and broadcasts a batch-1 matrix.
- kornia.geometry.transform.warp_image_tps(image, kernel_centers, kernel_weights, affine_weights, align_corners=False, padding_mode='zeros')[source]#
Warp images by a thin-plate spline that maps each output pixel to the input pixel it samples.
out = warp_image_tps(image, kernel_centers, kernel_weights, affine_weights)takes images(B, C, H, W)and a spline as inwarp_points_tps()(one per image, or a batch of 1 for all), applies the spline to the normalized coordinates of every output pixel and returns the(B, C, H, W)images bilinearly sampled there. The spline therefore maps output space to input space: to move control pointspoints_srcof the input ontopoints_dst, fitget_tps_transform(points_dst, points_src)and passpoints_dstaskernel_centers, with both point sets in normalized coordinates. For one global matrix, usewarp_perspective(); for random spline warps in an augmentation pipeline,RandomThinPlateSpline.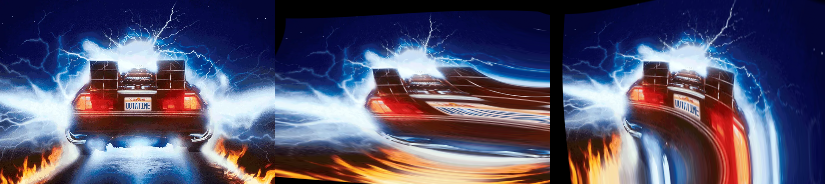
- Convention:
a
float16/bfloat16image with centers and weights of its dtype builds its grid and samples infloat32on every device and returns the input dtype: a half-precision grid is off by half a pixel or more at 256 pximage:
(B, C, H, W); the weights come fromget_tps_transform()called reversed,get_tps_transform(points_dst, points_src), andkernel_centersispoints_dst, the first argument of that call (see its Convention block);points_srcgives a wrong warp of the right shapeall control points live in the normalized
grid_sampleframe selected byalign_corners: the half-pixel \(x_{norm} = (2x+1)/W - 1\) at the defaultFalse, the corner-aligned \(x_{norm} = 2x/(W-1) - 1\) atTrue; values outside \([-1, 1]\) sample the padding. Pixel-space control points silently give a wrong warp of the right shapealign_corners:
Falseby default (the matrix warps default toTrue)for float32 points, a caller’s autocast region does not change the sampling positions, outside TorchScript (in the region, a mix of float32, float16 and bfloat16 points meets in float32, except that CPU and MPS autocast raise on a half
imageof a dtype other than the region’s)
- Parameters:
image (
Tensor) – input image torch.Tensor(B, C, H, W).kernel_centers (
Tensor) – kernel center points(B, K, 2).kernel_weights (
Tensor) – torch.Tensor of kernel weights(B, K, 2).affine_weights (
Tensor) – torch.Tensor of affine weights(B, 3, 2).align_corners (
bool, optional) – interpolation flag used by grid_sample. Default:Falsepadding_mode (
str, optional) – padding flag used by grid_sample. Default:"zeros"
- Return type:
- Returns:
warped image torch.Tensor
(B, C, H, W).
See also
get_tps_transform(): fits the spline; call it with the target points first for this warp.warp_points_tps(): applies the same spline to points.RandomThinPlateSpline: random spline warps, in an augmentation pipeline.elastic_transform2d(): a smoothed random displacement field instead of control points.
Example
>>> points_src = torch.rand(1, 5, 2)
>>> points_dst = torch.rand(1, 5, 2)
>>> image = torch.rand(1, 3, 32, 32)
>>> # note that we are getting the reverse transform: dst -> src
>>> kernel_weights, affine_weights = get_tps_transform(points_dst, points_src)
>>> warped_image = warp_image_tps(image, points_dst, kernel_weights, affine_weights)
- kornia.geometry.transform.warp_points_tps(points_src, kernel_centers, kernel_weights, affine_weights)[source]#
Move 2D points by a thin-plate spline given as kernel centres and weights.
warped = warp_points_tps(points_src, kernel_centers, kernel_weights, affine_weights)takes(B, N, 2)points and the(B, K, 2)kernel centres,(B, K, 2)kernel weights and(B, 3, 2)affine weights of a spline, and returns the(B, N, 2)warped points in the same frame, unclamped. With the weights ofget_tps_transform(points_src, points_dst), passpoints_srcaskernel_centers: that function centres the kernels there. In the weight tensors,[..., 0]holds the weights of the x transform and[..., 1]those of the y transform. To warp an image, usewarp_image_tps().- Convention:
points:
(B, N, 2)(or(B, K, 2)for kernel centers) in(x, y)order; no normalization is applied, and the output is in the same frame, not clampedkernel_centersmust be the first argument passed toget_tps_transform()(see its Convention block). Nothing checks this, and any other tensor of that shape, the second argument included, gives a wrong warp of the right shape. The right centres givekernel_weights.mT @ kernel_centersof zero up to round-off. A caller can assert that to catch the second argument, but it does not identify the centres, as a translated set passes it toofor float32 points, a caller’s autocast region does not change the result, outside TorchScript (in the region, a mix of float32, float16 and bfloat16 points meets in float32)
- Parameters:
- Return type:
- Returns:
The
(B, N, 2)torch.Tensor of warped source points, from applying the TPS transform.
See also
get_tps_transform(): fits the weights from point pairs.warp_image_tps(): applies a spline to every pixel of an image, in normalized coordinates.transform_points(): moves points by one(B, 3, 3)matrix instead.
Example
>>> points_src = torch.rand(1, 5, 2)
>>> points_dst = torch.rand(1, 5, 2)
>>> kernel_weights, affine_weights = get_tps_transform(points_src, points_dst)
>>> warped = warp_points_tps(points_src, points_src, kernel_weights, affine_weights)
>>> warped_correct = torch.allclose(warped, points_dst)
- kornia.geometry.transform.warp_grid(grid, src_homo_dst)[source]#
Warp a grid of 2D points by homographies, returning the coordinates without sampling an image.
warped = warp_grid(grid, src_homo_dst)applies the homographiessrc_homo_dstto every(x, y)point ofgridand returns the(N, H, W, 2)points after the homogeneous division, in the dtype ofsrc_homo_dst. It does not normalize: the points stay in the coordinates thatgridand the homography share, so a normalized grid fromcreate_meshgrid()and a normalized homography give positions thattorch.nn.functional.grid_sample()reads directly. To warp an image, usehomography_warp(), which builds such a grid, warps it with this function and samples the image.- Convention:
gridcoordinates:(x, y)(last dim), shape(1, H, W, 2)or(N, H, W, 2)src_homo_dstis the destination→source homography(1, 3, 3),(N, 3, 3)or(N, 1, 3, 3)only the
(1, H, W, 2)grid broadcasts over homography batches; a batched grid requires a matching batch ofNhomographiessrc_homo_dstis divided by a detached scale toward unit magnitude before the homogeneous division, as inwarp_perspective(), so a nonzero scalar multiple of it returns the same grid, except at grid points whose homogeneous coordinate is within1e-8of zero after that rescaling: those are left undivided, asconvert_points_from_homogeneous()does for points at infinitya caller’s autocast region does not change the grid, outside TorchScript
- Parameters:
- Return type:
- Returns:
the transformed grid of shape
(N, H, W, 2).- Raises:
ShapeError – If
gridis not(B, H, W, 2), orsrc_homo_dstis not(B, 3, 3)or(B, 1, 3, 3). A single(3, 3)homography needs a leading batch dimension.
See also
warp_grid3d(): the same for a 3D(x, y, z)grid and(N, 4, 4)homographies.homography_warp(): builds the grid, warps it with this function and samples the image.create_meshgrid(): the(1, H, W, 2)grid to pass in, in pixels or normalized.transform_points(): transform any(B, N, 2)point set by(B, 3, 3)matrices.
- kornia.geometry.transform.warp_grid3d(grid, src_homo_dst)[source]#
Warp a grid of 3D points by 4x4 homographies, returning the coordinates without sampling a volume.
warped = warp_grid3d(grid, src_homo_dst)applies the homographiessrc_homo_dstto every(x, y, z)point ofgridand returns the(N, D, H, W, 3)points after the homogeneous division, in the dtype ofsrc_homo_dst. It does not normalize or reorder: the last axis must already be(x, y, z), the order the homography andtorch.nn.functional.grid_sample()read, whereascreate_meshgrid3d()returns(d, x, y). To warp a volume, usehomography_warp3d(), which builds and reorders the grid, warps it with this function and samples the volume.- Convention:
gridcoordinates:(x, y, z)(last dim), shape(1, D, H, W, 3)or(N, D, H, W, 3)src_homo_dstis the destination→source homography(1, 4, 4),(N, 4, 4)or(N, 1, 4, 4)only the
(1, D, H, W, 3)grid broadcasts over homography batches; a batched grid requires a matching batch ofNhomographiessrc_homo_dstis divided by a detached scale toward unit magnitude before the homogeneous division, as inwarp_perspective(), so a nonzero scalar multiple of it returns the same grid, except at grid points whose homogeneous coordinate is within1e-8of zero after that rescaling: those are left undivided, asconvert_points_from_homogeneous()does for points at infinitya caller’s autocast region does not change the grid, outside TorchScript
- Parameters:
- Return type:
- Returns:
the transformed grid of shape
(N, D, H, W, 3).- Raises:
ShapeError – If
gridis not(B, D, H, W, 3), orsrc_homo_dstis not(B, 4, 4)or(B, 1, 4, 4). A single(4, 4)homography needs a leading batch dimension.
See also
warp_grid(): the same for a 2D(x, y)grid and(N, 3, 3)homographies.homography_warp3d(): builds and reorders the grid, warps it with this function and samples the volume.create_meshgrid3d(): a grid in(d, x, y)order, to reorder before passing it in.
- kornia.geometry.transform.remap(image, map_x, map_y, mode='bilinear', padding_mode='zeros', align_corners=None, normalized_coordinates=False)[source]#
Sample an image at per-pixel source coordinates given as an x map and a y map.
out = remap(image, map_x, map_y)takes images(B, C, H, W)and two(B, h, w)maps that hold, for every output pixel, the source columnxand rowyto sample, and returns(B, C, h, w). The maps are absolute pixel coordinates, not displacements, so the identity maps are the two channels ofcreate_meshgrid()withnormalized_coordinates=False; withnormalized_coordinates=Truethey are the \([-1, 1]\) coordinates oftorch.nn.functional.grid_sample(). Maps of batch 1 serve every image. With pixel maps, passalign_corners=True: the default resamples even an identity map. For a warp given by a matrix, usewarp_affine()orwarp_perspective().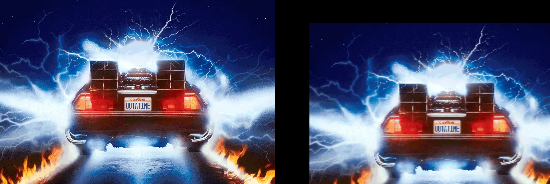 \[\text{dst}(x, y) = \text{src}(map_x(x, y), map_y(x, y))\]
- Convention:
align_corners:
Noneby default, resolved toFalseinternallypixel maps are normalized with the
align_corners=Trueconvention whatever flag reachesgrid_sample, so atFalse/Noneeven an identity map resamples the image; passalign_corners=True(#4504)the output spatial size comes from the maps; a zero map axis returns an autograd-connected empty output, including when the matching source axis is empty
- Parameters:
image (
Tensor) – the torch.Tensor to remap with shape(B, C, H, W). Where C is the number of channels.map_x (
Tensor) – the source x coordinate (column) to sample for each output pixel, with shape(B, h, w)or(1, h, w); in pixels unlessnormalized_coordinates=True.map_y (
Tensor) – the source y coordinate (row) to sample for each output pixel, with the shape ofmap_x.mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
Optional[bool], optional) – mode for grid_generation. Default:Nonenormalized_coordinates (
bool, optional) – whether the input coordinates are normalized in the range of [-1, 1]. Default:False
- Return type:
- Returns:
the sampled images
(B, C, h, w), with the spatial size of the maps.
See also
warp_perspective(): warp by a(B, 3, 3)pixel homography instead of maps.warp_grid(): the positions a homography gives, as a grid whose two channels are maps.create_meshgrid(): the identity maps, to offset or transform.warp_image_tps(): a smooth warp from thin-plate-spline control points.
Example
>>> import torch
>>> from kornia.geometry import create_meshgrid
>>> grid = create_meshgrid(2, 2, False)  # 1x2x2x2
>>> grid += 1  # apply offset in both directions
>>> input = torch.ones(1, 1, 2, 2)
>>> remap(input, grid[..., 0], grid[..., 1], align_corners=True)   # 1x1x2x2
tensor([[[[1., 0.],
          [0., 0.]]]])
- kornia.geometry.transform.homography_warp(patch_src, src_homo_dst, dsize, mode='bilinear', padding_mode='zeros', align_corners=False, normalized_coordinates=True, normalized_homography=True)[source]#
Warp an image by a destination→source homography in normalized
[-1, 1]coordinates.out = homography_warp(patch_src, src_homo_dst, dsize)takes images(N, C, H, W)and one(N, 3, 3)homography per image that maps destination points to source points in normalized \([-1, 1]\) coordinates, and returns the(N, C, h, w)destination images fordsize = (h, w). In normalized coordinates an identity maps the whole source onto the whole output, so a differentdsizeresizes the image. For a source→destination homography in pixel coordinates, asget_perspective_transform(),find_homography_dlt()andRANSACreturn it, usewarp_perspective(). Passed here unchanged, such a homography is read as a normalized destination→source one, which typically samples outside the source, so the output is mostly or entirely zeros (with the defaultpadding_mode="zeros").normalized_coordinates=Falsereads the same destination→source homography in pixels, andnormalized_homography=Falseinstead hands a pixel source→destination homography towarp_perspective()with this function’salign_corners=Falsedefault, which for a pixel homography samples the same positions asalign_corners=True(seealign_cornersbelow), up to which pixelmode="nearest"takes for a sample exactly halfway between two pixels.- Convention:
See Conventions & Pitfalls for homography direction, normalized coordinates and
align_cornerssampling rules.src_homo_dstis the destination→source homography(N, 3, 3)whennormalized_homography=True(default), in normalized \([-1, 1]\) coordinates by default (normalized_coordinates=True). Withnormalized_coordinates=Falseit is in pixel coordinates, pixel centres at integers: it maps the pixel(x, y)of thedsizeoutput to the source pixel it samples, so an identity returns the top-leftdsizewindow of the inputwith
normalized_homography=Falseit is consumed as the source→destination pixel homography, exactly likewarp_perspective(), andnormalized_coordinatesis ignoredsrc_homo_dsthas the batch ofpatch_src: a(1, 3, 3)homography is not shared by a larger batcha
float16/bfloat16patch with a homography of its dtype builds its grid and samples infloat32on every device and returns the input dtypewith
normalized_coordinates=Falsethe pixel grid is warped and normalized in at least float32, also under a half default dtype and in a caller’s autocast region, and then cast to the homography’s dtypewith
normalized_coordinates=Truea caller’s autocast region does not change the sampling grid, outside TorchScript (in the region, a patch and homography that mix float32 and half dtypes run in float32)align_corners:
Falseby default (differs fromwarp_perspective()). A pixel homography samples the same positions under both settings, which then differ only inpadding_mode="reflection"and, withmode="nearest", in which pixel a sample exactly halfway between two pixels takes. A normalized homography reads the whole \([-1, 1]\) range of a one-pixel source axis as that pixel underalign_corners=Truenegative output dimensions raise
ValueError
- Parameters:
patch_src (
Tensor) – The image or torch.Tensor to warp. Should be from source of shape(N, C, H, W).src_homo_dst (
Tensor) – The homography or torch.stack of homographies of shape(N, 3, 3)— destination to source whennormalized_homography=True(default), source to destination (pixel) whennormalized_homography=False.mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – interpolation flag. Default:Falsenormalized_coordinates (
bool, optional) – whethersrc_homo_dstis in normalized \([-1, 1]\) coordinates (True) or in pixel coordinates (False). Ignored whennormalized_homography=False. Default:Truenormalized_homography (
bool, optional) – whethersrc_homo_dstis a destination→source homography in the coordinatesnormalized_coordinatesselects (True, default) or a pixel source→destination homography (False). Default:True
- Return type:
- Returns:
the warped images
(N, C, h, w), sampled at the source locations of the destination pixels.
See also
warp_perspective(): takes the source→destination homography in pixel coordinates.HomographyWarper: the module form, which can precompute the sampling grid for repeated warps.homography_warp3d(): the same warp for(N, C, D, H, W)volumes by(N, 4, 4)homographies.warp_grid(): the warped sampling grid alone, without sampling the image.normalize_homography(): convert a pixel source→destination homography to normalized coordinates, with this function’salign_corners(it defaults toTruethere); invert the result for this function.
Example
>>> input = torch.rand(1, 3, 32, 32)
>>> homography = torch.eye(3).view(1, 3, 3)
>>> output = homography_warp(input, homography, (32, 32))
Example
>>> img = torch.rand(1, 4, 5, 6)
>>> H = torch.eye(3)[None]
>>> out = homography_warp(img, H, (4, 2), align_corners=True, normalized_homography=False)
>>> print(out.shape)
torch.Size([1, 4, 4, 2])
- kornia.geometry.transform.homography_warp3d(patch_src, src_homo_dst, dsize, mode='bilinear', padding_mode='zeros', align_corners=False, normalized_coordinates=True)[source]#
Warp a volume by a destination→source 3D homography in normalized coordinates.
out = homography_warp3d(patch_src, src_homo_dst, dsize)takes volumes(N, C, D, H, W)and one(N, 4, 4)homography per volume that maps destination points(x, y, z)to source points in normalized \([-1, 1]\) coordinates, and returns the(N, C, d, h, w)destination volumes fordsize = (d, h, w). In normalized coordinates, passalign_corners=True: the normalized grid is always corner-aligned, so at the defaultFalseeven an identity resamples the volume (#4503). For a source→destination homography in voxel coordinates, usewarp_perspective3d()withalign_corners=True, which at its defaultFalseresamples even an identity for the same reason, or pass the inverse of that homography here withnormalized_coordinates=False. This function has nonormalized_homographyswitch.- Convention:
input:
(N, C, D, H, W);dsizeis the output size(d, h, w)src_homo_dstis the destination→source homography(N, 4, 4), in normalized \([-1, 1]\) coordinates by default (normalized_coordinates=True), and acts on(x, y, z, 1)column vectors:xindexesW,yindexesH,zindexesD. That is the ordertorch.nn.functional.grid_sample()reads a 5-D grid in, and the orderwarp_grid3d()takes. kornia’s own 3-D grids and pixel coordinates are(d, x, y)(seecreate_meshgrid3d()), so the sampling grid is reordered here before the homography is applied; nothing else in the module changes its orderwith
normalized_coordinates=Falsesrc_homo_dstis in voxel coordinates, voxel centres at integers, in the same(x, y, z)order: it maps the voxel(x, y, z)of thedsizeoutput to the source voxel it samples, so an identity returns thedsizewindow of the input that starts at voxel(0, 0, 0). The warped voxel grid is normalized with the source size underalign_cornersbeforegrid_samplewith
normalized_coordinates=Falsethe voxel grid is warped and normalized in at least float32, also under a half default dtype and in a caller’s autocast region, and then cast to the homography’s dtypewith
normalized_coordinates=Truea caller’s autocast region does not change the sampling grid, outside TorchScript (in the region, a patch and homography that mix float32 and half dtypes run in float32)align_corners:
Falseby default. Withnormalized_coordinates=False, a voxel homography samples the same positions under both settings, which then differ only inpadding_mode="reflection"and, withmode="nearest", in which voxel a sample exactly halfway between two voxels takespadding_mode:
'zeros'by defaultnegative output dimensions raise
ValueError
- Parameters:
patch_src (
Tensor) – The image or torch.Tensor to warp. Should be from source of shape(N, C, D, H, W).src_homo_dst (
Tensor) – The homography or torch.stack of homographies from destination to source of shape(N, 4, 4).mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – interpolation flag. Default:Falsenormalized_coordinates (
bool, optional) – whethersrc_homo_dstis in normalized \([-1, 1]\) coordinates (True) or in voxel coordinates (False). Default:True
- Return type:
- Returns:
the warped volumes
(N, C, d, h, w), sampled at the source locations of the destination voxels.
See also
homography_warp(): the 2D warp of images, which also has anormalized_homographyswitch.warp_perspective3d(): takes the source→destination homography in voxel coordinates.warp_grid3d(): the warped sampling grid alone, in(x, y, z)order.create_meshgrid3d(): kornia’s(d, x, y)grid, which this function reorders.
Example
>>> input = torch.rand(1, 3, 8, 32, 32)
>>> homography = torch.eye(4).view(1, 4, 4)
>>> output = homography_warp3d(input, homography, (8, 32, 32))
Image 2D transforms#
Rotate, shift, zoom or shear an image by parameters (rotate(), translate(), scale(),
shear()), or warp it by an affine matrix (affine()), at the input size; change the size with
resize(), rescale() or resize_to_be_divisible(). Mirror or turn it by reversing axes, without
interpolation (hflip(), vflip(), rot180()); deform it by a smoothed displacement field
(elastic_transform2d()); blur and resize it by one pyramid level (pyrdown(), pyrup()), or build a
Gaussian or Laplacian pyramid (build_pyramid(), build_laplacian_pyramid(), with the integer helpers
is_powerof_two() and find_next_powerof_two()).
- kornia.geometry.transform.affine(tensor, matrix, mode='bilinear', padding_mode='zeros', align_corners=True)[source]#
Warp an image by a source→destination affine matrix, keeping its size.
out = affine(tensor, matrix)warps(C, H, W)or(B, C, H, W)images by(B, 2, 3)source→destination pixel affine matrices and returns them at their own size:warp_affine()withdsize=(H, W), plus an unbatched image and broadcasting. One matrix,(1, 2, 3)or(2, 3), serves every image of a batch, and one image, unbatched or of batch 1, is warped by every matrix, so it returns(B, C, H, W)forB > 1matrices. For another output size, usewarp_affine(); to build the matrix from an angle, a shift, a scale and a shear, useAffine.
- Convention:
See Conventions & Pitfalls for the
align_cornersdefaults and sampling rules.matrixis the source→destination pixel affine matrix(B, 2, 3); an unbatched(2, 3)matrix is read as(1, 2, 3).
- Parameters:
tensor (
Tensor) – The image tensor to be warped in shapes of(C, H, W)or(B, C, H, W).matrix (
Tensor) – The 2x3 affine transformation matrices, with shape(B, 2, 3), or one(2, 3)matrix.mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – interpolation flag. Default:True
- Return type:
- Returns:
The warped image with the same shape as the input, except that one image warped by
B > 1matrices returns(B, C, H, W).
See also
warp_affine(): the same warp with an explicit output size, for batched images.affine3d(): the same for volumes, by(B, 3, 4)matrices.Affine: a module built from an angle, a translation, a scale and a shear instead of a matrix.rotate(): rotate about the centre without building the matrix.
Example
>>> img = torch.rand(1, 2, 3, 5)
>>> aff = torch.eye(2, 3)[None]
>>> out = affine(img, aff)
>>> print(out.shape)
torch.Size([1, 2, 3, 5])
- kornia.geometry.transform.rotate(tensor, angle, center=None, mode='bilinear', padding_mode='zeros', align_corners=True)[source]#
Rotate an image counter-clockwise by an angle in degrees about its centre or a given point.
out = rotate(tensor, angle)rotates(C, H, W)or(B, C, H, W)images byangledegrees,(B,)or one value for all, counter-clockwise as displayed, aboutcenter((B, 2)(x, y)pixels, by default the image centre((W - 1) / 2, (H - 1) / 2)), and returns them at their size; the uncovered corners are padded bypadding_mode. For a stored angle, useRotate; for volumes,rotate3d(); for the matrix, to compose or reuse it,get_rotation_matrix2d().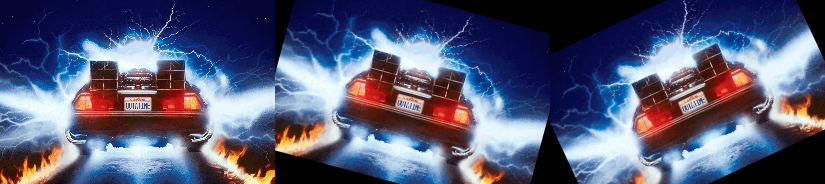
- Convention:
centeris(x, y)in pixels, origin at top-left; defaults to the tensor centerpositive
anglerotates counter-clockwise as displayed (y-down image axes)
- Parameters:
tensor (
Tensor) – The image tensor to be warped in shapes of(C, H, W)or(B, C, H, W).angle (
Tensor) – The angle through which to rotate. The tensor must have a shape of (B), where B is batch size.center (
Optional[Tensor], optional) – The center through which to rotate. The tensor must have a shape of (B, 2), where B is batch size and last dimension contains cx and cy. Default:Nonemode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – interpolation flag. Default:True
- Return type:
- Returns:
The rotated tensor with shape as input.
See also
Rotate: the module form, with the angle stored.rotate3d(): rotate volumes by an axis-angle vector; a positivezangle turns clockwise on screen (3D rotations are right-handed by design).get_rotation_matrix2d(): the(B, 2, 3)matrix of this rotation, with a scale.rot180(): a half turn by flipping both axes, without interpolation.
Note
See a working example here.
Example
>>> img = torch.rand(1, 3, 4, 4)
>>> angle = torch.tensor([90.])
>>> out = rotate(img, angle)
>>> print(out.shape)
torch.Size([1, 3, 4, 4])
- kornia.geometry.transform.translate(tensor, translation, mode='bilinear', padding_mode='zeros', align_corners=True)[source]#
Shift an image by a translation in pixels.
out = translate(tensor, translation)shifts(C, H, W)or(B, C, H, W)images bytranslation(B, 2),(dx, dy)in pixels, a positivedxto the right and a positivedydown, and returns them at their size; a fractional shift interpolates, and the uncovered border is padded bypadding_mode. One translation,(1, 2)or(2,), serves every image of a batch, and one image, unbatched or of batch 1, is shifted by every translation. For a stored translation, useTranslate; for the matrix,get_translation_matrix2d().
- Convention:
translationis(dx, dy)in pixels
- Parameters:
tensor (
Tensor) – The image tensor to be warped in shapes of(C, H, W)or(B, C, H, W).translation (
Tensor) – tensor containing the amount of pixels to translate in the x and y direction. The tensor must have a shape of (B, 2), where B is batch size, last dimension contains dx dy, or (2,) for one translation.mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – interpolation flag. Default:True
- Return type:
- Returns:
The translated tensor with shape as input, except that one image shifted by
B > 1translations returns(B, C, H, W).
See also
Translate: the module form, with the translation stored.get_translation_matrix2d(): the(B, 3, 3)matrix of this shift.affine(): warp by any affine matrix at the input size.
Example
>>> img = torch.rand(1, 3, 4, 4)
>>> translation = torch.tensor([[1., 0.]])
>>> out = translate(img, translation)
>>> print(out.shape)
torch.Size([1, 3, 4, 4])
- kornia.geometry.transform.scale(tensor, scale_factor, center=None, mode='bilinear', padding_mode='zeros', align_corners=True)[source]#
Zoom an image about its centre by a scale factor, keeping its size.
out = scale(tensor, scale_factor)scales the content of(C, H, W)or(B, C, H, W)images byscale_factor,(B,)for both axes or(B, 2)as(sx, sy), aboutcenter((B, 2)(x, y)pixels, by default the image centre), and returns them at their size: a factor above 1 zooms in and crops, one below 1 shrinks the content and pads the border. To change the image size instead, userescale()orresize(); for a stored factor,Scale.
- Convention:
centeris(x, y)in pixels, origin at top-left; defaults to the tensor center
- Parameters:
tensor (
Tensor) – The image tensor to be warped in shapes of(C, H, W)or(B, C, H, W).scale_factor (
Tensor) – The scale factor apply. The tensor must have a shape of (B) or (B, 2), where B is batch size. If (B), isotropic scaling will perform. If (B, 2), x-y-direction specific scaling will perform.center (
Optional[Tensor], optional) – The center through which to scale. The tensor must have a shape of (B, 2), where B is batch size and last dimension contains cx and cy. Default:Nonemode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – interpolation flag. Default:True
- Return type:
- Returns:
The scaled tensor with the same shape as the input.
See also
Scale: the module form, with the factor stored.rescale(): change the image size by a factor, given height first.get_rotation_matrix2d(): the matrix of this scaling, with a zero angle.
Example
>>> img = torch.rand(1, 3, 4, 4)
>>> scale_factor = torch.tensor([[2., 2.]])
>>> out = scale(img, scale_factor)
>>> print(out.shape)
torch.Size([1, 3, 4, 4])
- kornia.geometry.transform.shear(tensor, shear, mode='bilinear', padding_mode='zeros', align_corners=False)[source]#
Shear an image by raw shear factors about pixel (0, 0).
out = shear(tensor, shear)shears(C, H, W)or(B, C, H, W)images byshear(B, 2), the raw factors(shx, shy)described below, and returns them at their size. One pair of factors,(1, 2)or(2,), serves every image of a batch, and one image, unbatched or of batch 1, is sheared by every pair. For shear angles in radians, useAffine, about the image centre by default, orget_shear_matrix2d(), about a centre you pass; both shear by the negative tangent, so values belowpi / 2in magnitude shear the other way there. For stored factors, useShear.
- Convention:
shearis a pair of raw factors(shx, shy)about pixel(0, 0):x_out = x + shx * y,y_out = y + shy * x(x right, y down).Known defect:
Affinereads itsshearas angles in radians about the image centre and shears by their negative tangent, so the same tensor shears the other way there while its values stay belowpi / 2in magnitude (#5661).align_corners:
Falseby default (differs from the other 2D affine warps and fromShear, which default toTrue)
- Parameters:
tensor (
Tensor) – The image tensor to be skewed with shape of(C, H, W)or(B, C, H, W).shear (
Tensor) – tensor containing raw shear factors in the x and y direction about pixel (0, 0). The tensor must have a shape of (B, 2), where B is batch size, last dimension contains shx shy, or (2,) for one pair.mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – interpolation flag. Default:False
- Return type:
- Returns:
The skewed tensor with shape same as the input, except that one image sheared by
B > 1pairs of factors returns(B, C, H, W).
See also
Shear: the module form, which defaults toalign_corners=True.get_shear_matrix2d(): a shear given as angles in radians about a centre, the reading ofAffine.affine(): warp by any affine matrix at the input size.
Example
>>> img = torch.rand(1, 3, 4, 4)
>>> shear_factor = torch.tensor([[0.5, 0.0]])
>>> out = shear(img, shear_factor)
>>> print(out.shape)
torch.Size([1, 3, 4, 4])
- kornia.geometry.transform.hflip(input)[source]#
Mirror images left to right by reversing the width axis.
out = hflip(input)reverses the last axis of(*, W)tensors, the width of(*, H, W)images, and returns the same shape. To flip top to bottom, usevflip(); for a half turn,rot180(); for random flips in an augmentation pipeline,RandomHorizontalFlip.
- Convention:
flips the last dimension (dim
-1); accepts any rank \(\geq 1\) (rank 0 is outside the contract)
- Parameters:
input (
Tensor) – input torch.Tensor.- Return type:
- Returns:
The horizontally flipped image torch.Tensor, with the shape of the input.
See also
Hflip: the module form.vflip(): reverses the height axis instead.rot180(): reverses both axes.RandomHorizontalFlip: flips with a probability, in an augmentation pipeline.
- kornia.geometry.transform.vflip(input)[source]#
Flip images top to bottom by reversing the height axis.
out = vflip(input)reverses the second-to-last axis of(*, H, W)tensors and returns the same shape. To mirror left to right, usehflip(); for a half turn,rot180(); for random flips in an augmentation pipeline,RandomVerticalFlip.
- Convention:
flips along the height axis (the second-to-last dimension)
requires rank ≥ 2 (operates on dim
-2): unbatched(H, W)/(C, H, W)or batched(*, C, H, W)all work
- Parameters:
input (
Tensor) – input torch.Tensor.- Return type:
- Returns:
The vertically flipped image torch.Tensor, with the shape of the input.
See also
Vflip: the module form.hflip(): reverses the width axis instead.rot180(): reverses both axes.RandomVerticalFlip: flips with a probability, in an augmentation pipeline.
- kornia.geometry.transform.rot180(input)[source]#
Turn images by 180 degrees by reversing the height and width axes.
out = rot180(input)reverses the last two axes of(*, H, W)tensors and returns the same shape: the image turned by a half turn, exactly, without the interpolation ofrotate(). For any other angle, or a turn about another centre, userotate(); for the module form,Rot180.
- Convention:
- kornia.geometry.transform.resize(input, size, interpolation='bilinear', align_corners=None, side='short', antialias=False)[source]#
Resize an image to a given size, or one side to a given length keeping the aspect ratio.
out = resize(input, size)resamples the last two dimensions of(*, H, W)tensors tosize = (h, w)withtorch.nn.functional.interpolate()and returns(*, h, w). Anintsize sets the length of one side and keeps the aspect ratio, truncating the other side to an integer: the shorter side by default, or the longer side, the height or the width withside='long','vert'or'horz'.antialias=Trueblurs with a Gaussian before downscaling. To scale by a factor, userescale(); to zoom the content and keep the size,scale().
- Convention:
See Conventions & Pitfalls for sampling and
align_cornersconventions. When resizing camera images, see camera and world conventions for matching intrinsics scaling.input:
(*, H, W);sizeis(h, w)align_corners:
Noneby default (followstorch.nn.functional.interpolate; notewarp_perspective()/rotate()defaultTrue)sideresizing preserves aspect ratio using the named side
- Parameters:
input (
Tensor) – The image tensor to resize, with shape(*, H, W);*means any number of dimensions.size (
Union[int,Tuple[int,int]]) – Desired output size. If size is a sequence like (h, w), output size will be matched to this. If size is an int, the side thatsidenames will be matched to this number; with the defaultside='short', if height > width, the image will be rescaled to (size * height / width, size)interpolation (
str, optional) – algorithm used for upsampling:'nearest'|'nearest-exact'|'bilinear'|'bicubic'|'area'. Default:"bilinear"align_corners (
Optional[bool], optional) – interpolation flag. Default:Noneside (
str, optional) – Corresponding side ifsizeis an integer. Can be one of'short','long','vert', or'horz'. Default:"short"antialias (
bool, optional) – if True, then image will be filtered with Gaussian before downscaling. No effect for upscaling. Default:False
- Return type:
- Returns:
The resized tensor with the shape as the specified size.
See also
Resize: the module form, with the size stored.rescale(): the output size as a factor of the input size.resize_to_be_divisible(): the nearest size whose sides are multiples of a factor.scale(): zoom the content about the centre and keep the size.crop_and_resize(): resamples a box of each image, not the whole image, to a fixed size.
Example
>>> img = torch.rand(1, 3, 4, 4)
>>> out = resize(img, (6, 8))
>>> print(out.shape)
torch.Size([1, 3, 6, 8])
- kornia.geometry.transform.resize_to_be_divisible(input, divisible_factor, interpolation='bilinear', align_corners=None, side=None, antialias=False)[source]#
Resize an image so that its height and width are multiples of a factor.
out = resize_to_be_divisible(input, divisible_factor)resizes(*, H, W)tensors withresize()to the nearest multiples ofdivisible_factor, at leastdivisible_factorfor a positive side, and returns(*, h, w); an empty side stays empty. A side halfway between two multiples rounds as Python’sround()does, to an even quotient, so with a factor of 4 both 6 and 10 become 8.sideis deprecated and has no effect. For a given size, useresize().- Convention:
- Parameters:
input (torch.Tensor) – Input tensor to be resized.
divisible_factor (int) – The factor to which the image should be divisible.
interpolation (str, optional) – Interpolation flag. Defaults to “bilinear”. Default:
"bilinear"align_corners (Optional[bool], optional) – whether to align the corners of the input and output. Defaults to None. Default:
Noneside (str, optional) – Deprecated and ignored. Both sides are rounded independently to a multiple of
divisible_factor. In eager mode, any explicit non-None value emits aDeprecationWarning. Defaults to None. This argument will be removed in a future release. Default:Noneantialias (bool, optional) – If True, then image will be filtered with Gaussian before downscaling. Defaults to False. Default:
False
- Returns:
The resized tensor.
- Return type:
- Raises:
TypeError – If
inputis not a tensor.ValueError – If
inputhas fewer than two dimensions, ordivisible_factoris not a positive integer.
- kornia.geometry.transform.rescale(input, factor, interpolation='bilinear', align_corners=None, antialias=False)[source]#
Resize an image by a scale factor per side, given height first.
out = rescale(input, factor)resizes(*, H, W)tensors withresize()to(int(H * factor_h), int(W * factor_w)), truncating, and returns(*, h, w).factoris onefloatfor both sides or a pair(factor_h, factor_w), height first, unlike the(sx, sy)ofscale(); a singleintraisesTypeError. To set the output size directly, useresize(); for a stored factor,Rescale.
- Convention:
factoris(factor_h, factor_w)when a pair — height first (contrastscale(), whosescale_factoris x-first)delegates to
resize()after convertingfactorto an outputsizeONNX: an export with a dynamic height or width keeps it dynamic for the
'nearest','bilinear'and'bicubic'modes withoutantialias; the other modes keep the output size of the traced input. The exported graph computes the size in float32, which can be one pixel off eager whenfactoris not a power of two (0.7at a side of 90 gives 63, eager 62)
- Parameters:
input (
Tensor) – The image tensor to be scale with shape of(*, H, W).factor (
Union[float,Tuple[float,float]]) – Desired scaling factor as(factor_h, factor_w)— height first. If a single float, the value is used for both height and width (anintraisesTypeError).interpolation (
str, optional) – algorithm used for upsampling:'nearest'|'nearest-exact'|'bilinear'|'bicubic'|'area'. Default:"bilinear"align_corners (
Optional[bool], optional) – interpolation flag. Default:Noneantialias (
bool, optional) – if True, then image will be filtered with Gaussian before downscaling. No effect for upscaling. Default:False
- Return type:
- Returns:
The rescaled tensor with the shape as the specified size.
See also
Example
>>> img = torch.rand(1, 3, 4, 4)
>>> out = rescale(img, (2, 3))
>>> print(out.shape)
torch.Size([1, 3, 8, 12])
- kornia.geometry.transform.elastic_transform2d(image, noise, kernel_size=(63, 63), sigma=(32.0, 32.0), alpha=(1.0, 1.0), align_corners=False, mode='bilinear', padding_mode='zeros')[source]#
Deform images by a displacement field smoothed from noise, as described in [SSP03].
out = elastic_transform2d(image, noise)takes images(B, C, H, W)and a noise field(B, 2, H, W), smooths each channel of the noise with a Gaussian ofkernel_sizeandsigma, scales it byalphaand returns the(B, C, H, W)images sampled at the displaced pixels. The displacements are in the normalized \([-1, 1]\) coordinates ofgrid_sample: an x displacement of 1 moves a sample by \(W / 2\) pixels at the defaultalign_corners=Falseand by \((W - 1) / 2\) atTrue, and a y displacement likewise by the height. One Gaussian and onealphaserve the whole batch. For random fields in an augmentation pipeline, useRandomElasticTransform; for a smooth warp set by control points,warp_image_tps().
- Convention:
a
float16/bfloat16image with a noise field of its dtype builds its grid and samples infloat32on every device and returns the input dtype: a half-precision grid is off by half a pixel or more at 256 pximage:
(B, C, H, W);noise:(B, 2, H, W)with channel 0 the x- and channel 1 the y-displacement of the sampling grid (positive x-noise shifts image content left)displacements are smoothed with a Gaussian (
kernel_size,sigma) and scaled byalpha;kernel_sizeandsigmaare(y, x)pairs, butalphais(x, y)align_corners:
Falseby default (the matrix warps default toTrue); zeronoiseis an identity under either settingcoordinates displaced outside the image are filled by
padding_modeas ingrid_sample: zeros, the edge value, or the reflected imagea caller’s autocast region does not change the displacement field or the grid, and the result stays in the dtype of
image. Undertorch.compileon MPS it still changes the field: a convolution under the guard raises there, so the smoothing runs in the region’s dtype
- Parameters:
image (
Tensor) – Input image to be transformed with shape(B, C, H, W).noise (
Tensor) – Noise image used to spatially transform the input image. Same resolution as the input image with shape(B, 2, H, W). The coordinates order it is expected to be in x-y.kernel_size (
Tuple[int,int], optional) – the size of the Gaussian kernel, in the y and x directions, respectively; both odd. Default:(63, 63)sigma (
Union[Tuple[float,float],Tensor], optional) – The standard deviation of the Gaussian in the y and x directions, respectively, as a pair or a(2,)tensor. Larger sigma results in smaller pixel displacements. Default:(32.0, 32.0)alpha (
Union[Tuple[float,float],Tensor], optional) – The scaling factor that controls the intensity of the deformation in the x and y directions, respectively, as a pair or a(2,)tensor. Default:(1.0, 1.0)align_corners (
bool, optional) – Interpolation flag used bygrid_sample. Default:Falsemode (
str, optional) – Interpolation mode used bygrid_sample. Either'bilinear'or'nearest'. Default:"bilinear"padding_mode (
str, optional) – The padding used bygrid_sample. Either'zeros','border'or'reflection'. Default:"zeros"
- Return type:
- Returns:
the elastically transformed input image with shape
(B, C, H, W).
See also
RandomElasticTransform: draws uniform noise in \([-1, 1]\) for each call and applies it with probabilityp, in an augmentation pipeline.warp_image_tps(): a smooth deformation set by control-point pairs.remap(): samples an image at per-pixel coordinates given directly.
Example
>>> image = torch.rand(1, 3, 5, 5)
>>> noise = torch.rand(1, 2, 5, 5, requires_grad=True)
>>> image_hat = elastic_transform2d(image, noise, (3, 3))
>>> image_hat.mean().backward()
>>> image = torch.rand(1, 3, 5, 5)
>>> noise = torch.rand(1, 2, 5, 5)
>>> sigma = torch.tensor([4., 4.], requires_grad=True)
>>> image_hat = elastic_transform2d(image, noise, (3, 3), sigma)
>>> image_hat.mean().backward()
>>> image = torch.rand(1, 3, 5, 5)
>>> noise = torch.rand(1, 2, 5, 5)
>>> alpha = torch.tensor([16., 32.], requires_grad=True)
>>> image_hat = elastic_transform2d(image, noise, (3, 3), alpha=alpha)
>>> image_hat.mean().backward()
- kornia.geometry.transform.pyrdown(input, border_type='reflect', align_corners=False, factor=2.0)[source]#
Blur images with the 5x5 pyramid kernel and downsample them by a factor, one pyramid level down.
out = pyrdown(input)takes images(B, C, H, W), blurs them with the 5x5 binomial kernel and resizes them bilinearly to(B, C, floor(H / factor), floor(W / factor)), half the size at the defaultfactor=2.0. It resamples bilinearly where OpenCV’spyrDownkeeps every second pixel, and rounds an odd side down where OpenCV rounds it up. For the step up, usepyrup(); for every level at once,build_pyramid(); to keep every second pixel of a blurred map,blur_pool2d().
- Convention:
input:
(B, C, H, W)output spatial size is
floor(side / factor)per dimension (\(5 \times 5 \to 2 \times 2\) at the defaultfactor=2.0— note OpenCV’spyrDownrounds up instead)Dynamo ONNX uses float32 reciprocal-scale arithmetic for dynamic sides, which can differ from eager by one pixel for some fractional factors (for example, side 33 and factor 1.1)
border_type:
'reflect'by default (blur before downsample), including short positive axes; the resized output must still have at least one pixel along each axisalign_corners:
Falseby default
- Parameters:
input (
Tensor) – the torch.Tensor to be downsampled.border_type (
str, optional) – the padding mode to be applied before convolving. The expected modes are:'constant','reflect','replicate'or'circular'. Default:"reflect"align_corners (
bool, optional) – interpolation flag. Default:Falsefactor (
float, optional) – the downsampling factor Default:2.0
- Return type:
- Returns:
the downsampled torch.Tensor.
See also
PyrDown: the module form.pyrup(): one level up, to twice the size.build_pyramid(): the list of levels from repeatedpyrdowncalls.blur_pool2d(): a zero-padded binomial blur sampled at a stride, from pixel 0;blur_pool2d(x, 5, 2)blurs with this kernel and returnsceil(H / 2)rows.
Examples
>>> input = torch.arange(16, dtype=torch.float32).reshape(1, 1, 4, 4)
>>> pyrdown(input, align_corners=True)
tensor([[[[ 3.7500,  5.2500],
          [ 9.7500, 11.2500]]]])
- kornia.geometry.transform.pyrup(input, border_type='reflect', align_corners=False)[source]#
Upsample images to twice their size and blur them with the 5x5 pyramid kernel, one pyramid level up.
out = pyrup(input)takes images(B, C, H, W), resizes them bilinearly to(B, C, H * 2, W * 2)and then blurs them with the 5x5 binomial kernel; it has nofactor. Withpyrdownit builds the levels ofbuild_laplacian_pyramid(). For the step down, usepyrdown(); to change the size without blurring,resize().
- Convention:
input:
(B, C, H, W)output spatial size is exactly doubled per dimension (no
factorparameter, unlikepyrdown(); \(3 \times 3 \to 6 \times 6\))border_type:
'reflect'by default (blur after upsample)align_corners:
Falseby default
- Parameters:
- Return type:
- Returns:
the upsampled torch.Tensor.
See also
PyrUp: the module form.pyrdown(): one level down, by any factor.build_laplacian_pyramid(): subtractspyrupof each Gaussian level from the next finer one.
Examples
>>> input = torch.arange(4, dtype=torch.float32).reshape(1, 1, 2, 2)
>>> pyrup(input, align_corners=True)
tensor([[[[0.7500, 0.8750, 1.1250, 1.2500],
          [1.0000, 1.1250, 1.3750, 1.5000],
          [1.5000, 1.6250, 1.8750, 2.0000],
          [1.7500, 1.8750, 2.1250, 2.2500]]]])
- kornia.geometry.transform.build_pyramid(input, max_level, border_type='reflect', align_corners=False)[source]#
Build a Gaussian pyramid: the image and its successively halved levels, as a list.
levels = build_pyramid(input, max_level)takes images(B, C, H, W)and returns a list ofmax_leveltensors: the input itself, then each previous level throughpyrdown(),(B, C, H // 2, W // 2)and so on. Every level must have at least one pixel per side, soHandWmust be at least2 ** (max_level - 1). The blur extends its reflected border across the final 2 by 2 level. For band-pass levels, usebuild_laplacian_pyramid(); for octaves of several blurs each, with their sigmas,ScalePyramid.
- Convention:
input:
(B, C, H, W)max_levelis the total number of levels returned (including the unchanged original as level 0), not a 0-based index of the last leveleach subsequent level is produced by
pyrdown()(floor(side / 2)per dimension)
- Parameters:
input (
Tensor) – the torch.Tensor to be used to construct the pyramid.max_level (
int) – a positive integer giving the number of pyramid levels to return, including the unchanged original image as level 0.border_type (
str, optional) – the padding mode to be applied before convolving. The expected modes are:'constant','reflect','replicate'or'circular'. Default:"reflect"align_corners (
bool, optional) – interpolation flag. Default:False
- Return type:
- Shape:
Input:
(B, C, H, W)Output
[(B, C, H, W), (B, C, H // 2, W // 2), ...]
See also
build_laplacian_pyramid(): the differences of these levels, ending with the coarsest one.ScalePyramid: octaves of several blurred levels each, with their sigmas, for keypoint detection.pyrdown(): one level of this pyramid.
- kornia.geometry.transform.build_laplacian_pyramid(input, max_level, border_type='reflect', align_corners=False, *, minimal_padding=None)[source]#
Build a Laplacian pyramid: band-pass differences of Gaussian levels, ending with the coarsest level.
levels = build_laplacian_pyramid(input, max_level)takes images(B, C, H, W)and returns a list ofmax_leveltensors: leveliis Gaussian leveliofbuild_pyramid()minuspyrup()of Gaussian leveli + 1, and the last is the coarsest Gaussian level. Starting fromx = levels[-1],x = pyrup(x, border_type, align_corners) + levels[i]forifrommax_level - 2down to 0, with theborder_typeandalign_cornersthe pyramid was built with, rebuilds the input up to float rounding. The input is first reflect-padded at the right and bottom to the next power of two per side when neither side is a power of two or a side does not halve evenlymax_level - 1times (see Convention); every level is then shaped from the padded size, and the rebuilt image is the padded one. That rule is deprecated since kornia 0.9.1: with the defaultminimal_padding=None, an eager call thatminimal_padding=Truewould shape differently emits aFutureWarning.minimal_padding=Truegives the rule of a future minor release, which pads only to the next multiple of2 ** (max_level - 1), andminimal_padding=Falsekeeps the current rule without the warning. For the Gaussian levels themselves, usebuild_pyramid().See [BA87] for more details.
- Convention:
input:
(B, C, H, W)max_levelis the total number of levels returned, not a 0-based index of the last levellevels
0throughmax_level - 2are band-pass residuals: leveli=build_pyramid()Gaussian leveliminus apyrup()-expanded Gaussian leveli + 1; only the last element (indexmax_level - 1) is the unsubtracted final Gaussian level — level 0 is not the unchanged original image whenevermax_level > 1the input is reflect-padded up to the next power of two (per dimension) when neither side is already a power of two, or when
max_level > 1and a side is not divisible by2 ** (max_level - 1). When padding is applied, every returned level — including level 0 — is shaped from the padded sizewith
minimal_padding=True, the input is padded only when a side is not divisible by2 ** (max_level - 1), and only that side, to the next multiple. So 480x640 at 3 levels stays 480x640, where the rule above gives 512x1024. A side too small for the padding to reflect repeats its last row or column instead, whateverborder_typeborder_type:
'reflect'by defaultalign_corners:
Falseby default
- Parameters:
input (
Tensor) – the torch.Tensor to be used to construct the pyramid with shape(B, C, H, W).max_level (
int) – a positive integer giving the number of pyramid levels to return (see Convention above for what each level contains).border_type (
str, optional) – the padding mode to be applied before convolving. The expected modes are:'constant','reflect','replicate'or'circular'. Default:"reflect"align_corners (
bool, optional) – interpolation flag. Default:Falseminimal_padding (
bool|None, optional) –Truepads only asmax_levelneeds (see Convention above), the future default.Falsekeeps the power-of-two rule without a warning.None, the current default, uses the power-of-two rule and warns on a call thatTruewould shape differently. OnceTrueis the default,Falsekeeps the power-of-two rule for one more minor release, with a deprecation warning, and then the keyword is removed. Default:None
- Returns:
[(B, C, H', W'), (B, C, H' / 2, W' / 2), ...], where(H', W')equals the input(H, W)unless padding was applied (see Convention above), in which case it is the padded size.- Return type:
Output
See also
build_pyramid(): the Gaussian levels these are differences of.pyrup(): the upsampling step between levels, also the one that rebuilds the image.ScalePyramid: octaves of blurred levels for keypoint detection, with their sigmas.
Example
>>> levels = build_laplacian_pyramid(torch.rand(1, 1, 480, 640), 3, minimal_padding=True)
>>> [tuple(level.shape[-2:]) for level in levels]
[(480, 640), (240, 320), (120, 160)]
- kornia.geometry.transform.is_powerof_two(x)[source]#
Check whether an integer is a positive power of two.
is_powerof_two(x)returnsTruefor 1, 2, 4, 8, … andFalsefor every other integer,0and negative numbers included.build_laplacian_pyramid()uses it to decide whether to pad an image.- Parameters:
x (
int) – the integer to check.- Return type:
- Returns:
Trueifxis a positive power of two,Falseotherwise (including for0).
See also
find_next_powerof_two(): the smallest power of two not belowx.
Example
>>> is_powerof_two(64)
True
>>> is_powerof_two(100)
False
- kornia.geometry.transform.find_next_powerof_two(x)[source]#
Find the smallest power of two that is greater than or equal to a positive integer.
find_next_powerof_two(x)returnsxitself when it is a power of two, and the next one above otherwise. It is defined for positive integers only.build_laplacian_pyramid()pads each side of an image to it.- Parameters:
x (
int) – a positive integer.- Return type:
- Returns:
the smallest power of two not below
x.
See also
is_powerof_two(): whetherxis already a power of two.
Example
>>> find_next_powerof_two(100)
128
>>> find_next_powerof_two(64)
64
Image 3D transforms#
Warp a volume by an affine matrix (affine3d()) or rotate it about its centre by an axis-angle vector
(rotate3d()), at the input size.
- kornia.geometry.transform.affine3d(tensor, matrix, mode='bilinear', padding_mode='zeros', align_corners=False)[source]#
Warp a volume by a source→destination 3x4 affine matrix, keeping its size.
out = affine3d(tensor, matrix)warps(C, D, H, W)or(B, C, D, H, W)volumes by(B, 3, 4)source→destination voxel affine matrices and returns them at their own size, aswarp_affine3d()withdsize=(D, H, W)does; one matrix serves every volume of a batch. Passalign_corners=True: at the defaultFalsethe warp mixes two voxel normalizations, so a translation oftvoxels moves the volumet * size / (size - 1)voxels along that axis (#4503). For images, useaffine().- Convention:
matrixis the source→destination pixel affine matrix(B, 3, 4)align_corners:
Falseby default (the 2Daffine()defaults toTrue)
- Parameters:
tensor (
Tensor) – The image tensor to be warped in shapes of(C, D, H, W)or(B, C, D, H, W).matrix (
Tensor) – The affine transformation matrix with shape(B, 3, 4).mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – interpolation flag. Default:False
- Return type:
- Returns:
The warped image, with the shape of the input.
See also
affine(): the 2D warp of images, whose defaultalign_corners=Trueis correct.warp_affine3d(): the same warp with an explicit output size.rotate3d(): rotate a volume about its centre without building the matrix.
Example
>>> img = torch.rand(1, 2, 4, 3, 5)
>>> aff = torch.eye(3, 4)[None]
>>> out = affine3d(img, aff)
>>> print(out.shape)
torch.Size([1, 2, 4, 3, 5])
- kornia.geometry.transform.rotate3d(tensor, yaw, pitch, roll, center=None, mode='bilinear', padding_mode='zeros', align_corners=False)[source]#
Rotate a volume by an axis-angle vector of yaw, pitch and roll in degrees.
out = rotate3d(tensor, yaw, pitch, roll)rotates(C, D, H, W)or(B, C, D, H, W)volumes by the axis-angle vector(yaw, pitch, roll)in degrees,(B,)each, aboutcenter((B, 3)(x, y, z)pixels, by default the volume centre), and returns them at their size. Positive angles follow the right-hand rule, so a positiveroll, aboutz, turns clockwise on screen, the opposite ofrotate()(3D rotations are right-handed by design). Passalign_corners=True: at the defaultFalsethe warp mixes two voxel normalizations, which changes the rotation unless it turns about the volume centre in a plane whose two sizes are equal, as any rotation of a cube about its centre does (#4503).- Convention:
centeris(x, y, z)in pixels, origin at the top-left of the first depth slice (z = 0); defaults to the tensor centeryaw,pitchandrollare one axis-angle vector(rx, ry, rz)in degrees, not three composed per-axis Euler rotations: the three are concatenated and handed toget_projective_transform(), which applies Rodrigues’ formula. The rotation axis is(rx, ry, rz) / ||(rx, ry, rz)||and the angle is||(rx, ry, rz)||degrees, so(90, 90, 0)turns through90 * sqrt(2)degrees about(1, 1, 0) / sqrt(2)while(30, 0, 0)is a 30-degree turn aboutx. A single non-zero component therefore is the per-axis rotation it names, which is why one angle reads the same under either reading; two or more do not, and neither Euler order reproduces the axis-angle result.align_corners:
Falseby default (the 2Drotate()defaults toTrue)
- Parameters:
tensor (
Tensor) – The image tensor to be warped in shapes of(C, D, H, W)or(B, C, D, H, W).yaw (
Tensor) – Therxcomponent of the axis-angle vector. The tensor must have a shape of (B), where B is batch size.pitch (
Tensor) – Therycomponent of the axis-angle vector. The tensor must have a shape of (B), where B is batch size.roll (
Tensor) – Therzcomponent of the axis-angle vector. The tensor must have a shape of (B), where B is batch size.center (
Optional[Tensor], optional) – The center through which to rotate. The tensor must have a shape of (B, 3), where B is batch size and last dimension contains x, y and z. Default:Nonemode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – interpolation flag. Default:False
- Returns:
The rotated tensor with shape as input.
- Return type:
See also
rotate(): the 2D rotation of images, counter-clockwise on screen.affine3d(): warp a volume by any(B, 3, 4)affine matrix.get_projective_transform(): the(B, 3, 4)matrix of this rotation, with a scale.
Matrix transformations#
Build the matrices the warps take: a homography from point pairs (get_perspective_transform(), and
get_perspective_transform3d() from box corners), an affine matrix from a rotation, a translation, a shear or
all of them (get_rotation_matrix2d(), get_translation_matrix2d(), get_shear_matrix2d(),
get_affine_matrix2d(), and in 3D get_projective_transform(), get_shear_matrix3d(),
get_affine_matrix3d()), the inverse of an affine matrix (invert_affine_transform()) and [R | t]
(projection_from_Rt()). get_tps_transform() fits the thin-plate spline that warp_image_tps() takes.
- kornia.geometry.transform.get_perspective_transform(points_src, points_dst)[source]#
Compute the homography that maps four source points exactly onto four destination points.
M = get_perspective_transform(points_src, points_dst)takes two(B, 4, 2)sets of(x, y)points, matched by index, and returns the(B, 3, 3)homography, scaled toM[2, 2] = 1where it can be, that maps each source point onto its destination point: the source→destination pixel homography thatwarp_perspective()takes. It solves the four-point system in closed form, by Heckbert’s square-to-quadrilateral mappings, rather than with the DLT, whose exact solution it equals, so it needs no linear solver. For more than four or noisy correspondences, usefind_homography_dlt()orRANSAC.The matrix maps each source point onto its destination point, up to the projective scale:
\[\begin{split}\begin{bmatrix} x^{'} \\ y^{'} \\ 1 \\ \end{bmatrix} = \begin{bmatrix} h_1 & h_2 & h_3 \\ h_4 & h_5 & h_6 \\ h_7 & h_8 & h_9 \\ \end{bmatrix} \cdot \begin{bmatrix} x \\ y \\ 1 \\ \end{bmatrix}\end{split}\]- Convention:
points:
(x, y), pixel centers, origin at top-left; shape(B, 4, 2)a degenerate quadrilateral, such as one with three collinear points or two equal ones, does not raise: a degenerate source returns a non-finite matrix, a degenerate destination a non-finite or a singular one
Mis scaled toM[2, 2] = 1wherever that form is finite in the output dtype. Where it is not, because the computed bottom-right entry is exactly zero, as for some homographies that send source pixel(0, 0)to infinity although neither quadrilateral is degenerate, or because the form overflows the dtype, such as a float16 one with entries beyond65504,Mis divided instead by the geometric mean of its largest and smallest nonzero magnitudes, which keeps both in range where the dtype can hold their ratio. When the true bottom-right entry is zero but rounding leaves a small residue,M[2, 2] = 1holds and the other entries are large, about the inverse of that residue; the matrix still maps the points.find_homography_dlt()returns the same map at another scalefloat16 and bfloat16 points are solved in float32, and the result is cast back to their dtype
integer or boolean points give a matrix in the default floating dtype; floating points keep theirs
a caller’s autocast region does not change the result, outside TorchScript
- Parameters:
- Return type:
- Returns:
the perspective transformation with shape
(B, 3, 3).
See also
warp_perspective(): warp an image by the returned homography.get_perspective_transform3d(): the 3D counterpart, a(B, 4, 4)homography from box corners.find_homography_dlt(): a least-squares homography from any number of weighted point pairs.RANSAC: a homography that is robust to wrong correspondences.
Example
>>> x1 = torch.tensor([[[0., 0.], [1., 0.], [1., 1.], [0., 1.]]])
>>> x2 = torch.tensor([[[1., 0.], [0., 0.], [0., 1.], [1., 1.]]])
>>> x2_trans_x1 = get_perspective_transform(x1, x2)
- kornia.geometry.transform.get_perspective_transform3d(src, dst)[source]#
Compute the 3D homography that maps five source box corners exactly onto destination ones.
M = get_perspective_transform3d(src, dst)takes two(B, 8, 3)sets of(x, y, z)box corners inbbox_generator3d()order and returns the(B, 4, 4)homography, withM[3, 3] = 1, that maps corners 0, 1, 2, 5 and 7 ofsrconto those ofdst: the source→destination voxel homography thatwarp_perspective3d()takes. The other three corners map onto theirs only when all eight pairs are related by one homography. For 2D points, useget_perspective_transform().The function calculates the matrix of a perspective transform so that:
\[\begin{split}\begin{bmatrix} t_{i}x_{i}^{'} \\ t_{i}y_{i}^{'} \\ t_{i}z_{i}^{'} \\ t_{i} \\ \end{bmatrix} = \textbf{map_matrix} \cdot \begin{bmatrix} x_{i} \\ y_{i} \\ z_{i} \\ 1 \\ \end{bmatrix}\end{split}\]where
\[dst(i) = (x_{i}^{'},y_{i}^{'},z_{i}^{'}), src(i) = (x_{i}, y_{i}, z_{i}), i = 0,1,2,5,7\]Concrete math is as below:
\[\[ u_i =\frac{c_{00} * x_i + c_{01} * y_i + c_{02} * z_i + c_{03}} {c_{30} * x_i + c_{31} * y_i + c_{32} * z_i + c_{33}} \] \[ v_i =\frac{c_{10} * x_i + c_{11} * y_i + c_{12} * z_i + c_{13}} {c_{30} * x_i + c_{31} * y_i + c_{32} * z_i + c_{33}} \] \[ w_i =\frac{c_{20} * x_i + c_{21} * y_i + c_{22} * z_i + c_{23}} {c_{30} * x_i + c_{31} * y_i + c_{32} * z_i + c_{33}} \]\]\[\begin{split}\begin{pmatrix} x_0 & y_0 & z_0 & 1 & 0 & 0 & 0 & 0 & 0 & 0 & 0 & 0 & -x_0*u_0 & -y_0*u_0 & -z_0 * u_0 \\ x_1 & y_1 & z_1 & 1 & 0 & 0 & 0 & 0 & 0 & 0 & 0 & 0 & -x_1*u_1 & -y_1*u_1 & -z_1 * u_1 \\ x_2 & y_2 & z_2 & 1 & 0 & 0 & 0 & 0 & 0 & 0 & 0 & 0 & -x_2*u_2 & -y_2*u_2 & -z_2 * u_2 \\ x_5 & y_5 & z_5 & 1 & 0 & 0 & 0 & 0 & 0 & 0 & 0 & 0 & -x_5*u_5 & -y_5*u_5 & -z_5 * u_5 \\ x_7 & y_7 & z_7 & 1 & 0 & 0 & 0 & 0 & 0 & 0 & 0 & 0 & -x_7*u_7 & -y_7*u_7 & -z_7 * u_7 \\ 0 & 0 & 0 & 0 & x_0 & y_0 & z_0 & 1 & 0 & 0 & 0 & 0 & -x_0*v_0 & -y_0*v_0 & -z_0 * v_0 \\ 0 & 0 & 0 & 0 & x_1 & y_1 & z_1 & 1 & 0 & 0 & 0 & 0 & -x_1*v_1 & -y_1*v_1 & -z_1 * v_1 \\ 0 & 0 & 0 & 0 & x_2 & y_2 & z_2 & 1 & 0 & 0 & 0 & 0 & -x_2*v_2 & -y_2*v_2 & -z_2 * v_2 \\ 0 & 0 & 0 & 0 & x_5 & y_5 & z_5 & 1 & 0 & 0 & 0 & 0 & -x_5*v_5 & -y_5*v_5 & -z_5 * v_5 \\ 0 & 0 & 0 & 0 & x_7 & y_7 & z_7 & 1 & 0 & 0 & 0 & 0 & -x_7*v_7 & -y_7*v_7 & -z_7 * v_7 \\ 0 & 0 & 0 & 0 & 0 & 0 & 0 & 0 & x_0 & y_0 & z_0 & 1 & -x_0*w_0 & -y_0*w_0 & -z_0 * w_0 \\ 0 & 0 & 0 & 0 & 0 & 0 & 0 & 0 & x_1 & y_1 & z_1 & 1 & -x_1*w_1 & -y_1*w_1 & -z_1 * w_1 \\ 0 & 0 & 0 & 0 & 0 & 0 & 0 & 0 & x_2 & y_2 & z_2 & 1 & -x_2*w_2 & -y_2*w_2 & -z_2 * w_2 \\ 0 & 0 & 0 & 0 & 0 & 0 & 0 & 0 & x_5 & y_5 & z_5 & 1 & -x_5*w_5 & -y_5*w_5 & -z_5 * w_5 \\ 0 & 0 & 0 & 0 & 0 & 0 & 0 & 0 & x_7 & y_7 & z_7 & 1 & -x_7*w_7 & -y_7*w_7 & -z_7 * w_7 \\ \end{pmatrix}\end{split}\]- Convention:
points:
(x, y, z), pixel centers, origin at the top-left of the first depth slice; shape(B, 8, 3)the 15 unknowns are solved exactly from points 0, 1, 2, 5 and 7, the corners
000,100,110,101and011inbbox_generator3d()order; points 3, 4 and 6 are not used, so they map onto theirdstonly when all eight pairs are related by one homographyreturns the source→destination pixel homography
(B, 4, 4)integer or boolean points give a matrix in the default floating dtype; floating points keep theirs
- Parameters:
- Return type:
- Returns:
the perspective transformation with shape
(B, 4, 4).
See also
get_perspective_transform(): the 2D homography from four point pairs.warp_perspective3d(): warp a volume by the returned homography.bbox_generator3d(): box corners in the order this function reads them.
- kornia.geometry.transform.get_projective_transform(center, angles, scales)[source]#
Compute the 3x4 affine matrix of a 3D scaling and axis-angle rotation about a centre.
P = get_projective_transform(center, angles, scales)takes(B, 3)centres(x, y, z)in pixels, axis-angle vectors(rx, ry, rz)in degrees and per-axis scale factors, and returns the(B, 3, 4)source→destination pixel matrix that scales and then rotates aboutcenter, aswarp_affine3d()takes. The rotation is Rodrigues’ formula onanglesconverted to radians and follows the right-hand rule, so a positive rotation aboutzturns clockwise on screen, the opposite ofget_rotation_matrix2d(). The matrix is affine, not projective; to add a translation and shears, useget_affine_matrix3d(), whose angles turn the other way (#4408).Warning
This API signature it is experimental and might suffer some changes in the future.
- Convention:
centeris(x, y, z)in pixels, origin at the top-left of the first depth slice (z = 0)rotation follows the right-hand rule (see
kornia.geometry.conversions.axis_angle_to_rotation_matrix()); a positive rotation about +z is clockwise on screen (y-down image axes) — opposite ofget_rotation_matrix2d()returns the projection matrix
(B, 3, 4)in pixel coordinatesa caller’s autocast region does not change the result
float16andbfloat16angles are converted and rotated infloat32, and the rotation is rounded once to the input dtype
- Parameters:
center (
Tensor) – center of the rotation (x,y,z) in the source with shape(B, 3).angles (
Tensor) – axis angle vector containing the rotation angles in degrees in the form of (rx, ry, rz) with shape(B, 3). Internally it calls Rodrigues to compute the rotation matrix from axis-angle.scales (
Tensor) – per-axis scale factors(sx, sy, sz)with shape(B, 3), or(1, 3)or(3,)shared across the batch. A(3,)tensor always means per-axis factors, including whenB = 3. Use(B, 1)for one isotropic factor per sample, or(1,)for one factor shared across all samples and axes. Per-sample isotropic factors must have shape(B, 1), not(B,).
- Return type:
- Returns:
the projection matrix of 3D rotation with shape
(B, 3, 4).- Raises:
ShapeError – If
scalesis not(B, 3),(B, 1),(1, 3),(3,)or(1,).
See also
get_rotation_matrix2d(): the 2D rotation and scale, counter-clockwise on screen.get_affine_matrix3d(): adds a translation and shears, and negates the angles.rotate3d(): rotate a volume about its centre by such an axis-angle vector.axis_angle_to_rotation_matrix(): the 3x3 rotation of an axis-angle vector in radians.
- kornia.geometry.transform.get_rotation_matrix2d(center, angle, scale)[source]#
Compute the 2D affine matrix that scales and rotates counter-clockwise, in degrees, about a centre.
M = get_rotation_matrix2d(center, angle, scale)takes centres(B, 2)as(x, y)pixels, angles(B,)in degrees and scale factors(B, 2)forxandy, and returns the(B, 2, 3)source→destination pixel matrix that scales and then rotates aboutcenter, which stays fixed. A positive angle turns counter-clockwise as displayed, withypointing down. PassMtowarp_affine(); to add a translation and a shear in one(B, 3, 3)matrix, useget_affine_matrix2d(), and to rotate an image directly,rotate().With equal scale factors
scale, the matrix is:\[\begin{split}\begin{bmatrix} \alpha & \beta & (1 - \alpha) \cdot \text{x} - \beta \cdot \text{y} \\ -\beta & \alpha & \beta \cdot \text{x} + (1 - \alpha) \cdot \text{y} \end{bmatrix}\end{split}\]where
\[\begin{split}\alpha = \text{scale} \cdot \cos(\text{angle}) \\ \beta = \text{scale} \cdot \sin(\text{angle})\end{split}\]With two different factors, the left 2x2 block is the rotation times
diag(scale[:, 0], scale[:, 1]). A caller’s autocast region does not change the result.- Convention:
centeris(x, y)in pixels, origin at top-leftpositive
anglerotates counter-clockwise as displayed (y-down image axes)returns
(B, 2, 3)affine matrix in pixel coordinates
- Parameters:
center (
Tensor) – center of the rotation in the source image with shape(B, 2).angle (
Tensor) – rotation angle in degrees. Positive values mean counter-clockwise rotation (the coordinate origin is assumed to be the top-left corner) with shape(B).scale (
Tensor) – scale factor for x, y scaling with shape(B, 2).
- Return type:
- Returns:
the affine matrix of 2D rotation with shape
(B, 2, 3).- Raises:
TypeError – If any input is not a tensor.
ValueError – If input shapes are invalid, or batch sizes, devices or dtypes do not match.
See also
get_affine_matrix2d(): also translates and shears, returns(B, 3, 3), and turns clockwise for a positive angle (#4408).rotate(): rotate an image about its centre without building the matrix.get_projective_transform(): the 3D rotation and scale, by an axis-angle vector.angle_to_rotation_matrix(): the 2x2 rotation matrix of an angle alone.
Example
>>> center = torch.zeros(1, 2)
>>> scale = torch.ones((1, 2))
>>> angle = 45. * torch.ones(1)
>>> get_rotation_matrix2d(center, angle, scale)
tensor([[[ 0.7071,  0.7071,  0.0000],
         [-0.7071,  0.7071,  0.0000]]])
- kornia.geometry.transform.get_translation_matrix2d(translations)[source]#
Compute the 3x3 matrix of a 2D translation in pixels.
M = get_translation_matrix2d(translations)takes(B, 2)shifts(dx, dy)in pixels and returns the(B, 3, 3)matrix that moves every point by them, a positivedxto the right and a positivedydown. PassM[:, :2]towarp_affine()orMtowarp_perspective(); to shift an image directly, usetranslate().- Convention:
translationsis(dx, dy)in pixels; returns(B, 3, 3)affine matrix in pixel coordinates
- Parameters:
translations (
Tensor) – torch.Tensor containing the translation vector with shape(B, 2).- Return type:
- Returns:
the affine transformation matrix
(B, 3, 3).- Raises:
ShapeError – If
translationsis not(B, 2). A single translation needs shape(1, 2).
See also
translate(): shift an image without building the matrix.get_affine_matrix2d(): a translation composed with a rotation, a scale and a shear.
- kornia.geometry.transform.get_shear_matrix2d(center, sx=None, sy=None)[source]#
Compute the 3x3 matrix of a 2D shear given as two angles in radians about a centre.
M = get_shear_matrix2d(center, sx, sy)takes(B, 2)centres(x, y)in pixels and optional(B,)shear anglessxandsyin radians (zero when omitted), and returns the(B, 3, 3)source→destination pixel matrix that shears alongxby-tan(sx)and then alongyby-tan(sy), both aboutcenter.Affineandget_affine_matrix2d()read shear angles this way;shear()andSheartake raw factors about pixel(0, 0)instead, which shear the other way for the same values belowpi / 2in magnitude (#5661).\[\begin{split}\begin{bmatrix} 1 & b \\ a & ab + 1 \\ \end{bmatrix}\end{split}\]Here \(a = -\tan(sy)\) and \(b = -\tan(sx)\).
- Convention:
centeris(x, y)in pixels, origin at top-leftsxandsyare angles in radians; aboutcenter = (cx, cy), the forward mapping isx_out = x - tan(sx) * (y - cy), theny_out = y - tan(sy) * (x_out - cx). Pixel x increases rightward and y downward. This differs fromshear()’s raw factors.returns
(B, 3, 3)affine matrix in pixel coordinates
- Parameters:
- Return type:
- Returns:
the shear matrix with shape
(B, 3, 3), to be passed to the affine transformation.
See also
get_shear_matrix3d(): the 3D shear from up to six angles,(B, 4, 4).shear(): shear an image by raw factors about pixel(0, 0), which shear the other way belowpi / 2.get_affine_matrix2d(): this shear composed with a rotation, a scale and a translation.
Examples
>>> rng = torch.manual_seed(0)
>>> sx = torch.randn(1)
>>> sx
tensor([1.5410])
>>> center = torch.tensor([[0., 0.]])  # Bx2
>>> get_shear_matrix2d(center, sx=sx)
tensor([[[  1.0000, -33.5468,   0.0000],
         [ -0.0000,   1.0000,   0.0000],
         [  0.0000,   0.0000,   1.0000]]])
- kornia.geometry.transform.get_shear_matrix3d(center, sxy=None, sxz=None, syx=None, syz=None, szx=None, szy=None)[source]#
Compute the 4x4 matrix of a 3D shear given as up to six angles in radians about a centre.
M = get_shear_matrix3d(center, sxy, sxz, syx, syz, szx, szy)takes(B, 3)centres(x, y, z)in pixels and optional(B,)shear angles in radians (zero when omitted), and returns the(B, 4, 4)source→destination pixel matrix below, whose translation keepscenterfixed. With \(S_{ab} = -\tan(s_{ab})\), the anglesabon its own adds \(S_{ab}\) times coordinateato coordinateb.sxyandsxzform one shear,syxandsyza second andszxandszya third, and the linear part is the product of the three in that order, so a point is sheared byszxandszyfirst and bysxyandsxzlast.\[\begin{split}\begin{bmatrix} 1 & o & r & x - (x + oy + rz) \\ m & p & s & y - (mx + py + sz) \\ n & q & t & z - (nx + qy + tz) \\ 0 & 0 & 0 & 1 \\ \end{bmatrix} Where: m = S_{xy} n = S_{xz} o = S_{yx} p = S_{xy}S_{yx} + 1 q = S_{xz}S_{yx} + S_{yz} r = S_{zx} + S_{yx}S_{zy} s = S_{xy}S_{zx} + (S_{xy}S_{yx} + 1)S_{zy} t = S_{xz}S_{zx} + (S_{xz}S_{yx} + S_{yz})S_{zy} + 1\end{split}\]Here \(S_{ab} = -\tan(s_{ab})\), and \((x, y, z)\) is
center.- Convention:
centeris(x, y, z)in pixels, origin at the top-left of the first depth slice (z = 0); it is a fixed point of the returned matrix for every combination of shearsreturns
(B, 4, 4)affine matrix in pixel coordinates
- Parameters:
center (
Tensor) – shearing center coordinates of (x, y, z), with shape(B, 3).sxy (
Optional[Tensor], optional) – shearing angle in radians that adds \(S_{xy} x\) toy. Default:Nonesxz (
Optional[Tensor], optional) – shearing angle in radians that adds \(S_{xz} x\) toz. Default:Nonesyx (
Optional[Tensor], optional) – shearing angle in radians that adds \(S_{yx} y\) tox. Default:Nonesyz (
Optional[Tensor], optional) – shearing angle in radians that adds \(S_{yz} y\) toz. Default:Noneszx (
Optional[Tensor], optional) – shearing angle in radians that adds \(S_{zx} z\) tox. Default:Noneszy (
Optional[Tensor], optional) – shearing angle in radians that adds \(S_{zy} z\) toy. Default:None
- Return type:
- Returns:
the shear matrix with shape
(B, 4, 4), to be passed to the affine transformation.
See also
get_shear_matrix2d(): the 2D shear from two angles,(B, 3, 3).get_affine_matrix3d(): this shear composed with a rotation, a scale and a translation.warp_perspective3d(): warp a volume by the returned matrix.
Examples
>>> rng = torch.manual_seed(0)
>>> sxy, sxz, syx, syz = torch.randn(4, 1)
>>> sxy, sxz, syx, syz
(tensor([1.5410]), tensor([-0.2934]), tensor([-2.1788]), tensor([0.5684]))
>>> center = torch.tensor([[0., 0., 0.]])  # Bx3
>>> get_shear_matrix3d(center, sxy=sxy, sxz=sxz, syx=syx, syz=syz)
tensor([[[  1.0000,  -1.4369,   0.0000,   0.0000],
         [-33.5468,  49.2039,   0.0000,   0.0000],
         [  0.3022,  -1.0729,   1.0000,   0.0000],
         [  0.0000,   0.0000,   0.0000,   1.0000]]])
- kornia.geometry.transform.get_affine_matrix2d(translations, center, scale, angle, sx=None, sy=None)[source]#
Compose a 2D affine matrix from a translation, clockwise rotation, scale and shear about a centre.
M = get_affine_matrix2d(translations, center, scale, angle, sx, sy)takes(B, 2)translations(dx, dy), centres(x, y)and scale factors forxandy,(B,)angles in degrees and optional(B,)shear anglessxandsyin radians, and returns the(B, 3, 3)source→destination pixel matrix that shears, scales, rotates and then translates, the first three aboutcenter. A positiveangleturns clockwise as displayed, unlikeget_rotation_matrix2d(),rotate()andAffine(#4408). PassM[:, :2]towarp_affine()orMtowarp_perspective().- Convention:
centeris(x, y)in pixels, origin at top-leftpositive
anglerotates clockwise as displayed — this function negatesanglebefore delegating toget_rotation_matrix2d(), whose convention is CCW-positivesxandsyare angles in radians, usingget_shear_matrix2d()’s negative-tangent, x-then-y shear aboutcenter, applied before rotation, scale and translationreturns
(B, 3, 3)affine matrix in pixel coordinatesa caller’s autocast region does not change the result (there, mixed float32 and half
centerand shears run in float32)
- Parameters:
translations (
Tensor) – torch.Tensor containing the translation vector with shape(B, 2).center (
Tensor) – torch.Tensor containing the center vector with shape(B, 2).scale (
Tensor) – torch.Tensor containing the scale factor with shape(B, 2).angle (
Tensor) – torch.Tensor of angles in degrees(B).sx (
Optional[Tensor], optional) – torch.Tensor containing the shear angle in radians in the x-direction with shape(B). Default:Nonesy (
Optional[Tensor], optional) – torch.Tensor containing the shear angle in radians in the y-direction with shape(B). Default:None
- Return type:
- Returns:
the affine transformation matrix
(B, 3, 3).
See also
get_rotation_matrix2d(): rotation and scale only,(B, 2, 3), counter-clockwise for a positive angle.get_affine_matrix3d(): the 3D composition,(B, 4, 4), whose positivezangle turns counter-clockwise on screen.Affine: warp an image by these parameters in one module, counter-clockwise for a positive angle.get_shear_matrix2d(): the shear part alone.find_affine(): an affine matrix fitted to point correspondences instead of built from parameters.
- kornia.geometry.transform.get_affine_matrix3d(translations, center, scale, angles, sxy=None, sxz=None, syx=None, syz=None, szx=None, szy=None)[source]#
Compose a 3D affine matrix from a translation, axis-angle rotation, scale and shears about a centre.
M = get_affine_matrix3d(translations, center, scale, angles)takes(B, 3)translations(dx, dy, dz), centres(x, y, z)in pixels, per-axis scale factors and axis-angle vectors in degrees, plus up to six optional(B,)shear angles in radians, and returns the(B, 4, 4)source→destination pixel matrix that shears, scales, rotates and then translates, the first three aboutcenter. The angles are negated beforeget_projective_transform(), so they turn the other way from that function androtate3d(): a positive rotation aboutzturns counter-clockwise on screen, asrotate()does andget_affine_matrix2d()does not (#4408). PassM[:, :3]towarp_affine3d()orMtowarp_perspective3d().- Convention:
centeris(x, y, z)in pixels, origin at the top-left of the first depth slice (z = 0)anglesare negated before delegating toget_projective_transform(), whose own rotation convention follows the right-hand rule (seekornia.geometry.conversions.axis_angle_to_rotation_matrix())returns
(B, 4, 4)affine matrix in pixel coordinatesa caller’s autocast region does not change the result (there, mixed float32 and half
centerand shears run in float32)
- Parameters:
translations (
Tensor) – torch.Tensor containing the translation vector (dx,dy,dz) with shape(B, 3).center (
Tensor) – torch.Tensor containing the center vector (x,y,z) with shape(B, 3).scale (
Tensor) – per-axis scale factors(sx, sy, sz)with shape(B, 3), or(1, 3)or(3,)shared across the batch. A(3,)tensor always means per-axis factors, including whenB = 3. Use(B, 1)for one isotropic factor per sample, or(1,)for one factor shared across all samples and axes. Per-sample isotropic factors must have shape(B, 1), not(B,).angles (
Tensor) – axis angle vector containing the rotation angles in degrees in the form of (rx, ry, rz) with shape(B, 3). Internally it calls Rodrigues to compute the rotation matrix from axis-angle.sxy (
Optional[Tensor], optional) – the shear anglesxyofget_shear_matrix3d(), in radians, with shape(B). Default:Nonesxz (
Optional[Tensor], optional) – the shear anglesxzofget_shear_matrix3d(), in radians, with shape(B). Default:Nonesyx (
Optional[Tensor], optional) – the shear anglesyxofget_shear_matrix3d(), in radians, with shape(B). Default:Nonesyz (
Optional[Tensor], optional) – the shear anglesyzofget_shear_matrix3d(), in radians, with shape(B). Default:Noneszx (
Optional[Tensor], optional) – the shear angleszxofget_shear_matrix3d(), in radians, with shape(B). Default:Noneszy (
Optional[Tensor], optional) – the shear angleszyofget_shear_matrix3d(), in radians, with shape(B). Default:None
- Return type:
- Returns:
the 3d affine transformation matrix
(B, 4, 4).- Raises:
ShapeError – If
scaleis not(B, 3),(B, 1),(1, 3),(3,)or(1,); seeget_projective_transform().
See also
get_affine_matrix2d(): the 2D composition, whose positive angle turns clockwise on screen.get_projective_transform(): rotation and scale only,(B, 3, 4), with the angles as given.get_shear_matrix3d(): the shear part alone.warp_affine3d(): warp a volume byM[:, :3].
- kornia.geometry.transform.invert_affine_transform(matrix)[source]#
Invert 2D affine matrices of shape
(B, 2, 3).M_inv = invert_affine_transform(M)returns, for each(B, 2, 3)affine matrix, the(B, 2, 3)inverse of its 3x3 extension with the last row(0, 0, 1), in the dtype ofM. It is pure matrix inversion, so the result keeps the input’s coordinates, pixel or normalized: the inverse of a source→destination matrix maps destination to source, and warps awarp_affine()result back. For(B, 3, 3)homographies, usetorch.linalg.inv().The input is the matrix:
\[\begin{split}\begin{bmatrix} a_{11} & a_{12} & b_{1} \\ a_{21} & a_{22} & b_{2} \\ \end{bmatrix}\end{split}\]- Convention:
matrixis a(B, 2, 3)affine transform in any coordinate convention (pixel or normalized) — pure matrix inversion; the result stays in the input’s conventionin eager mode a singular matrix raises
torch.linalg.LinAlgError
- Parameters:
matrix (
Tensor) – original affine transform. The torch.Tensor must be in the shape of(B, 2, 3).- Return type:
- Returns:
the reverse affine transform with shape
(B, 2, 3).
See also
warp_affine(): warp an image by a matrix or by its inverse.get_affine_matrix2d(): a(B, 3, 3)affine matrix from translation, rotation, scale and shear; pass itsM[:, :2].convert_affinematrix_to_homography(): the(B, 3, 3)extension, to compose with homographies.
- kornia.geometry.transform.projection_from_Rt(rmat, tvec)[source]#
Stack rotations and translations into
[R | t]matrices of shape(*, 3, 4).P = projection_from_Rt(rmat, tvec)concatenates rotations(*, 3, 3)and translations(*, 3, 1)with the same leading dimensions into the(*, 3, 4)matrices \(P = [R | t]\). It applies no intrinsics: for a camera projection matrix \(K [R | t]\), useprojection_from_KRt(), and for a 4x4 pose,Rt_to_matrix4x4().Warning
This API signature it is experimental and might suffer some changes in the future.
- Convention:
returns the concatenation \([R | t]\) with shape
(*, 3, 4)
- Parameters:
- Return type:
- Returns:
the projection matrix with shape
(*, 3, 4).
See also
projection_from_KRt(): also multiplies by the camera intrinsicsK.Rt_to_matrix4x4(): the homogeneous(B, 4, 4)pose instead.
- kornia.geometry.transform.get_tps_transform(points_src, points_dst)[source]#
Fit a thin-plate-spline warp that maps source points exactly onto target points.
kernel_weights, affine_weights = get_tps_transform(points_src, points_dst)takes(B, N, 2)point pairs and returns the(B, N, 2)kernel weights and(B, 3, 2)affine weights of Bookstein’s thin-plate spline, whose kernels are centred on the points where it interpolates:warp_points_tps(points_src, points_src, kernel_weights, affine_weights)returnspoints_dst. It is the same spline asscipy.interpolate.RBFInterpolator(points_src, points_dst, kernel="thin_plate_spline", degree=1). To warp an image, fit the reverse mapping and usewarp_image_tps()(see Convention); for a homography from four point pairs, useget_perspective_transform().- Convention:
points_src/points_dst:(B, N, 2)in(x, y)order, in whatever coordinate frame the caller supplies; no normalization is appliedreturns kernel weights
(B, N, 2)and affine weights(B, 3, 2); the identity mapping gives zero kernel weights and an identity affine up to solver round-off, and any pairs related by an affine map, a constant map included, give zero kernel weights. The kernel weightswsatisfyw.sum(1) == 0andw.mT @ points_src == 0, so the warp leaves its affine part only likelog rfar from the landmarksfor float32 points, a caller’s autocast region does not change the result, outside TorchScript (in the region, a mix of float32, float16 and bfloat16 points meets in float32); any other dtype mismatch raises
RuntimeErrorzero or one point makes the linear system singular and
torch.linalg.solveraises; two points, like any set ofpoints_srcall on one line, make it singular too, but round-off can hide that, and the solve then returns huge affine weights that throw points off that line far away and may miss the landmarks themselves. Repeatedpoints_srcare singular in the same way; repeatedpoints_dstare finethe tensor passed as the first argument is the
kernel_centersthat the warp function must receive with these weights.warp_points_tps()is composed in the natural(points_src, points_dst)order;warp_image_tps()samples from output space back into input space, so it is composed reversed, with both point sets in the normalized frame given in its Convention block:kernel_weights, affine_weights = get_tps_transform(points_dst, points_src) warped = warp_image_tps(image, kernel_centers=points_dst, kernel_weights=kernel_weights, affine_weights=affine_weights)
in kornia 0.9.1, a call outside TorchScript and
torch.compileemits aFutureWarningthat repeats which tensor to pass askernel_centers; it reads no tensor and does not change the result
- Parameters:
- Return type:
- Returns:
(B, N, 2)torch.Tensor of kernel weights and(B, 3, 2)torch.Tensor of affine weights. The last dimension contains the x-transform and y-transform weights as separate columns. Row 0 of the affine weights is the translation and rows 1 and 2 the matrix
Athat multiplies a point asp @ A.
See also
warp_points_tps(): applies the fitted spline to points, withpoints_srcaskernel_centers.warp_image_tps(): applies a spline fitted from target to source to an image.get_perspective_transform(): the(B, 3, 3)homography of four point pairs, one global matrix.
Example
>>> points_src = torch.rand(1, 5, 2)
>>> points_dst = torch.rand(1, 5, 2)
>>> kernel_weights, affine_weights = get_tps_transform(points_src, points_dst)
Crop operators#
Crop (B, C, H, W) images by integer slicing of axis-aligned boxes (crop_by_indices()), by resampling a
four-corner box to a fixed size (crop_and_resize()) or onto a second box whose size sets the output
(crop_by_boxes()), by a source→destination pixel matrix (crop_by_transform_mat()), or at the centre
(center_crop(), and its module form CenterCrop2D). A box is (B, 4, 2): its (x, y) corners
clockwise from the top-left, as inclusive pixel positions.
- kornia.geometry.transform.crop_by_indices(input_tensor, src_box, size=None, interpolation='bilinear', align_corners=None, antialias=False, shape_compensation='resize')[source]#
Crop axis-aligned boxes by integer slicing, then resize or pad each crop to a common size.
patches = crop_by_indices(input_tensor, src_box, size)takes images(B, C, H, W)and one box per image,(B, 4, 2), slices each box out with integer indices and returns(B, C, h, w)forsize = (h, w). Outside graph export (see the notes) it slices by the top-left corner, the right edge (xof vertex 1) and the bottom edge (yof vertex 3) of a box, and truncates float coordinates toward zero; withoutsizeit takes the size from the box asinfer_bbox_shape()does, whose height readsyof vertex 2, and every box must have the same size. A slice of another size thansize, from a box of another size or one clipped by the image border, is resized (shape_compensation='resize') or zero-padded or trimmed to it ('pad'). The crop is differentiable with respect to the image, not the box: for sub-pixel, rotated or differentiable boxes, usecrop_and_resize().- Convention:
input:
(B, C, H, W);sizeis(h, w)if given, else inferred fromsrc_box; a single box does not broadcast over a batch of imagessrc_box:(B, 4, 2)corner points in(x, y)order top-left, top-right, bottom-right, bottom-left — same convention ascrop_and_resize()unlike the other crop operators in this module:
interpolation=(notmode=),align_corners=Noneby default (notTrue), and anantialias=Falseoptionshape_compensation('resize'by default) applies whenever the cropped slice does not matchsize, whether or notsrc_boxis identical across the batch — each row’s output depends only on its own box.the part of a box outside the image is clipped on every side, a box that starts left of or above the image included, and
shape_compensationthen applies. With'pad'the padding goes on the side where the box overflowed, so every kept pixel stays at its position in the box.
Note
Under
torch.compile()a non-empty batch withsizegiven,'bilinear','bicubic'or'nearest'interpolation,antialias=Falseandshape_compensation='resize'is cropped by a gather that keeps the box coordinates on the device, so it traces withfullgraph=Trueand matches the eager result up to float rounding. Every other call keeps the eager path, which reads the box coordinates back to Python and breaks the graph. Graph export is described in the note below.- Parameters:
input_tensor (
Tensor) – the 2D image torch.Tensor with shape(B, C, H, W).src_box (
Tensor) – a torch.Tensor with shape(B, 4, 2)containing the coordinates of the bounding boxes to be extracted, where each box is defined in the clockwise order: top-left, top-right, bottom-right and bottom-left. The coordinates must be in x, y order.size (
Optional[Tuple[int,int]], optional) – output size. An auto resize or F.pad will be performed according toshape_compensationif the cropped slice sizes are not exactly align size. If None, will auto-infer from src_box. Default:Noneinterpolation (
str, optional) – algorithm used for upsampling:'nearest'|'nearest-exact'|'bilinear'|'bicubic'|'area'. Default:"bilinear"align_corners (
Optional[bool], optional) – interpolation flag. Default:Noneantialias (
bool, optional) – if True, then image will be filtered with Gaussian before downscaling. No effect for upscaling. Default:Falseshape_compensation (
str, optional) – how to compensate when the cropped slice size differs from size:'resize'resamples, while'pad'pads or trims.'F.pad'is a legacy alias for'pad'. Default:"resize"
- Return type:
- Returns:
The cropped torch.Tensor with shape
(B, C, h, w), where(h, w)issizeif given, otherwise the shape inferred fromsrc_box.- Raises:
ValueError – if
shape_compensationis not'resize','pad'or'F.pad', orsizeisNoneand the boxes differ in size.
See also
crop_and_resize(): resamples any four-corner box, differentiably with respect to its corners.CenterCrop2D: slices the central window with this function in its default mode, unless the size exceeds the input on an axis, where it zero-pads and slices directly.RandomCrop: random boxes, sliced with this function in its default mode, in an augmentation pipeline.
Note
Under graph export (
torch.export.export()/torch.onnx.export()) the box coordinates cannot be read back to Python, so the crop is captured as the same warp ascrop_and_resize()(align_corners=True), which keeps the box coordinates dynamic. This needssize: a box that is exactlysizepixels (whatRandomCropandCenterCrop2Dproduce) is reproduced exactly, any other box is resampled tosizewithalign_corners=Trueregardless ofshape_compensationandalign_corners. Withoutsizethe eager path is kept: it reads the box coordinates back to Python, which breaks the graph undertorch.compile()and is rejected bytorch.exportas data-dependent.
- kornia.geometry.transform.crop_by_boxes(input_tensor, src_box, dst_box, mode='bilinear', padding_mode='zeros', align_corners=True, validate_boxes=None)[source]#
Crop images by mapping a source box onto a destination box, whose size sets the output size.
patches = crop_by_boxes(input_tensor, src_box, dst_box)takes images(B, C, H, W)and two boxes per image,(B, 4, 2)each (both(1, 4, 2)for all images), warps each image by the homography that mapssrc_boxontodst_boxand returns the(B, C, h, w)window at destination pixels(0, 0)..``(w - 1, h - 1)``, where(h, w)is the inclusive size ofdst_box. Everydst_boxin the batch must have that same size, since the output is one tensor, and adst_boxthat does not start at(0, 0)shifts the crop by its offset, partly out of the window. The size is read from thedst_boxvalues on the host. Whendst_boxis the window(0, 0)..``(w - 1, h - 1)`` itself and(h, w)is known,crop_and_resize()withsize=(h, w)gives the same crop without that read; it always places the destination box at the origin, so it cannot reproduce an offsetdst_box. For volumes, usecrop_by_boxes3d().- Convention:
input:
(B, C, H, W)src_box/dst_box:(B, 4, 2)corner points in(x, y)order top-left, top-right, bottom-right, bottom-left — same convention ascrop_and_resize();dst_boxdetermines the output resolutiona single box (batch size 1) broadcasts over a batch of images, but a single image does not broadcast over a batch of boxes;
src_boxanddst_boxhave the same batch sizean empty batch has no
dst_boxto read a size from and returns(0, C, 0, 0)a box axis of one pixel in one box but not in the other returns NaN (a meaningless finite value with
mode='nearest'), as incrop_and_resize()(#4747)a
float16orbfloat16image is cropped infloat32, its homography solved and kept infloat32, and the patches rounded once to the image dtype
- Parameters:
input_tensor (
Tensor) – the 2D image torch.Tensor with shape(B, C, H, W).src_box (
Tensor) – a torch.Tensor with shape(B, 4, 2)containing the coordinates of the bounding boxes to be extracted, where each box is defined in the clockwise order: top-left, top-right, bottom-right and bottom-left. The coordinates must be in x, y order.dst_box (
Tensor) – a torch.Tensor with shape(B, 4, 2)containing the coordinates of the bounding boxes to be placed, where each box is defined in the clockwise order: top-left, top-right, bottom-right and bottom-left. The coordinates must be in x, y order.mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – mode for grid_generation. Default:Truevalidate_boxes (
Optional[bool], optional) – deprecated since kornia 0.9.1 and ignored; passingTrueorFalseemits aDeprecationWarning, and the defaultNonedoes not. The boxes are not validated, whatever its value: only the shapes ofsrc_boxanddst_boxand the equal size of thedst_boxboxes are checked. Default:None
- Return type:
- Returns:
the patches, with shape
(B, C, h, w)for the size(h, w)ofdst_box.- Raises:
AssertionError – if the boxes of
dst_boxdiffer in size.
See also
crop_and_resize(): takes the output size assizeand places the box at the patch corners.crop_by_transform_mat(): takes the source→destination matrix itself.crop_by_boxes3d(): the same for volumes and(B, 8, 3)boxes.
Examples
>>> input = torch.arange(16, dtype=torch.float32).reshape((1, 1, 4, 4))
>>> src_box = torch.tensor([[
...     [1., 1.],
...     [2., 1.],
...     [2., 2.],
...     [1., 2.],
... ]])  # 1x4x2
>>> dst_box = torch.tensor([[
...     [0., 0.],
...     [1., 0.],
...     [1., 1.],
...     [0., 1.],
... ]])  # 1x4x2
>>> crop_by_boxes(input, src_box, dst_box, align_corners=True)
tensor([[[[ 5.0000,  6.0000],
          [ 9.0000, 10.0000]]]])
- kornia.geometry.transform.crop_by_transform_mat(input_tensor, transform, out_size, mode='bilinear', padding_mode='zeros', align_corners=True)[source]#
Crop images by a source→destination pixel matrix, affine or homography, into a given output size.
patches = crop_by_transform_mat(input_tensor, transform, out_size)takes images(B, C, H, W)and a source→destination pixel matrix per image, affine(B, 2, 3)or homography(B, 3, 3)(a batch of 1 serves every image), and returns the(B, C, h, w)destination window starting at pixel(0, 0)forout_size = (h, w). It callswarp_affine()for an affine matrix andwarp_perspective()for a homography, after casting the matrix to the image dtype and expanding it to the batch: a float64 or integer matrix crops a float32 image, which those two reject, and a batch-1 homography serves a batch, whichwarp_perspectivealone does not allow. To build the matrix from boxes, usecrop_by_boxes()orcrop_and_resize(); for volumes,crop_by_transform_mat3d().- Convention:
input:
(B, C, H, W);out_sizeis(h, w)transformis the source→destination pixel transform, accepted as either(B, 2, 3)affine or(B, 3, 3)homogeneous; dispatch is by shape —(B, 2, 3)takes the cheaperwarp_affine()path, while(B, 3, 3)takeswarp_perspective()and uses the full matrix, so a non-trivial third (projective) row changes the output; anout_sizedimension of1is handled like any other size
- Parameters:
input_tensor (
Tensor) – the 2D image torch.Tensor with shape(B, C, H, W).transform (
Tensor) – a perspective transformation matrix with shape(B, 3, 3), or an affine matrix with shape(B, 2, 3)that takes the cheaper warp_affine path.out_size (
Tuple[int,int]) – size of the output image (height, width).mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (str) – padding mode for outside grid values
'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – mode for grid_generation. Default:True
- Return type:
- Returns:
the patches, with shape
(B, C, h, w).
See also
warp_affine(): the affine warp it calls, with afill_valuefor the padding.warp_perspective(): the homography warp it calls, with afill_valuefor the padding.crop_by_boxes(): builds the homography from a source and a destination box.crop_by_transform_mat3d(): the same for volumes, by(B, 3, 4)or(B, 4, 4)matrices.
- kornia.geometry.transform.center_crop(input_tensor, size, mode='bilinear', padding_mode='zeros', align_corners=True)[source]#
Crop the central window of each image to a given size, in one call.
patches = center_crop(input_tensor, size)takes images(B, C, H, W)and returns their central(B, C, h, w)windows forsize = (h, w): a sub-image of the input, with the extra pixel of an odd margin at the bottom/right. Asizelarger than the input pads bypadding_mode(zeros by default), again with the extra pixel at the bottom/right. The crop is an integer translation sampled bywarp_perspective(), so it is exact up to float rounding. For the module form, which slices by default, useCenterCrop2D; for volumes,center_crop3d().- Convention:
input:
(B, C, H, W)(strictly 4D — no unbatched(C, H, W)/(H, W)input is accepted);sizeis(h, w)offset: the crop starts at the integer pixel
int(H / 2 - h / 2)(likewise for the width), as inCenterCrop2D, so the output is a sub-image of the input. With an odd margin the extra pixel is left at the bottom/right; for asizelarger than the input, the extra padding pixel goes there too.
- Parameters:
input_tensor (
Tensor) – the 2D image torch.Tensor with shape(B, C, H, W).size (
Tuple[int,int]) – a tuple with the expected height and width of the output patch.mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – mode for grid_generation. Default:True
- Return type:
- Returns:
the central windows, with shape
(B, C, h, w).
See also
CenterCrop2D: the module form; slices with integer indices by default instead of resampling.center_crop3d(): the central window of each volume; keep its defaultalign_corners=True.crop_and_resize(): a window at any box, resampled to a fixed size.CenterCrop: the same windows as an augmentation, for augmentation pipelines; it raises for asizelarger than the input instead of padding.
Examples
>>> input = torch.tensor([[[
...     [1., 2., 3., 4.],
...     [5., 6., 7., 8.],
...     [9., 10., 11., 12.],
...     [13., 14., 15., 16.],
...  ]]])
>>> center_crop(input, (2, 4), mode='nearest', align_corners=True)
tensor([[[[ 5.,  6.,  7.,  8.],
          [ 9., 10., 11., 12.]]]])
- kornia.geometry.transform.crop_and_resize(input_tensor, boxes, size, mode='bilinear', padding_mode='zeros', align_corners=True)[source]#
Crop a four-corner box from each image and resample it to a fixed output size.
patches = crop_and_resize(input_tensor, boxes, size)takes images(B, C, H, W)and boxes(B, 4, 2), one per image or(1, 4, 2)for all of them, and returns the(B, C, h, w)patches forsize = (h, w). The box corners land on the corner pixels of the patch: a rectangle is resized corner to corner, any other quadrilateral is rectified by the homography between the two, and the patch is differentiable with respect to the corners. A single image does not broadcast over a batch of boxes. For an exact integer slice without interpolation, usecrop_by_indices(); to place the crop by a second box,crop_by_boxes(); for volumes,crop_and_resize3d().- Convention:
see Conventions & Pitfalls for the
align_cornersdefaults and sampling rulesa
float16orbfloat16image is cropped infloat32, its homography solved and kept infloat32, and the patches rounded once to the image dtype;float32boxes keep their precisioninput:
(B, C, H, W);sizeis(h, w)boxes:(B, 4, 2)corner points in(x, y)order top-left, top-right, bottom-right, bottom-left; coordinates are inclusive pixel positions (box(1, 1)..``(2, 2)`` selects a \(2 \times 2\) pixel block), origin at top-lefta box axis of one pixel is cropped exactly when
sizeis one pixel on that axis too; one pixel in the box but not insize, or the reverse, has no invertible matrix and returns NaN (a meaningless finite value withmode='nearest'), and so does a box with no homography to the patch, such as a triangle (#4747)
- Parameters:
input_tensor (
Tensor) – the 2D image torch.Tensor with shape(B, C, H, W).boxes (
Tensor) – a torch.Tensor containing the coordinates of the bounding boxes to be extracted. The torch.Tensor must have the shape of(B, 4, 2), where each box is defined in the following (clockwise) order: top-left, top-right, bottom-right and bottom-left. The coordinates must be in the x, y order.size (
Tuple[int,int]) – a tuple with the height and width that will be used to resize the extracted patches.mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – mode for grid_generation. Default:True
- Return type:
- Returns:
the patches, with shape
(B, C, h, w)forsize = (h, w).
See also
crop_by_indices(): integer slicing of axis-aligned boxes, without interpolation.crop_by_boxes(): maps the box onto a second box, whose size sets the output size.crop_and_resize3d(): the same for volumes and(B, 8, 3)boxes; passalign_corners=Truethere.resize(): the whole image; for an image and asizeof at least 2 pixels on each axis, bilinearcrop_and_resizeof the image’s corner box equalsresize(input, size, align_corners=True).RandomResizedCrop: random boxes resized to a fixed size, in an augmentation pipeline.
Example
>>> input = torch.tensor([[[
...     [1., 2., 3., 4.],
...     [5., 6., 7., 8.],
...     [9., 10., 11., 12.],
...     [13., 14., 15., 16.],
... ]]])
>>> boxes = torch.tensor([[
...     [1., 1.],
...     [2., 1.],
...     [2., 2.],
...     [1., 2.],
... ]])  # 1x4x2
>>> crop_and_resize(input, boxes, (2, 2), mode='nearest', align_corners=True)
tensor([[[[ 6.,  7.],
          [10., 11.]]]])
Crop operators (3D)#
Crop (B, C, D, H, W) volumes by (B, 8, 3) boxes, resampled to a fixed size (crop_and_resize3d()) or onto
a second box (crop_by_boxes3d()), by a source→destination voxel matrix (crop_by_transform_mat3d()), or at
the centre (center_crop3d()). Pass align_corners=True: at False the 3D crops sample off the box
(#4503).
- kornia.geometry.transform.crop_by_boxes3d(tensor, src_box, dst_box, interpolation='bilinear', align_corners=False)[source]#
Crop volumes by mapping a source box onto a destination box, whose size sets the output size.
patches = crop_by_boxes3d(tensor, src_box, dst_box)takes volumes(B, C, D, H, W)and two boxes per volume,(B, 8, 3)each (both(1, 8, 3)for all volumes), warps each volume by the affine map that takes the corners ofsrc_boxonto those ofdst_box, which must exist, as it does for any two parallelepipeds or two translated copies of one box, and returns the(B, C, d, h, w)window that starts at voxel(0, 0, 0), where(d, h, w)is the inclusive size ofdst_box; everydst_boxin the batch must have that size. Passalign_corners=True: the defaultFalsesamples off the box (#4503). When the output size is known,crop_and_resize3d()takes it instead of a second box; for images, usecrop_by_boxes().- Convention:
input:
(B, C, D, H, W)src_box/dst_box:(B, 8, 3)corner points in(x, y, z)order, front face then back face, each face top-left, top-right, bottom-right, bottom-left — same convention ascrop_and_resize3d();dst_boxdetermines the output resolutionalign_corners:
Falseby defaultan empty batch has no
dst_boxto read a size from and returns(0, C, 0, 0, 0)
- Parameters:
tensor (
Tensor) – the 3D volume tensor with shape(B, C, D, H, W).src_box (
Tensor) – a tensor with shape(B, 8, 3)containing the coordinates of the bounding boxes to be extracted, where each box is defined in the clockwise order: front-top-left, front-top-right, front-bottom-right, front-bottom-left, back-top-left, back-top-right, back-bottom-right, back-bottom-left. The coordinates must be in x, y, z order.dst_box (
Tensor) – a tensor with shape(B, 8, 3)containing the coordinates of the bounding boxes to be placed, where each box is defined in the clockwise order: front-top-left, front-top-right, front-bottom-right, front-bottom-left, back-top-left, back-top-right, back-bottom-right, back-bottom-left. The coordinates must be in x, y, z order.interpolation (
str, optional) – Interpolation flag. Default:"bilinear"align_corners (
bool, optional) – mode for grid_generation. Default:False
- Return type:
- Returns:
the patches, with shape
(B, C, d, h, w)for the size(d, h, w)ofdst_box.- Raises:
AssertionError – if the boxes of
dst_boxdiffer in size, a box has a non-finite coordinate or edges along one axis that span different extents on it, or no affine map takes asrc_boxonto itsdst_box.
See also
crop_by_boxes(): the same for images and(B, 4, 2)boxes.crop_and_resize3d(): takes the output size assizeand places the box at the patch corners.crop_by_transform_mat3d(): takes the source→destination matrix itself.
Examples
>>> input = torch.tensor([[[
...         [[ 0.,  1.,  2.,  3.],
...          [ 4.,  5.,  6.,  7.],
...          [ 8.,  9., 10., 11.],
...          [12., 13., 14., 15.]],
...         [[16., 17., 18., 19.],
...          [20., 21., 22., 23.],
...          [24., 25., 26., 27.],
...          [28., 29., 30., 31.]],
...         [[32., 33., 34., 35.],
...          [36., 37., 38., 39.],
...          [40., 41., 42., 43.],
...          [44., 45., 46., 47.]]]]])
>>> src_box = torch.tensor([[
...     [1., 1., 1.],
...     [3., 1., 1.],
...     [3., 3., 1.],
...     [1., 3., 1.],
...     [1., 1., 2.],
...     [3., 1., 2.],
...     [3., 3., 2.],
...     [1., 3., 2.],
... ]])  # 1x8x3
>>> dst_box = torch.tensor([[
...     [0., 0., 0.],
...     [2., 0., 0.],
...     [2., 2., 0.],
...     [0., 2., 0.],
...     [0., 0., 1.],
...     [2., 0., 1.],
...     [2., 2., 1.],
...     [0., 2., 1.],
... ]])  # 1x8x3
>>> crop_by_boxes3d(input, src_box, dst_box, interpolation='nearest', align_corners=True)
tensor([[[[[21., 22., 23.],
           [25., 26., 27.],
           [29., 30., 31.]],

          [[37., 38., 39.],
           [41., 42., 43.],
           [45., 46., 47.]]]]])
- kornia.geometry.transform.crop_by_transform_mat3d(tensor, transform, out_size, mode='bilinear', padding_mode='zeros', align_corners=True)[source]#
Crop volumes by a source→destination voxel matrix into a given output size.
patches = crop_by_transform_mat3d(tensor, transform, out_size)takes volumes(B, C, D, H, W)and a source→destination voxel matrix per volume,(B, 3, 4)or(B, 4, 4)(a batch of 1 serves every volume, whichwarp_affine3d()alone does not allow), and returns the(B, C, d, h, w)window that starts at voxel(0, 0, 0)forout_size = (d, h, w). It warps withwarp_affine3d()and uses only the top three rows, so a projective last row is ignored. Unlikecrop_by_transform_mat(), it does not cast the matrix: its dtype must be the volume’s. For images, usecrop_by_transform_mat(); to build the matrix from boxes,crop_by_boxes3d().- Convention:
input:
(B, C, D, H, W);out_sizeis(d, h, w)transformis the source→destination pixel transform, accepted as either(B, 3, 4)affine or(B, 4, 4)homogeneous; only the top three rows are used, so a projective last row is ignored (unlike the 2Dcrop_by_transform_mat())align_corners:
Trueby default;Falsewarps by a matrix normalized for corner-aligned voxels (#4503)
- Parameters:
tensor (
Tensor) – the 3D volume tensor with shape(B, C, D, H, W).transform (
Tensor) – the source->destination pixel transform, either affine with shape(B, 3, 4)or homogeneous with shape(B, 4, 4).out_size (
Tuple[int,int,int]) – size of the output image (depth, height, width).mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – mode for grid_generation. Default:True
- Return type:
- Returns:
the patches, with shape
(B, C, d, h, w).
See also
crop_by_transform_mat(): the same for images, which also applies a projective row.warp_affine3d(): the warp it calls, which takes one(B, 3, 4)matrix per volume.crop_by_boxes3d(): builds the matrix from a source and a destination box.
- kornia.geometry.transform.center_crop3d(tensor, size, interpolation='bilinear', align_corners=True)[source]#
Crop the central window of each volume to a given size.
patches = center_crop3d(tensor, size)takes volumes(B, C, D, H, W)and returns their central(B, C, d, h, w)windows forsize = (d, h, w): with the defaultalign_corners=True, a sub-volume of the input, with the extra voxel of an odd margin at the back/bottom/right. Asizelarger than the input pads with zeros. For images, usecenter_crop(); for a crop at any box,crop_and_resize3d().- Convention:
input:
(B, C, D, H, W);sizeis(d, h, w)align_corners:
Trueby defaultoffset: the crop starts at the integer voxel
int(D / 2 - d / 2)(likewise for the height and width), as inCenterCrop3D, so with the defaultalign_corners=Truethe output is a sub-volume of the input. With an odd margin the extra voxel is left at the back/bottom/right.align_corners=Falseresamples off the voxel grid even for an even margin (seecrop_and_resize3d(), #4503).a
sizemay have one-voxel axes (#4747)
- Parameters:
tensor (
Tensor) – the 3D volume tensor with shape(B, C, D, H, W).size (
Tuple[int,int,int]) – a tuple with the expected depth, height and width of the output patch.interpolation (
str, optional) – Interpolation flag. Default:"bilinear"align_corners (
bool, optional) – mode for grid_generation. Default:True
- Return type:
- Returns:
the central windows, with shape
(B, C, d, h, w).
See also
center_crop(): the central window of each image.crop_and_resize3d(): a window at any box, resampled to a fixed size.CenterCrop3D: the same windows as an augmentation, for augmentation pipelines; it raises for asizelarger than the input instead of padding.
Examples
>>> input = torch.arange(64, dtype=torch.float32).view(1, 1, 4, 4, 4)
>>> input
tensor([[[[[ 0.,  1.,  2.,  3.],
           [ 4.,  5.,  6.,  7.],
           [ 8.,  9., 10., 11.],
           [12., 13., 14., 15.]],

          [[16., 17., 18., 19.],
           [20., 21., 22., 23.],
           [24., 25., 26., 27.],
           [28., 29., 30., 31.]],

          [[32., 33., 34., 35.],
           [36., 37., 38., 39.],
           [40., 41., 42., 43.],
           [44., 45., 46., 47.]],

          [[48., 49., 50., 51.],
           [52., 53., 54., 55.],
           [56., 57., 58., 59.],
           [60., 61., 62., 63.]]]]])
>>> center_crop3d(input, (2, 2, 2), align_corners=True)
tensor([[[[[21.0000, 22.0000],
           [25.0000, 26.0000]],

          [[37.0000, 38.0000],
           [41.0000, 42.0000]]]]])
- kornia.geometry.transform.crop_and_resize3d(tensor, boxes, size, interpolation='bilinear', align_corners=False)[source]#
Crop an eight-corner box from each volume and resample it to a fixed output size.
patches = crop_and_resize3d(tensor, boxes, size)takes volumes(B, C, D, H, W)and boxes(B, 8, 3), one per volume or(1, 8, 3)for all of them, and returns the(B, C, d, h, w)patches forsize = (d, h, w). Each box must be a parallelepiped, so that an affine map takes it onto the patch; withalign_corners=Trueits corners land on the corner voxels of the patch. Passalign_corners=True, since the defaultFalsesamples off the box (#4503). For images, usecrop_and_resize(); to place the crop by a second box,crop_by_boxes3d().- Convention:
input:
(B, C, D, H, W);sizeis(d, h, w)boxes:(B, 8, 3)corner points in(x, y, z)order, front face then back face, each face top-left, top-right, bottom-right, bottom-left — same(x, y)/inclusive-pixel convention ascrop_and_resize(), withzanchored at the top-left of the first depth slice (z = 0); reproducing the exact integer-voxel slice requiresalign_corners=True— the defaultFalseinterpolates insteadalign_corners:
Falseby defaulta single volume does not broadcast over a batch of boxes
a one-voxel axis of an axis-aligned box crops to a one-voxel axis of
size; a one-voxel axis on only one of the two raisestorch.linalg.LinAlgError(#4747)
- Parameters:
tensor (
Tensor) – the 3D volume tensor with shape(B, C, D, H, W).boxes (
Tensor) – a tensor with shape(B, 8, 3)containing the coordinates of the bounding boxes to be extracted, where each box is defined in the clockwise order: front-top-left, front-top-right, front-bottom-right, front-bottom-left, back-top-left, back-top-right, back-bottom-right, back-bottom-left. The coordinates must be in x, y, z order.size (
Tuple[int,int,int]) – a tuple with the depth, height and width that will be used to resize the extracted patches.interpolation (
str, optional) – Interpolation flag. Default:"bilinear"align_corners (
bool, optional) – mode for grid_generation. Default:False
- Return type:
- Returns:
tensor containing the patches with shape
(B, C, d, h, w).- Raises:
AssertionError – if a box has a non-finite coordinate, edges along one axis that span different extents on it, or is not a parallelepiped.
See also
crop_and_resize(): the same for images and(B, 4, 2)boxes, wherealign_cornerschanges only'reflection'padding and, withmode='nearest', which pixel a sample exactly halfway takes.crop_by_boxes3d(): maps the box onto a second box, whose size sets the output size.center_crop3d(): the central window of each volume, withalign_corners=Trueby default.
Example
>>> input = torch.arange(64, dtype=torch.float32).view(1, 1, 4, 4, 4)
>>> input
tensor([[[[[ 0.,  1.,  2.,  3.],
           [ 4.,  5.,  6.,  7.],
           [ 8.,  9., 10., 11.],
           [12., 13., 14., 15.]],

          [[16., 17., 18., 19.],
           [20., 21., 22., 23.],
           [24., 25., 26., 27.],
           [28., 29., 30., 31.]],

          [[32., 33., 34., 35.],
           [36., 37., 38., 39.],
           [40., 41., 42., 43.],
           [44., 45., 46., 47.]],

          [[48., 49., 50., 51.],
           [52., 53., 54., 55.],
           [56., 57., 58., 59.],
           [60., 61., 62., 63.]]]]])
>>> boxes = torch.tensor([[
...     [1., 1., 1.],
...     [3., 1., 1.],
...     [3., 3., 1.],
...     [1., 3., 1.],
...     [1., 1., 2.],
...     [3., 1., 2.],
...     [3., 3., 2.],
...     [1., 3., 2.],
... ]])  # 1x8x3
>>> crop_and_resize3d(input, boxes, (2, 2, 2), align_corners=True)
tensor([[[[[21.0000, 23.0000],
           [29.0000, 31.0000]],

          [[37.0000, 39.0000],
           [45.0000, 47.0000]]]]])
Modules#
The torch.nn.Module classes. Module forms that store their arguments: the 2D transforms (Rotate,
Translate, Scale, Shear, Affine), the resizes (Resize, Rescale),
the pyramid steps (PyrDown, PyrUp) and the centre crop (CenterCrop2D); module forms that
take no arguments: the flips (Hflip, Vflip, Rot180). ScalePyramid builds
scale-space octaves, HomographyWarper warps by a normalized homography, and BaseWarper is the
interface for writing another warper.
- class kornia.geometry.transform.Rotate(angle, center=None, mode='bilinear', padding_mode='zeros', align_corners=True)[source]#
Rotate an image counter-clockwise by a stored angle in degrees (module form).
Build
rotator = Rotate(angle), optionally withcenter, thenout = rotator(input)rotates(C, H, W)or(B, C, H, W)images asrotate()does: counter-clockwise as displayed, about the image centre by default, at the input size. For volumes, userotate3d(); to rotate, shift, scale and shear in one warp,Affine.- Convention:
See the convention block of
rotate().
- Parameters:
angle (
Tensor) – The angle through which to rotate. The tensor must have a shape of (B), where B is batch size.center (
Optional[Tensor], optional) – The center through which to rotate. The tensor must have a shape of (B, 2), where B is batch size and last dimension contains cx and cy. Default:Nonemode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – interpolation flag. Default:True
- Returns:
The rotated tensor with the same shape as the input.
See also
Example
>>> img = torch.rand(1, 3, 4, 4)
>>> angle = torch.tensor([90.])
>>> out = Rotate(angle)(img)
>>> print(out.shape)
torch.Size([1, 3, 4, 4])
- class kornia.geometry.transform.Translate(translation, mode='bilinear', padding_mode='zeros', align_corners=True)[source]#
Shift an image by a stored translation in pixels (module form).
Build
shifter = Translate(translation), thenout = shifter(input)shifts(C, H, W)or(B, C, H, W)images by the(B, 2)translation(dx, dy)in pixels, astranslate()does. To combine the shift with a rotation, a scale and a shear, useAffine.- Convention:
See the convention block of
translate().
- Parameters:
translation (
Tensor) – tensor containing the amount of pixels to translate in the x and y direction. The tensor must have a shape of (B, 2), where B is batch size, last dimension contains dx dy.mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – interpolation flag. Default:True
- Returns:
The translated tensor with the same shape as the input, except that one image shifted by
B > 1translations returns(B, C, H, W).
See also
translate(): the one-call form.Affine: a translation with a rotation, a scale and a shear in one warp.
Example
>>> img = torch.rand(1, 3, 4, 4)
>>> translation = torch.tensor([[1., 0.]])
>>> out = Translate(translation)(img)
>>> print(out.shape)
torch.Size([1, 3, 4, 4])
- class kornia.geometry.transform.Scale(scale_factor, center=None, mode='bilinear', padding_mode='zeros', align_corners=True)[source]#
Zoom an image about its centre by a stored scale factor, keeping its size (module form).
Build
zoomer = Scale(scale_factor), optionally withcenter, thenout = zoomer(input)scales the content of(C, H, W)or(B, C, H, W)images asscale()does, at the input size. To change the image size instead, useRescaleorResize.- Convention:
See the convention block of
scale().
- Parameters:
scale_factor (
Tensor) – The scale factor apply. The tensor must have a shape of (B) or (B, 2), where B is batch size. If (B), isotropic scaling will perform. If (B, 2), x-y-direction specific scaling will perform.center (
Optional[Tensor], optional) – The center through which to scale. The tensor must have a shape of (B, 2), where B is batch size and last dimension contains cx and cy. Default:Nonemode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – interpolation flag. Default:True
- Returns:
The scaled tensor with the same shape as the input.
See also
Example
>>> img = torch.rand(1, 3, 4, 4)
>>> scale_factor = torch.tensor([[2., 2.]])
>>> out = Scale(scale_factor)(img)
>>> print(out.shape)
torch.Size([1, 3, 4, 4])
- class kornia.geometry.transform.Shear(shear, mode='bilinear', padding_mode='zeros', align_corners=True)[source]#
Shear an image by stored raw shear factors about pixel (0, 0) (module form).
Build
shearer = Shear(shear), thenout = shearer(input)shears(C, H, W)or(B, C, H, W)images by the(B, 2)raw factors(shx, shy), asshear()does, except thatalign_cornersdefaults toTruehere and toFalsein the function. For shear angles in radians about the image centre, useAffine, which shears by their negative tangent, so values belowpi / 2in magnitude shear the other way there.- Convention:
- Parameters:
shear (
Tensor) – tensor containing raw shear factors in the x and y direction about pixel (0, 0). The tensor must have a shape of (B, 2), where B is batch size, last dimension contains shx shy.mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – interpolation flag. Default:True
- Returns:
The skewed tensor with the same shape as the input, except that one image sheared by
B > 1pairs of factors returns(B, C, H, W).
See also
Example
>>> img = torch.rand(1, 3, 4, 4)
>>> shear_factor = torch.tensor([[0.5, 0.0]])
>>> out = Shear(shear_factor)(img)
>>> print(out.shape)
torch.Size([1, 3, 4, 4])
- class kornia.geometry.transform.PyrDown(border_type='reflect', align_corners=False, factor=2.0)[source]#
Blur images with the 5x5 pyramid kernel and downsample them by a factor (module form).
Build
down = PyrDown(), optionally withborder_type,align_cornersandfactor, thenout = down(input)blurs(B, C, H, W)images and resizes them tofloor(H / factor)byfloor(W / factor), aspyrdown()does. For the step up, usePyrUp; for every level at once,build_pyramid().- Convention:
See the convention block of
pyrdown().
- Parameters:
border_type (
str, optional) – the padding mode to be applied before convolving. The expected modes are:'constant','reflect','replicate'or'circular'. Default:"reflect"align_corners (
bool, optional) – interpolation flag. Default:Falsefactor (
float, optional) – the downsampling factor Default:2.0
- Returns:
the downsampled torch.Tensor.
- Shape:
Input:
(B, C, H, W)Output:
(B, C, H // 2, W // 2)at the defaultfactor=2.0
Examples
>>> input = torch.rand(1, 2, 4, 4)
>>> output = PyrDown()(input)  # 1x2x2x2
- class kornia.geometry.transform.PyrUp(border_type='reflect', align_corners=False)[source]#
Upsample images to twice their size and blur them with the 5x5 pyramid kernel (module form).
Build
up = PyrUp(), optionally withborder_typeandalign_corners, thenout = up(input)resizes(B, C, H, W)images to(B, C, H * 2, W * 2)and blurs them, aspyrup()does. For the step down, usePyrDown.- Convention:
See the convention block of
pyrup().
- Parameters:
- Returns:
the upsampled torch.Tensor.
- Shape:
Input:
(B, C, H, W)Output:
(B, C, H * 2, W * 2)
Examples
>>> input = torch.rand(1, 2, 4, 4)
>>> output = PyrUp()(input)  # 1x2x8x8
- class kornia.geometry.transform.ScalePyramid(n_levels=3, init_sigma=1.6, min_size=15, double_image=False, extra_levels=3)[source]#
Build octaves of progressively blurred images, with their sigmas, for scale-space detection.
Build
sp = ScalePyramid(n_levels, init_sigma, min_size), thenpyr, sigmas, pixel_dists = sp(input)takes(B, C, H, W)images and returns three lists with one entry per octave.pyr[o]stacksL = n_levels + extra_levelslevels as(B, C, L, H_o, W_o), each blurred2 ** (1 / n_levels)times more than the previous, andsigmas[o]andpixel_dists[o]are(B, L). Each octave after the first starts from leveln_levelsof the previous one, resized to half its size, and octaves are added while that halved size stays abovemin_sizeon its shorter side. It is the pyramidScaleSpaceDetectorsearches; for a plain list of halved images, usebuild_pyramid().- Convention:
input:
(B, C, H, W)forwardreturns(pyr, sigmas, pixel_dists), one entry per octave:pyr[o]is(B, C, L, H_o, W_o)withL = n_levels + extra_levels, andsigmas[o]andpixel_dists[o]are(B, L)nominal values (the targeted blur, not a measurement)sigmasis octave-relative: the blur in input pixels issigmas[o] * pixel_dists[o]an
init_sigmabelow the assumed input blur (0.5, or1.0withdouble_image=True) leaves the first level at that blur, and the octave is built and labelled from it, as ifinit_sigmawere the assumed input blurthe internal resizes use
align_corners=True; there is noalign_cornersparameter. They keep the first and last pixel centres, so pixel \((u, v)\) of octaveois input pixel \((u (W - 1) / (W_o - 1), v (H - 1) / (H_o - 1))\);pixel_distsis the nominal spacing \(2^o\) (\(2^{o - 1}\) withdouble_image=True), not this map
- Parameters:
n_levels (
int, optional) – number of levels per octave over which the blur doubles, a positive integer (a NumPy integer or integer tensor is converted toint). Each level is blurred2 ** (1 / n_levels)times more than the one before. Default:3init_sigma (
float, optional) – initial blur level. Default:1.6min_size (
int, optional) – the minimum size of the octave in pixels, a non-negative number: an octave after the first is built only when its shorter side is larger thanmin_size, so0halves the image down to one pixel. Default:15double_image (
bool, optional) – add 2x upscaled image as 1st level of pyramid. OpenCV SIFT does this. Default:Falseextra_levels (
int, optional) – number of levels per octave beyondn_levels, a positive integer (a NumPy integer or integer tensor is converted toint); the default 3 is what DoG non-maximum suppression needs. Leveln_levels, blurred to twice the first level’s sigma, seeds the next octave, so1is the least that works. Default:3
- Returns:
images, the levels of each octave. 2nd output: sigmas, the nominal blur of each level in the octave’s own pixels. 3rd output: pixel_dists, the nominal pixel spacing of each level relative to the input.
- Return type:
1st output
- Raises:
ValueCheckError – if
n_levelsorextra_levelsis not a positive integer, ormin_sizeis negative or NaN. Raised even when theKORNIA_CHECKhelpers are disabled, becauseforwardcould not build the pyramid.
- Shape:
Input:
(B, C, H, W)Output 1st:
[(B, C, L, H, W), (B, C, L, H // 2, W // 2), ...], starting from(B, C, L, H * 2, W * 2)withdouble_image=TrueOutput 2nd:
[(B, L), (B, L), (B, L), ...]Output 3rd:
[(B, L), (B, L), (B, L), ...]
See also
build_pyramid(): a list of halved images, one blur per level, without sigmas.build_laplacian_pyramid(): band-pass levels for reconstruction rather than detection.ScaleSpaceDetector: detects keypoints in this pyramid.
Examples
>>> input = torch.rand(2, 4, 100, 100)
>>> sp, sigmas, pds = ScalePyramid(3, 15)(input)
- class kornia.geometry.transform.Hflip(*args, **kwargs)[source]#
Mirror images left to right by reversing the width axis (module form).
Build
flipper = Hflip(), which takes no arguments, thenout = flipper(input)reverses the columns of(*, W)tensors ashflip()does. To flip top to bottom, useVflip; for a half turn,Rot180.- Convention:
See the convention block of
hflip().
- Returns:
The horizontally flipped image torch.Tensor, with the shape of the input.
See also
hflip(): the one-call form.Vflip: flips top to bottom instead.RandomHorizontalFlip: flips with a probability, in an augmentation pipeline.
Examples
>>> hflip = Hflip()
>>> input = torch.tensor([[[
...    [0., 0., 0.],
...    [0., 0., 0.],
...    [0., 1., 1.]
... ]]])
>>> hflip(input)
tensor([[[[0., 0., 0.],
          [0., 0., 0.],
          [1., 1., 0.]]]])
- class kornia.geometry.transform.Vflip(*args, **kwargs)[source]#
Flip images top to bottom by reversing the height axis (module form).
Build
flipper = Vflip(), which takes no arguments, thenout = flipper(input)reverses the rows of(*, H, W)tensors asvflip()does. To mirror left to right, useHflip; for a half turn,Rot180.- Convention:
See the convention block of
vflip().
- Returns:
The vertically flipped image torch.Tensor, with the shape of the input.
See also
vflip(): the one-call form.Hflip: mirrors left to right instead.RandomVerticalFlip: flips with a probability, in an augmentation pipeline.
Examples
>>> vflip = Vflip()
>>> input = torch.tensor([[[
...    [0., 0., 0.],
...    [0., 0., 0.],
...    [0., 1., 1.]
... ]]])
>>> vflip(input)
tensor([[[[0., 1., 1.],
          [0., 0., 0.],
          [0., 0., 0.]]]])
- class kornia.geometry.transform.Rot180(*args, **kwargs)[source]#
Turn images by 180 degrees by reversing the height and width axes (module form).
Build
rotator = Rot180(), which takes no arguments, thenout = rotator(input)reverses both the rows and the columns of(*, H, W)tensors asrot180()does, without interpolation. To rotate by a stored angle, useRotate.- Convention:
See the convention block of
rot180().
- Returns:
The rotated image torch.Tensor, with the shape of the input.
Examples
>>> rot180 = Rot180()
>>> input = torch.tensor([[[
...    [0., 0., 0.],
...    [0., 0., 0.],
...    [0., 1., 1.]
... ]]])
>>> rot180(input)
tensor([[[[1., 1., 0.],
          [0., 0., 0.],
          [0., 0., 0.]]]])
- class kornia.geometry.transform.Resize(size, interpolation='bilinear', align_corners=None, side='short', antialias=False)[source]#
Resize an image to a given size, or one side to a given length (module form).
Build
resizer = Resize(size)with the arguments ofresize(), thenout = resizer(input)resizes(*, H, W)tensors exactly asresize(input, size, ...)does. For a factor instead of a size, useRescale; inside an augmentation pipeline, useResize.- Convention:
See Conventions & Pitfalls for sampling and
align_cornersconventions. When resizing camera images, see camera and world conventions for matching intrinsics scaling.See the convention block of
resize().
- Parameters:
size (
Union[int,Tuple[int,int]]) – Desired output size. If size is a sequence like (h, w), output size will be matched to this. If size is an int, the side thatsidenames will be matched to this number; with the defaultside='short', if height > width, the image will be rescaled to (size * height / width, size)interpolation (
str, optional) – algorithm used for upsampling:'nearest'|'nearest-exact'|'bilinear'|'bicubic'|'area'. Default:"bilinear"align_corners (
Optional[bool], optional) – interpolation flag. Default:Noneside (
str, optional) – Corresponding side ifsizeis an integer. Can be one of'short','long','vert', or'horz'. Default:"short"antialias (
bool, optional) – if True, then image will be filtered with Gaussian before downscaling. No effect for upscaling. Default:False
- Returns:
The resized tensor with the shape of the given size.
See also
Example
>>> img = torch.rand(1, 3, 4, 4)
>>> out = Resize((6, 8))(img)
>>> print(out.shape)
torch.Size([1, 3, 6, 8])
- class kornia.geometry.transform.Rescale(factor, interpolation='bilinear', align_corners=True, antialias=False)[source]#
Resize an image by a stored scale factor per side, given height first (module form).
Build
rescaler = Rescale(factor), thenout = rescaler(input)resizes(*, H, W)tensors asrescale()does, except thatalign_cornersdefaults toTruehere and toNonein the function. For a size instead of a factor, useResize.- Convention:
align_corners:
Trueby default (differs from functionrescale(), whose default isNone). It applies to the'bilinear'and'bicubic'modes only.'nearest','nearest-exact'and'area'ignore it, an explicitalign_corners=Trueincluded, becausetorch.nn.functional.interpolateaccepts no value butNonefor them; the functionrescale()raisesValueErrorfor such a call.See the convention block of
rescale().
- Parameters:
factor (
Union[float,Tuple[float,float]]) – Desired scaling factor as(factor_h, factor_w)— height first. If a single float, the value is used for both height and width (anintraisesTypeError).interpolation (
str, optional) – algorithm used for upsampling:'nearest'|'nearest-exact'|'bilinear'|'bicubic'|'area'. Default:"bilinear"align_corners (
bool, optional) – interpolation flag. Default:Trueantialias (
bool, optional) – if True, then image will be filtered with Gaussian before downscaling. No effect for upscaling. Default:False
- Returns:
The rescaled tensor with the shape according to the given factor.
See also
Example
>>> img = torch.rand(1, 3, 4, 4)
>>> out = Rescale((2, 3))(img)
>>> print(out.shape)
torch.Size([1, 3, 8, 12])
- class kornia.geometry.transform.Affine(angle=None, translation=None, scale_factor=None, shear=None, center=None, mode='bilinear', padding_mode='zeros', align_corners=True)[source]#
Warp an image by a rotation, a scale and a shear about a centre, then a translation (module form).
Build
warper = Affine(angle, translation, scale_factor, shear, center)with at least one of the first four, thenout = warper(input)warps(B, C, H, W)images, or one(C, H, W)image, by the matrix ofget_affine_matrix2d(): a shear, a scale, a counter-clockwise rotation in degrees and a translation in pixels, the first three aboutcenter(by default the image centre). The parameters, andcenterwhen given, share one batch sizeP.Pand the input batch must be equal, or one of them 1, a(C, H, W)input counting as 1: one parameter set warps every image, andPsets warp one image. For a matrix you already have, useaffine(); for one kind of warp,Rotate,Translate,ScaleorShear.- Convention:
shearcontains angles in radians, using the negative-tangent, x-then-y convention ofget_shear_matrix2d()aboutcenter(by default((W - 1) / 2, (H - 1) / 2)).Known defect:
shear()andShearread theirshearas raw factors about pixel(0, 0), without the negative tangent, so the same tensor shears the other way there while its values stay belowpi / 2in magnitude (#5661).align_cornersdefaults toTrue. See the convention block ofaffine().
- Parameters:
angle (
Optional[Tensor], optional) – Angle in degrees for counter-clockwise rotation around the center. The tensor must have a shape of (B), where B is the batch size. Default:Nonetranslation (
Optional[Tensor], optional) – Amount of pixels for translation in x- and y-direction. The tensor must have a shape of (B, 2), where B is the batch size and the last dimension contains dx and dy. Default:Nonescale_factor (
Optional[Tensor], optional) – Factor for scaling. The tensor must have a shape of (B,2), where B is the batch size and the last dimension contains scale factors for x and y direction. Default:Noneshear (
Optional[Tensor], optional) – Angles in radians for shearing in x- and y-direction around the center. The tensor must have a shape of (B, 2), where B is the batch size and the last dimension contains sx and sy. Default:Nonecenter (
Optional[Tensor], optional) – Transformation center in pixels. The tensor must have a shape of (B, 2), where B is the batch size and the last dimension contains cx and cy. Defaults to the center of image to be transformed. Default:Nonemode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"align_corners (
bool, optional) – interpolation flag. Default:True
- Raises:
RuntimeError – At construction, if not one of
angle,translation,scale_factor, orshearis set, or if their batch sizes differ.DeviceError – If
angle,translation,scale_factorandshearare not all on one device.TypeCheckError – If they are on one device but do not all have one dtype. The ones not given are created on that device and in that dtype.
ValueError – At the call, if
centerand the parameters have different batch sizes (construction does not checkcenter), or if the parameter batch and the input batch differ and neither is 1, a(C, H, W)input counting as 1.
- Returns:
The transformed tensor with same shape as input, except that one image warped by
P > 1parameter sets returns(P, C, H, W).
See also
get_affine_matrix2d(): the(B, 3, 3)matrix this module warps by, whose own angle turns clockwise (#4408).affine(): warp by an affine matrix you already have.Rotate: a rotation alone.Shear: raw shear factors about pixel(0, 0), which shear the other way belowpi / 2.
Example
>>> img = torch.rand(1, 2, 3, 5)
>>> angle = 90. * torch.rand(1)
>>> out = Affine(angle)(img)
>>> print(out.shape)
torch.Size([1, 2, 3, 5])
- class kornia.geometry.transform.BaseWarper(height, width, *args, **kwargs)[source]#
Declare the interface of a homography warper module that ImageRegistrator can call.
BaseWarper(height, width)only stores the destinationheightandwidth. A subclass implementswarper(patch_src, src_homo_dst), which samples a(B, C, H, W)source on that destination grid by a(B, 3, 3)destination→source homography, andprecompute_warp_grid(src_homo_dst), which caches the grid.ImageRegistratortakes such a class aswarperand calls it aswarper(height, width). Both methods are abstract: constructingBaseWarperitself, or a subclass that does not implement both, raisesTypeError. To warp images, useHomographyWarper.- Convention:
subclasses receive
src_homo_dstas the destination→source homography
See also
HomographyWarper: the implementation kornia ships, in normalized or pixel coordinates.ImageRegistrator: registers two images by optimizing a transform, and warps with a warper class of this interface.
- class kornia.geometry.transform.HomographyWarper(height, width, mode='bilinear', padding_mode='zeros', normalized_coordinates=True, align_corners=False)[source]#
Warp images to a fixed size by a normalized destination→source homography (module form).
Build
warper = HomographyWarper(height, width), thenout = warper(patch_src, src_homo_dst)warps(N, C, H, W)images by(N, 3, 3)destination→source homographies in normalized \([-1, 1]\) coordinates and returns(N, C, height, width), ashomography_warp()withdsize=(height, width)does. To reuse one homography, callwarper.precompute_warp_grid(src_homo_dst)once and thenwarper(patch_src); a homography passed to the call takes precedence over the cached grid, and a call with neither raisesRuntimeError. For a source→destination homography in pixel coordinates, asRANSACandfind_homography_dlt()return it, usewarp_perspective(). This class has nonormalized_homographyswitch:normalized_coordinates=Falsestill reads a destination→source homography, in pixels.\[X_{src} = H_{src}^{\{dst\}} * X_{dst}\]- Convention:
See Conventions & Pitfalls for homography direction, normalized coordinates and sampling conventions.
See the convention block of
homography_warp().with
normalized_coordinates=Falsea grid fromprecompute_warp_gridholds source pixel coordinates computed as inhomography_warp()(in at least float32, unaffected by autocast), normalized at sampling time with the size of the patch passed toforwardand then cast to the homography’s dtype
- Parameters:
height (
int) – The height of the destination torch.Tensor.width (
int) – The width of the destination torch.Tensor.mode (
str, optional) – interpolation mode to calculate output values'bilinear'|'nearest'. Default:"bilinear"padding_mode (
str, optional) – padding mode for outside grid values'zeros'|'border'|'reflection'. Default:"zeros"normalized_coordinates (
bool, optional) – whether the homographies are in normalized \([-1, 1]\) coordinates (True) or in pixel coordinates (False), as inhomography_warp(). Default:Truealign_corners (
bool, optional) – interpolation flag. Default:False
See also
homography_warp(): the one-call form, with anormalized_homographyswitch for pixel source→destination homographies.warp_perspective(): takes the source→destination homography in pixel coordinates.BaseWarper: the interface this class implements, forImageRegistrator.ImageRegistrator: fits a homography between two images, warping with this class by default.
- class kornia.geometry.transform.CenterCrop2D(size, align_corners=True, resample=Resample.BILINEAR.name, cropping_mode='slice')[source]#
Crop the central window of each image to a given size, by slicing or resampling (module form).
Build
cropper = CenterCrop2D(size)with anintor an(h, w)tuple, thenout = cropper(input)returns the central(B, C, h, w)windows of(B, C, H, W)images, at the offsets ofcenter_crop(). The defaultcropping_mode='slice'slices with integer indices, throughcrop_by_indices(), or after zero-padding whensizeexceeds the input on an axis;'resample'samples the same windows, up to float rounding, by a translation throughwarp_affine()with theresamplemode. For one call, usecenter_crop(); in an augmentation pipeline,CenterCrop.- Convention:
align_corners(andresample) only take effect whencropping_mode='resample'; the defaultcropping_mode='slice'performs integer-index slicing and ignores bothSee the convention block of
center_crop().
- Parameters:
size (
Union[int,Tuple[int,int]]) – Size(h, w)in pixels of the cropped region, or oneintfor both sides; a list raisesTypeError.align_corners (
bool, optional) – interpolation flag. Default:Trueresample (
Union[str,int,Resample], optional) – Resampling mode. Default:Resample.BILINEAR.namecropping_mode (
str, optional) – Cropping mode, “resample” or “slice”. Default:"slice"
Note
torch.jit.scriptcompiles neither cropping mode, andtorch.jit.tracerecords the crop offsets of the traced input size.See also
center_crop(): the one-call form, which always resamples.crop_by_indices(): the integer slicing of the default mode, for any axis-aligned box.CenterCrop: the same windows as an augmentation, for augmentation pipelines; it raises for asizelarger than the input instead of padding.
Image registration#
See also the image registration application page.
Register two images by optimizing a homography or a similarity by gradient descent, coarse to fine.
ImageRegistrator takes a pair of (1, C, H, W) images, builds a Gaussian pyramid of each with
build_pyramid() and, from the coarsest level to the finest, optimizes a transform
model on the loss of each image warped onto the other. The built-in models return a (1, 3, 3) destination→source
matrix in normalized \([-1, 1]\) coordinates (align_corners=False): the src_homo_dst of
homography_warp() and HomographyWarper.
Which class to use:
Register two images:
ImageRegistrator, withmodel_type'homography','similarity','translation','rotation'or'scale'.The models it optimizes:
Homography(a full homography) andSimilarity(a rotation, a scale and a shift, each one optional). A custom model subclassesBaseModeland comes with a warper class, such as a subclass ofBaseWarper.To estimate a homography from matched keypoints rather than from pixel values, use
RANSACorfind_homography_dlt().
- class kornia.geometry.transform.image_registrator.BaseModel(*args, **kwargs)[source]#
Declare the interface of a transform model that ImageRegistrator optimizes.
A subclass holds its transform parameters as
Parameterand implementsreset_model(), which returns them to the identity,forward(), the matrix with which its warper warps the source image into the destination, andforward_inverse(), the matrix of the reverse warp.ImageRegistratortakes an instance asmodel_type, together with awarperclass. The three methods are abstract: constructingBaseModelitself, or a subclass that does not implement all three, raisesTypeError, as forBaseWarper. For the built-in models, useHomographyorSimilarity.See also
Homography: the built-in model of a full homography.Similarity: the built-in model of a rotation, a scale and a shift.ImageRegistrator: optimizes a model of this interface.
- abstractmethod forward()[source]#
Return the transform used to warp the source image into the destination image.
The built-in models map destination coordinates to source coordinates. A custom model’s coordinates must match its supplied warper; see
ImageRegistrator.- Return type:
- Returns:
Transform tensor for the current model state, in the shape required by the warper.
- class kornia.geometry.transform.image_registrator.Homography[source]#
Hold a learnable 3x3 homography for ImageRegistrator, starting from the identity.
model = Homography()holds one(3, 3)Parameter, initialized to the identity.model()returns it as a(1, 3, 3)matrix scaled so that its[2, 2]entry is 1, andmodel.forward_inverse()its inverse, up to scale.ImageRegistrator('homography')optimizes it as the destination→source homography in normalized coordinates. For a rotation, a scale and a shift only, useSimilarity.See also
Similarity: four degrees of freedom instead of eight, each of rotation, scale and shift optional.ImageRegistrator: optimizes this model withmodel_type='homography'.
- forward()[source]#
Single-batch homography, scaled so that its
[2, 2]entry is 1.- Return type:
- Returns:
Homography matrix with shape
(1, 3, 3).
- class kornia.geometry.transform.image_registrator.ImageRegistrator(model_type='homography', optimizer=optim.Adam, loss_fn=F.l1_loss, pyramid_levels=5, lr=1e-3, num_iterations=100, tolerance=1e-4, warper=None, allow_shape_mismatch=False)[source]#
Register two images by optimizing a transform model on their Gaussian pyramids, coarse to fine.
Build
registrator = ImageRegistrator(model_type), thenM = registrator.register(src_img, dst_img)takes two(1, C, H, W)images (the built-in models hold one transform, and a larger batch raises). From the coarsest ofpyramid_levelsGaussian levels to the finest, it runs up tonum_iterationssteps ofoptimizeron the masked loss ofsrc_imgwarped ontodst_imgplusdst_imgwarped back ontosrc_img, and returns the model’s matrix,(1, 3, 3)for the built-in models (with the matrix after each level as well, whenoutput_intermediate_models=True);warp_src_into_dst()then warps an image by it. With more than one level, both sides need at least2 ** (pyramid_levels - 1)pixels, 16 for the default 5. To align images from matched keypoints instead, useRANSAC.- Convention:
register()returnsself.model()unchanged. For the built-in stringmodel_typevalues, this maps destination coordinates to source coordinates, normalized to \([-1, 1]\) withalign_corners=False: thesrc_homo_dstargument ofhomography_warp().warp_src_into_dst()uses this model, andwarp_dst_into_src()usesself.model.forward_inverse(). A custommodel_typeandwarperdetermine their own coordinate system; their forward and inverse mappings must agree with that warper.For the built-in models,
denormalize_homography(M, (H, W), (H, W), align_corners=False)converts the returnedMto pixels: content that moves by \((t_x, t_y)\) pixels fromsrc_imgtodst_imggives a shift of \((-t_x, -t_y)\).register()always starts from the identity, so a loadedstate_dictdrives the warps but is not a warm start.A
float16/bfloat16model or image is optimized infloat32: duringregister()both images, also whenallow_shape_mismatchresizessrc_img, and the model’s half parameters and buffers arefloat32, and afterwards those tensors and their gradients return to their own dtype, also whenregister()raises. Adam’s second-moment estimate0.001 * g**2and itsepsof1e-8are both 0 infloat16once|g| < 0.0055, so afloat16optimization divides by zero and ends in NaN, andbfloat16steps round to the dtype’s coarse spacing. For a half model the intermediate models ofoutput_intermediate_modelsare computed infloat32and rounded to the model’s dtype, so the last one can differ by an ulp from the returnedself.model(), which is computed in the model’s dtype.A
float16,bfloat16orfloat32model therefore registers images of any of these dtypes.warp_src_into_dst()andwarp_dst_into_src()sample a model and an image of two different ones of them infloat32too and return the image’s dtype; a model and an image of the same dtype go to the warper unchanged, as before.
- Parameters:
model_type (
Union[str,BaseModel], optional) – Geometrical model for registration:'homography','similarity', or'translation','rotation'or'scale'(aSimilaritythat optimizes only that parameter), or aBaseModelinstance together withwarper. Default:"homography"optimizer (
Type[Optimizer], optional) – optimizer class used for the optimization. Default:optim.Adamloss_fn (
Callable[...,Tensor], optional) – torch loss function, called withreduction='none'. Default:F.l1_losspyramid_levels (
int, optional) – number of scale pyramid levels. Default:5lr (
float, optional) – learning rate for optimization. Default:1e-3num_iterations (
int, optional) – maximum number of iterations at each pyramid level, from coarse to fine. Default:100tolerance (
float, optional) – stop a pyramid level when successive losses at that level differ by less than this value. The first iteration at each level always runs. Default 1e-4. Default:1e-4warper (
Optional[Type[BaseWarper]], optional) – the warper class, called aswarper(height, width). Required whenmodel_typeis a module; a stringmodel_typeusesHomographyWarper. Default:Noneallow_shape_mismatch (
bool, optional) – if True,register()resizessrc_imgbilinearly to the height and width ofdst_img, and a different batch or channel size still raisesValueError; if False, images of different shapes raiseValueError. Default:False
See also
Homography: the model ofmodel_type='homography'.Similarity: the model of the other stringmodel_typevalues.HomographyWarper: the warper of the built-in models.RANSAC: a homography from matched keypoints, robust to outliers.
Example
>>> from kornia.geometry import ImageRegistrator
>>> img_src = torch.rand(1, 1, 32, 32)
>>> img_dst = torch.rand(1, 1, 32, 32)
>>> registrator = ImageRegistrator('similarity')
>>> homo = registrator.register(img_src, img_dst)
- get_single_level_loss(img_src, img_dst, transform_model)[source]#
Warp img_src into img_dst with transform_model and returns loss.
- Return type:
- register(src_img, dst_img, verbose=False, output_intermediate_models=False)[source]#
Estimate the transformation which warps src_img into dst_img by gradient descent.
- Parameters:
- Return type:
- Returns:
the transformation between two images, shape depends on the model, typically [1x3x3] torch.Tensor for string model_types.
- warp_dst_inro_src(dst_img)[source]#
Deprecated alias for
warp_dst_into_src().- Return type:
- class kornia.geometry.transform.image_registrator.Similarity(rotation=True, scale=True, shift=True)[source]#
Hold a learnable rotation, scale and shift for ImageRegistrator, each one optional.
model = Similarity(rotation, scale, shift)holds an anglerotin degrees, ascaleand a(1, 2, 1)shiftin normalized units, each aParameterwhen its flag isTrueand otherwise a constant buffer (0, 1 and 0).model()returns the(1, 3, 3)matrix described below andmodel.forward_inverse()its inverse.ImageRegistratoruses it for'similarity'(all three),'translation'(the shift),'rotation'and'scale'. For a full homography, useHomography.- Convention:
forward()is[[scale * R, shift], [0, 0, 1]]in the normalized \([-1, 1]\) coordinates ofImageRegistrator(align_corners=False), whereRcomes fromangle_to_rotation_matrix()ofrotin degrees.After
set_image_shape()with the image heightHand widthW,Risdiag(H / W, 1) @ angle_to_rotation_matrix(rot) @ diag(W / H, 1). The normalized frame scales x by2 / Wand y by2 / H, so in pixels the linear part is thenscale * angle_to_rotation_matrix(rot)about the image centre, for any aspect ratio.ImageRegistrator.register()sets the shape ofdst_img.shiftstays in normalized units.Without an image shape,
Risangle_to_rotation_matrix(rot), which rotates the pixels only on a square image. The shape is not part ofstate_dict(): afterload_state_dict, callset_image_shape()again before using the model on a non-square image.
- Parameters:
See also
Homography: a full homography, eight degrees of freedom.ImageRegistrator: optimizes this model for everymodel_typebut'homography'.
- forward()[source]#
Single-batch similarity transform.
- Return type:
- Returns:
Similarity with shape
(1, 3, 3)