

kornia.geometry.epipolar#
Functions for epipolar geometry, as used in Structure from Motion (SfM) and two-view pose estimation.
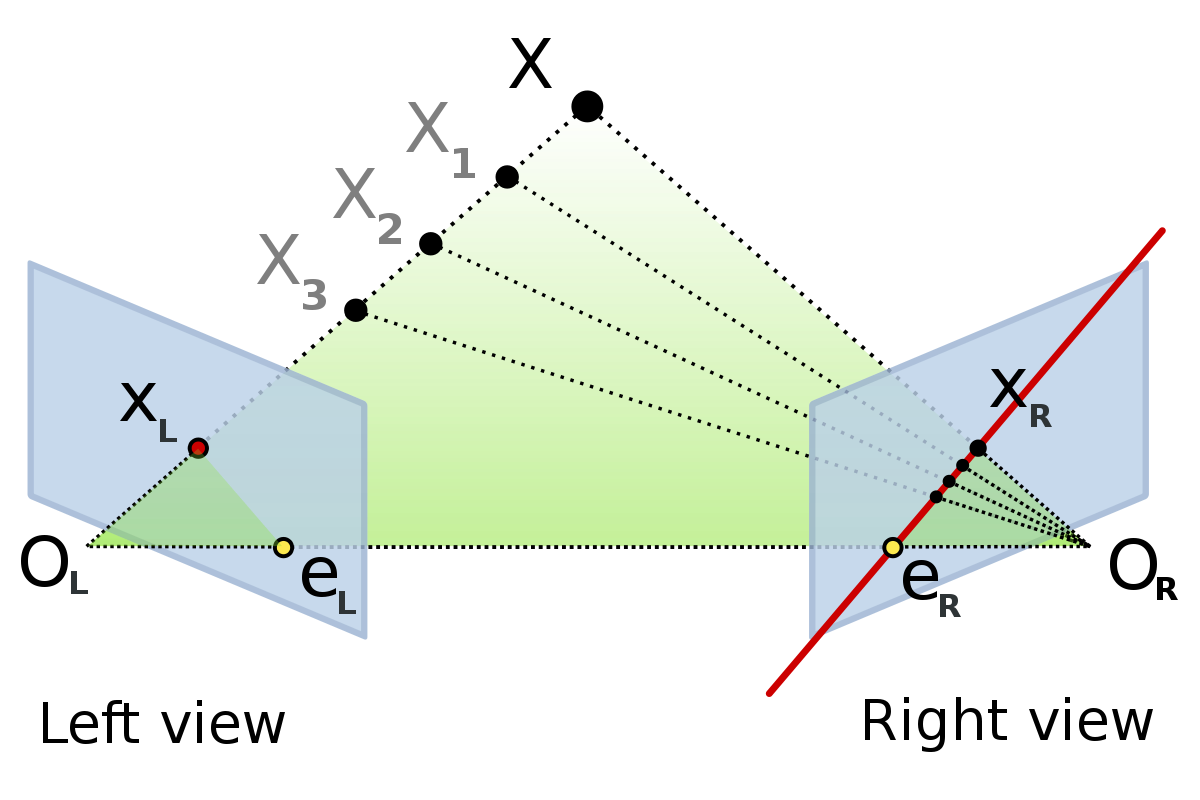
Essential#
- kornia.geometry.epipolar.find_essential(points1, points2, weights=None)[source]#
Find essential matrices.
- Convention:
points1(first image) andpoints2(second image) are normalised camera coordinates \(K^{-1} [u, v, 1]^\top\), not pixels; each real candidate satisfies \(x_2^\top E x_1 = 0\) in them. Two-view geometry maps this onto OpenCV.All ten slots are always returned: each real root gives a candidate of unit Frobenius norm, and each complex root a
NaNslot, so a sample with no real solution returns tenNaNslots.The solve runs in float64 whatever the input dtype, and the degree-ten polynomial’s roots come from LAPACK on the host for every device. MPS has no float64, so MPS inputs are solved on the host and the candidates copied back, which on an Apple M1 was also faster than a float32 solve on the device. A sample whose five design rows are rank deficient, such as one with a repeated correspondence, has no unique solution: ten
NaNslots and a zero gradient.
- Parameters:
points1 (
Tensor) – A set of points in the first image with a tensor shape \((B, N, 2), N>=5\).points2 (
Tensor) – A set of points in the second image with a tensor shape \((B, N, 2), N>=5\).weights (
Optional[Tensor], optional) – Accepted with a shape of \((B, N)\) and ignored for compatibility, including for \(N > 5\). Positive weights leave the null space of an exact five-point sample unchanged; for larger sets they can affect the least-squares fit. Default:None
- Return type:
- Returns:
the computed essential matrices with shape \((B, 10, 3, 3)\). To choose the best one out of 10, try to check the one with the lowest Sampson distance, ignoring the
NaNslots.
- kornia.geometry.epipolar.project_to_essential(E_mat)[source]#
Project a matrix onto the essential-matrix manifold.
An essential matrix must be of the form \(U \text{diag}(s, s, 0) V^T\). Matrices estimated by other means (e.g. a fundamental matrix fitted with the 8-point DLT) generally violate this constraint, which silently breaks tools that rely on it, such as
decompose_essential_matrix()andmotion_from_essential(). The projection averages the two largest singular values and zeroes the smallest one.- Convention:
The result is not normalised to unit Frobenius norm, unlike the candidates of
find_essential().
- kornia.geometry.epipolar.essential_from_fundamental(F_mat, K1, K2)[source]#
Get Essential matrix from Fundamental and Camera matrices.
Uses the method from Hartley/Zisserman 9.6 pag 257 (formula 9.12).
- Convention:
\(E = K_2^\top F K_1\) with
K1the camera of the first image, soEfollows the \(x_2^\top E x_1 = 0\) order offind_essential(); it keeps the scale ofF_mat.
- Parameters:
- Return type:
- Returns:
The essential matrix with shape \((*, 3, 3)\).
- kornia.geometry.epipolar.essential_from_Rt(R1, t1, R2, t2)[source]#
Get the Essential matrix from Camera motion (Rs and ts).
Reference: Hartley/Zisserman 9.6 pag 257 (formula 9.12)
- Convention:
Returns \([t]_\times R\) for the relative motion
(R, t)ofrelative_camera_motion(), so \(x_2^\top E x_1 = 0\) in normalised camera coordinates. It is not normalised: \(\|E\|_F = \sqrt{2} \|t\|\).
- Parameters:
- Return type:
- Returns:
The Essential matrix with the shape \((*, 3, 3)\).
- kornia.geometry.epipolar.decompose_essential_matrix(E_mat)[source]#
Decompose an essential matrix to possible rotations and translation.
This function decomposes the essential matrix E using svd decomposition [96] and give the possible solutions: \(R1, R2, t\).
- Convention:
Returns two rotations and a unit translation; the true pose is one of \((R_1, \pm t)\), \((R_2, \pm t)\). \((R_1, -t)\) and \((R_2, t)\) give \([t]_\times R\) with the sign of
E_mat, \((R_1, t)\) and \((R_2, -t)\) the opposite sign. Which of the four is the true pose is not fixed: it can change whenE_matis negated or rescaled. Select by cheirality withmotion_from_essential_choose_solution(); two-view geometry compares OpenCV’s labels.
- Parameters:
E_mat (
Tensor) – The essential matrix in the form of \((*, 3, 3)\).- Return type:
- Returns:
A tuple containing the first and second possible rotation matrices and the translation vector, with shapes \([(*, 3, 3), (*, 3, 3), (*, 3, 1)]\): the same leading dims as the input.
- kornia.geometry.epipolar.decompose_essential_matrix_no_svd(E_mat)[source]#
Decompose the essential matrix to rotation and translation.
Recovers the rotations and translation from an essential matrix without SVD. Reference: Horn, Berthold KP. Recovering baseline and orientation from essential matrix[J]. J. Opt. Soc. Am, 1990, 110.
- Convention:
Same candidate set as
decompose_essential_matrix(), withtof unit norm.
- Parameters:
E_mat (
Tensor) – The essential matrix in the form of \((*, 3, 3)\).- Return type:
- Returns:
A tuple containing the first and second possible rotation matrices and the translation vector, with shapes \([(B, 3, 3), (B, 3, 3), (B, 3, 1)]\): all leading dims are flattened into one batch dim.
- kornia.geometry.epipolar.motion_from_essential(E_mat)[source]#
Get Motion (R’s and t’s ) from Essential matrix.
Computes and return four possible poses exist for the decomposition of the Essential matrix. The possible solutions are \([R1,t], [R1,-t], [R2,t], [R2,-t]\).
- Convention:
The candidates of
decompose_essential_matrix()are stacked on dim-3in that order; which index is the true pose is not fixed.
- kornia.geometry.epipolar.motion_from_essential_choose_solution(E_mat, K1, K2, x1, x2, mask=None)[source]#
Recover the relative camera rotation and the translation from an estimated essential matrix.
The method checks the corresponding points in two images and also returns the triangulated 3d points. Internally uses
decompose_essential_matrix()andtriangulate_points().- Convention:
K1andK2are applied inside, sox1andx2are pixel coordinates.Returns the candidate with the most points at positive depth in both cameras, with \(\|t\| = 1\), and the points triangulated in the first camera’s frame at that scale.
The fourth output is the number of points at positive depth in both cameras for the returned candidate, as
cv2.recoverPosereturns. A count of0means no point passed, and the returned pose is then candidate 0 ofmotion_from_essential(), not a recovered motion.
- Parameters:
E_mat (
Tensor) – The essential matrix in the form of \((B, 3, 3)\), or \((3, 3)\) with every other input unbatched too.K1 (
Tensor) – The camera matrix from first camera with shape \((B, 3, 3)\).K2 (
Tensor) – The camera matrix from second camera with shape \((B, 3, 3)\).x1 (
Tensor) – The set of points in the first image with shape \((B, N, 2)\).x2 (
Tensor) – The set of points in the second image with shape \((B, N, 2)\).mask (
Optional[Tensor], optional) – A boolean mask which can be used to exclude some points from choosing the best solution. This is useful for using this function with sets of points of different cardinality (for instance after filtering with RANSAC) while keeping batch semantics. Mask is of shape \((B, N)\). Default:None
- Return type:
- Returns:
The rotation, translation, 3d triangulated points, and the number of points with positive depth in both cameras for the selected candidate. The tuple is as following \([(B, 3, 3), (B, 3, 1), (B, N, 3), (B,)]\), without
Bfor unbatched inputs.
- kornia.geometry.epipolar.relative_camera_motion(R1, t1, R2, t2)[source]#
Compute the relative camera motion between two cameras.
Given the motion parameters of two cameras, computes the motion parameters of the second one assuming the first one to be at the origin. If \(T1\) and \(T2\) are the camera motions, the computed relative motion is \(T = T_{2}T^{-1}_{1}\).
- Convention:
Inputs are world-to-camera extrinsics, \(x_{cam} = R X + t\) (see camera and world conventions); the result is \(R = R_2 R_1^\top\) and \(t = t_2 - R_2 R_1^\top t_1\), the motion from camera 1 to camera 2. As 4x4 matrices this is \(E_2 E_1^{-1}\), whereas
relative_transformation()of \(E_1\) and \(E_2\) returns \(E_1^{-1} E_2\).
- Parameters:
- Return type:
- Returns:
A tuple with the relative rotation matrix and translation vector with the shape of \([(*, 3, 3), (*, 3, 1)]\).
Fundamental#
- kornia.geometry.epipolar.find_fundamental(points1, points2, weights=None, method='8POINT')[source]#
Find the fundamental matrix.
- Convention:
points1are in the first image andpoints2in the second; the result satisfies \(x_2^\top F x_1 = 0\), the second image’s point on the left. Two-view geometry maps this onto OpenCV.The result is scaled so that
F[2, 2] = 1bynormalize_transformation(), which leaves it at its unnormalised scale whenF[2, 2]is numerically zero, as for exactly rectified stereo.method="7POINT"returns three candidates in no particular order.weightsweight each correspondence’s equation in the linear system: only their ratios matter, a negative weight counts as zero, andmethod="7POINT"ignores them.When the 7-point cubic has one real root, the two extra
"7POINT"candidates are zero matrices.
- Parameters:
points1 (
Tensor) – A set of points in the first image with a tensor shape \((B, N, 2)\): \(N \ge 8\) for"8POINT", exactly 7 for"7POINT".points2 (
Tensor) – A set of points in the second image with the shape ofpoints1.weights (
Optional[Tensor], optional) – Tensor containing the weights per point correspondence with a shape of \((B, N)\). Default:Nonemethod (
Literal['8POINT','7POINT'], optional) – The method to use for computing the fundamental matrix. Supported methods are “7POINT” and “8POINT”. Default:"8POINT"
- Return type:
- Returns:
the computed fundamental matrix with shape \((B, 3, 3)\) for
"8POINT"and \((B, 3, 3, 3)\) for"7POINT".- Raises:
ValueError – If an invalid method is provided.
- kornia.geometry.epipolar.fundamental_from_essential(E_mat, K1, K2)[source]#
Get the Fundamental matrix from Essential and camera matrices.
Uses the method from Hartley/Zisserman 9.6 pag 257 (formula 9.12).
- Convention:
\(F = K_2^{-\top} E K_1^{-1}\) with
K1the camera of the first image, soFfollows the \(x_2^\top F x_1 = 0\) order offind_fundamental(); it keeps the scale ofE_mat, with noF[2, 2] = 1normalisation.
- Parameters:
- Return type:
- Returns:
The fundamental matrix with shape \((*, 3, 3)\).
- kornia.geometry.epipolar.fundamental_from_projections(P1, P2)[source]#
Get the Fundamental matrix from Projection matrices.
- Convention:
The result satisfies \(x_2^\top F x_1 = 0\) for
(P1, P2), the order offind_fundamental(). It is not normalised, and forP1 = [I | 0],P2 = [R | t]it is the negative ofessential_from_Rt()for the same motion.float16 and bfloat16 inputs are computed in float32. A float16
Fis then divided by its largest absolute entry before the cast back, because pixel-unit projection matrices give entries of order1e10, above float16’s maximum of 65504; an all-zeroF(coincident camera centres) stays zero. bfloat16 has float32’s exponent range and is cast back unnormalised.
- kornia.geometry.epipolar.compute_correspond_epilines(points, F_mat)[source]#
Compute the corresponding epipolar line for a given set of points.
- Convention:
For first-image points and
Ffromfind_fundamental()the lines lie in the second image; for second-image points passF.transpose(-2, -1). Lines are scaled to \(a^2 + b^2 = 1\).
- Parameters:
- Return type:
- Returns:
a tensor with shape \((*, N, 3)\) containing the epipolar lines \(F x\) of the points. Each line is described as \(ax + by + c = 0\) and encoding the vectors as \((a, b, c)\).
- kornia.geometry.epipolar.normalize_points(points, eps=1e-8, weights=None)[source]#
Normalize points (isotropic).
Computes the Hartley normalisation: the points are translated to zero mean and scaled isotropically so that their mean distance to the origin is \(\sqrt{2}\). Reference: Hartley/Zisserman 4.4.4 pag.107
This operation is an essential step before applying the DLT algorithm in order to consider the result as optimal.
- Parameters:
points (
Tensor) – Tensor containing the points to be normalized with shape \((B, N, 2)\).eps (
float, optional) – epsilon value to avoid numerical instabilities. Default:1e-8weights (
Optional[Tensor], optional) – Optional nonnegative weights with shape \((B, N)\) for the centroid and mean radius. Zero-weight points do not influence the transform. An all-zero batch element uses unweighted statistics. Default:None
- Return type:
- Returns:
tuple containing the normalized points in the shape \((B, N, 2)\) and the transformation matrix in the shape \((B, 3, 3)\) that maps the input points to them.
- kornia.geometry.epipolar.normalize_transformation(M, eps=1e-8)[source]#
Normalize a given transformation matrix.
- Convention:
Divides
Mby its last entryM[..., -1, -1], which givesfind_fundamental()itsF[2, 2] = 1scaling. A matrix whose last entry is withinepsof zero is returned unchanged.
- Parameters:
- Return type:
- Returns:
the normalized transformation matrix with same shape as the input.
- kornia.geometry.epipolar.get_perpendicular(lines, points)[source]#
Compute the perpendicular to a line, through the point.
- Parameters:
- Return type:
- Returns:
a tensor with shape \((B, N, 3)\) containing a vector of the epipolar perpendicular lines. Each line is described as \(ax + by + c = 0\) and encoding the vectors as \((a, b, c)\); the normal \((a, b)\) has the norm of the input line’s and is not rescaled.
- kornia.geometry.epipolar.get_closest_point_on_epipolar_line(pts1, pts2, Fm)[source]#
Return closest point on the epipolar line to the correspondence, given the fundamental matrix.
- Convention:
Returns, in the second image, the point of the epipolar line of
pts1closest topts2, forFmin the \(x_2^\top F x_1 = 0\) order offind_fundamental().
- Parameters:
pts1 (
Tensor) – points in the first image with shape \((B, N, 2)\) or \((B, N, 3)\). If they are not homogeneous, converted automatically.pts2 (
Tensor) – points in the second image with shape \((B, N, 2)\) or \((B, N, 3)\). If they are not homogeneous, converted automatically.Fm (
Tensor) – Fundamental matrices with shape \((B, 3, 3)\). Called Fm to avoid ambiguity with torch.nn.functional.
- Return type:
- Returns:
point on epipolar line \((B, N, 2)\).
Metrics#
- kornia.geometry.epipolar.sampson_epipolar_distance(pts1, pts2, Fm, squared=True, eps=1e-8, use_matmul_at_less_than_points=10000)[source]#
Return Sampson distance for correspondences given the fundamental matrix.
- Convention:
pts1are first-image points,pts2second-image points, andFmfollows \(x_2^\top F x_1 = 0\), as returned byfind_fundamental()(see two-view geometry).Returns squared pixel distances by default; a 3-vector point is used as given, so it must have \(w = 1\).
One set of correspondences scored against several matrices (points with leading dimensions of size 1) is computed from two matrix products for all of them, in at least float32; the result matches the per-matrix computation to roundoff.
The value does not depend on the scale of
Fm, andsquared=Falsereturns exactly 0, with a zero gradient, for an exact match. A correspondence whose two epilines both have \(a = b = 0\), as under a degenerateFm, is at distanceinf.
- Parameters:
pts1 (
Tensor) – points in the first image with shape \((*, N, 2)\) or \((*, N, 3)\).pts2 (
Tensor) – points in the second image with shape \((*, N, 2)\) or \((*, N, 3)\).Fm (
Tensor) – Fundamental matrices with shape \((*, 3, 3)\). Called Fm to avoid ambiguity with torch.nn.functional.squared (
bool, optional) – if True (default), the squared distance is returned, else its square root. Default:Trueeps (
float, optional) – unused; it was added to the denominator and inside the square root, which made the value depend on the scale ofFmand an exact match score \(\sqrt{\epsilon}\) (#4881). The singular case is guarded exactly instead. Accepted so that existing calls keep working. Default:1e-8use_matmul_at_less_than_points (
int, optional) – IfFmis on CUDA and the number of points is less than this value, use the matmul implementation. Default:10000
- Return type:
- Returns:
the computed Sampson distance with shape \((*, N)\).
- kornia.geometry.epipolar.symmetrical_epipolar_distance(pts1, pts2, Fm, squared=True, eps=1e-8)[source]#
Return symmetrical epipolar distance for correspondences given the fundamental matrix.
- Convention:
Argument order and units as
sampson_epipolar_distance(); the value is the sum of the two squared point-to-epiline distances.The value does not depend on the scale of
Fm, andsquared=Falsereturns exactly 0 for an exact match, as insampson_epipolar_distance(). A correspondence with an epiline of \(a = b = 0\) in either image is at distanceinf.
- Parameters:
pts1 (
Tensor) – points in the first image with shape \((*, N, 2)\) or \((*, N, 3)\).pts2 (
Tensor) – points in the second image with shape \((*, N, 2)\) or \((*, N, 3)\).Fm (
Tensor) – Fundamental matrices with shape \((*, 3, 3)\). Called Fm to avoid ambiguity with torch.nn.functional.squared (
bool, optional) – if True (default), the squared distance is returned, else its square root. Default:Trueeps (
float, optional) – unused, as insampson_epipolar_distance()(#4881). Default:1e-8
- Return type:
- Returns:
the computed Symmetrical distance with shape \((*, N)\).
- kornia.geometry.epipolar.left_to_right_epipolar_distance(pts1, pts2, Fm)[source]#
Return one-sided epipolar distance for correspondences given the fundamental matrix.
- Convention:
Argument order as
sampson_epipolar_distance(); returns the unsquared pixel distance of eachpts2to the epipolar line of itspts1in the second image.The value does not depend on the scale of
Fm; a point whose epiline has \(a = b = 0\) is at distanceinf, as inpoint_line_distance().
- Parameters:
- Return type:
- Returns:
the one-sided distance with shape \((*, N)\).
- kornia.geometry.epipolar.right_to_left_epipolar_distance(pts1, pts2, Fm)[source]#
Return one-sided epipolar distance for correspondences given the fundamental matrix.
- Convention:
Argument order as
sampson_epipolar_distance(); returns the unsquared pixel distance of eachpts1to the epipolar line of itspts2in the first image.The value does not depend on the scale of
Fm; a point whose epiline has \(a = b = 0\) is at distanceinf, as inpoint_line_distance().
- Parameters:
- Return type:
- Returns:
the one-sided distance with shape \((*, N)\).
Projection#
- kornia.geometry.epipolar.projection_from_KRt(K, R, t)[source]#
Get the projection matrix P from K, R and t.
This function computes the product \(P = K [R|t]\).
- Convention:
Randttake world points into the camera frame,X_cam = R @ X + t, andKtakes the camera frame to pixels.tis the extrinsic translation; the camera centre is-R.T @ t.K,Randtmust have the same number of dimensions, andRandtthe same batch shape;Kbroadcasts against them. The inverse isKRt_from_projection(), anddepth_from_point()gives the depth of a point in this camera.
- kornia.geometry.epipolar.KRt_from_projection(P, eps=1e-6)[source]#
Decompose the Projection matrix into
K,Randtwith \(K [R|t] = \pm P\).- Convention:
Inverse of
projection_from_KRt(): returnsK(upper triangular, positive diagonal), a rotationR(det R = 1) and the translationt, not the camera centre; Two-view geometry maps this onto OpenCV.Pis defined up to a nonzero scale, sign included:s * Pgives the sameRandtfor every nonzerosand|s| * K. So \(K [R|t]\) isPwhenP[:, :3, :3]has positive determinant and-Pwhen it has negative determinant (-Pgives the factors ofP).Kis not normalised toK[2, 2] = 1; divide byK[..., 2:, 2:]to normalise.Pmust have exactly one batch dimension. float16 and bfloat16 raise.
- Parameters:
- Return type:
- Returns:
The Camera matrix with shape \((B, 3, 3)\).
The Rotation matrix with shape \((B, 3, 3)\).
The Translation vector with shape \((B, 3, 1)\).
- kornia.geometry.epipolar.depth_from_point(R, t, X)[source]#
Return the depth of a point transformed by a rigid transform.
- Convention:
Returns the
zcoordinate ofR @ X + t, the depth in the camera ofprojection_from_KRt()with the sameRandt. The sign is not checked. AnXof shape(B, 3)with a batchedRis read asBpoints seen by every camera and gives(B, B), not one point per camera.
- kornia.geometry.epipolar.projections_from_fundamental(F_mat)[source]#
Get the projection matrices from the Fundamental Matrix.
- Convention:
Returns the canonical pair for
Fin thex2^T F x1 = 0convention offind_fundamental(), stacked on the last dimension:[..., 0] = [I | 0]for the first image and[..., 1] = [[e2]_x F | e2], withe2the left null vector ofF, the epipole in the second image (e2^T F = 0).F_matmust have exactly one batch dimension.
- kornia.geometry.epipolar.intrinsics_like(focal, input)[source]#
Return a 3x3 intrinsics matrix per batch element of the input.
- Convention:
fx = fy = focaland the principal point is(W / 2, H / 2)of the \((B, C, H, W)\) input; dtype and device follow the input.focalmust be positive and the input 4-D.The input must be floating point, like kornia’s images: an integer input raises by design rather than returning an integer
K.Known defects:
(W / 2, H / 2)is the half-pixel centre, not the integer-pixel centre((W - 1) / 2, (H - 1) / 2)of kornia’s grids (#4263).
- Parameters:
- Return type:
- Returns:
The camera matrix with the shape of \((B, 3, 3)\).
- kornia.geometry.epipolar.scale_intrinsics(camera_matrix, scale_factor)[source]#
Scale a camera matrix containing the intrinsics.
Applies the scaling factor to the focal length and center of projection.
- Convention:
- Parameters:
camera_matrix (
Tensor) – the camera calibration matrix containing the intrinsic parameters. The expected shape for the tensor is \((B, 3, 3)\).scale_factor (
Union[float,Tensor]) – the scaling factor to be applied: a float, or a tensor of shape \((B,)\) that scales each batch element by its own factor.
- Return type:
- Returns:
The scaled camera matrix with the same shape as the input \((B, 3, 3)\).
- kornia.geometry.epipolar.random_intrinsics(low, high)[source]#
Generate a random camera matrix based on a given uniform distribution.
- Convention:
fx,fy,cxandcyare four draws from \(U(low, high)\) on torch’s global generator. The bounds are scalars; dtype and device follow tensor bounds, and Python floats give the default dtype and device.
Numeric#
- kornia.geometry.epipolar.cross_product_matrix(x)[source]#
Return the skew-symmetric cross-product matrix of a vector.
- Convention:
Same matrix as
vector_to_skew_symmetric_matrix(), \([x]_\times w = x \times w\), for any number of leading dims.
Triangulation#
- kornia.geometry.epipolar.triangulate_points(P1, P2, points1, points2, solver='eigh')[source]#
Reconstructs a bunch of points by triangulation.
Triangulates the 3d position of 2d correspondences between two images. Reference: the
"svd"and"eigh"solvers use the DLT formulation from Hartley/Zisserman 12.2 pag.312.The input points are assumed to be inlier correspondences. The method does not perform any robust estimation.
- Convention:
P1pairs withpoints1andP2withpoints2. Input and output points are Euclidean; Two-view geometry maps this onto OpenCV. The leading dimensions ofP1andP2broadcast against those of the points.Cheirality and baseline are not checked: a point behind a camera is returned with negative depth, and with zero baseline the depth is undefined:
"svd"and"eigh"return an arbitrary point on the line of sight, possibly behind the camera or at infinity (NaN), and"cofactor"returns NaN.A correspondence at infinity, whose homogeneous
wis at the roundoff of the input and compute dtypes, returns NaN. In float16 and bfloat16 that roundoff also covers a point a few tens of units away in the scale oft. Mask those rows before a loss (out[~out.isnan().any(-1)]); the gradients with respect to the cameras and the other points stay finite."svd"and"eigh"solve in float64, or in float32 for float16 and bfloat16 input and on MPS;"cofactor"solves in float32, or in float64 for float64 input. All return the input dtype;solverbelow compares their accuracy.
- Parameters:
P1 (
Tensor) – The projection matrix for the first camera with shape \((*, 3, 4)\).P2 (
Tensor) – The projection matrix for the second camera with shape \((*, 3, 4)\).points1 (
Tensor) – The set of points seen from the first camera, in the image coordinates ofP1(pixels forP1 = K [R | t]), with shape \((*, N, 2)\).points2 (
Tensor) – The set of points seen from the second camera, in the image coordinates ofP2(pixels forP2 = K [R | t]), with shape \((*, N, 2)\).solver (
str, optional) –Back-end used to find the null vector of the \(4 \times 4\) DLT constraint matrix. One of: Default:
"eigh""svd"— most numerically stable. Uses a full SVD. Suitable when maximum accuracy is required regardless of speed."eigh"(default) — forms \(X^\top X\) and finds the eigenvector for its smallest eigenvalue viatorch.linalg.eigh(). Algebraically equivalent to the SVD solution, and equal to it to roundoff on well-conditioned input; forming \(X^\top X\) squares the singular values, so on ill-conditioned rows, such as a baseline much shorter than the depth, it loses accuracy that"svd"keeps. Typically 10-26x faster than"svd"on GPU for large batches."cofactor"— closed form, no LAPACK call. The null vectors of the four \(3 \times 4\) sub-systems (the cofactors, as innull_vector_3x4()) form the adjugate of the DLT matrix; the longest one, refined by one step of inverse iteration through the adjugate, gives the"svd"point to roundoff without noise and nearly the same point with noise, also for rectified and vertical stereo pairs, where a sub-system is nearly rank-deficient. When the noise is comparable to the parallax, so that the DLT point itself is far off, one step does not converge and the two can differ. The point is NaN when every sub-system is rank-deficient (zero baseline). Fastest option for large batches.
- Return type:
- Returns:
The reconstructed 3d points in the world frame with shape \((*, N, 3)\).
Example
>>> P1 = torch.eye(3, 4)[None]   # 1x3x4
>>> P2 = torch.eye(3, 4)[None]
>>> P2[..., 0, 3] = -1.0  # second camera shifted along x
>>> pts1 = torch.rand(1, 5, 2)
>>> pts2 = torch.rand(1, 5, 2)
>>> pts3d = triangulate_points(P1, P2, pts1, pts2)
>>> pts3d.shape
torch.Size([1, 5, 3])
- kornia.geometry.epipolar.generate_scene(num_views, num_points)[source]#
Generate a random 3d scene seen by
num_viewscameras that share one camera matrix.- Convention:
Every point has positive depth in every view; depth and focal length are not bounded away from zero.
Draws from torch’s global generator.
- Parameters:
- Returns:
"K": the camera matrix shared by all views, with shape \((1, 3, 3)\)."R": the rotation of each view, with shape \((V, 3, 3)\)."t": the translation of each view, with shape \((V, 3, 1)\)."P": the projection matrix \(K [R|t]\) of each view, with shape \((V, 3, 4)\)."points3d": the 3d points, in \([0, 1)\) per coordinate, with shape \((1, N, 3)\)."points2d": the projection ofpoints3dby eachP, with shape \((V, N, 2)\).
- Return type:
A dictionary of tensors on torch’s default device and in the default dtype