

Augmentation Containers#
The classes in this section are containers for augmenting different data formats (e.g. images, videos).
Augmentation Sequential#
Kornia augmentations provide a simple on-device augmentation framework with a number of conveniences (e.g. returning the transformation matrix, or inverting a geometric transform). On top of that, we provide an advanced augmentation container to ease the pain of building augmentation pipelines. This API also provides predefined routines that automate the processing of masks, bounding boxes, and keypoints.
- class kornia.augmentation.container.AugmentationSequential(*args, data_keys=(DataKey.INPUT,), same_on_batch=None, keepdim=None, random_apply=False, random_apply_weights=None, transformation_matrix_mode='silent', extra_args=None)[source]#
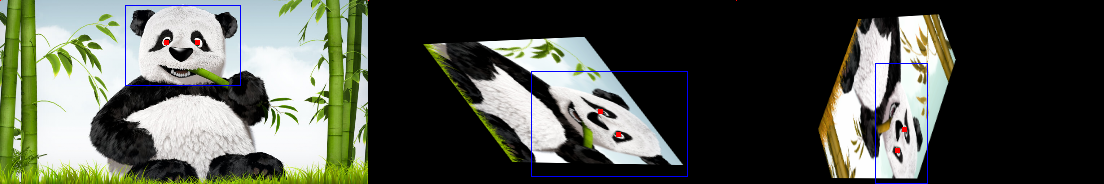
AugmentationSequential for handling multiple input types like inputs, masks, keypoints at once.
- Parameters:
*args (
Union[_AugmentationBase,ImageSequential]) – a list of kornia augmentation modules.data_keys (
Union[Sequence[str],Sequence[int],Sequence[DataKey],None], optional) – the input type sequential for applying augmentations. Accepts “input”, “image”, “mask”, “bbox”, “bbox_xyxy”, “bbox_xywh”, “keypoints”, “class”, “label”. Default:(DataKey.INPUT,)same_on_batch (
Optional[bool], optional) – apply the same transformation across the batch. If None, it will not overwrite the function-wise settings. Default:Nonekeepdim (
Optional[bool], optional) – whether to keep the output shape the same as input (True) or broadcast it to the batch form (False). If None, it will not overwrite the function-wise settings. Default:Nonerandom_apply (
Union[int,bool,Tuple[int,int]], optional) – randomly select children to apply. The selected children run in random order and may repeat when the requested count exceeds the sum of the selection weights. If int, a fixed number of transformations will be selected. If (a,), x number of transformations (a <= x <= len(args)) will be selected. If (a, b), x number of transformations (a <= x <= b) will be selected. If True, the whole list of args will be processed as a sequence in a random order. If False, the whole list of args will be processed as a sequence in original order. Default:Falsetransformation_matrix_mode (
str, optional) – computation mode for the chained transformation matrix, via .transform_matrix attribute. If silent, the default, the transformation matrix is computed silently and a direct non-rigid module is skipped rather than treated as an identity. Nested containers are not handled consistently; see the Convention note below. If rigid, transformation matrix will be computed silently and the non-rigid modules will trigger errors. If skip, transformation matrix will be totally ignored. The validator also accepts silence, an alias that behaves like silent; any other value raisesValueError. Default:"silent"extra_args (
Optional[Dict[DataKey,Dict[str,Any]]], optional) – a dict keyed bykornia.constants.DataKeythat replaces the default{DataKey.MASK: {'resample': Resample.NEAREST, 'align_corners': None}}rather than merging into it, so an override that omits a key drops that key’s default. An empty dict is falsy and restores the default.DataKey.IMAGEhonours both entries andDataKey.KEYPOINTShonours neither. ForDataKey.MASKon a 2D geometric augmentation that uses the base mask path theresampleentry is honoured in both directions, and a dict without one resamples masks with nearest neighbour.align_cornersis handler-dependent: some warps honor it, but resize mask paths replace it.RandomResizedCropin the defaultcropping_mode='slice'ignores it for nearest resampling.RandomElasticTransformhas its own mask path and honours both entries. As in the constructors,resamplemay be a string, an int or akornia.constants.Resamplemember. Default:None
- Convention:
each child keeps the contract of its own base and class; mix and 3D children do not inherit every
AugmentationBase2Dconvention.data_keysnames one entry per positional argument, case-insensitively:input(aliasimage),mask,bbox,bbox_xyxy,bbox_xywh,keypointsandlabel(aliasclass); any other name raises aValueErrorthat is also aKeyError. Withdata_keys=Nonethe call takes a dict whose keys are these names, optionally followed by a_or-suffix (mask_2,class_id). The longest matching name wins and a suffix needs its separator:bbox_xyxy2is abboxkey and must hold vertices. Unrecognized keys (images,masks,labels) are returned unchanged, without a warning. The input dict is not modified.the layouts are
(B, C, H, W)for images and masks,(B, N, 4, 2)vertices forbbox,(B, N, 4)forbbox_xyxyandbbox_xywh, and(B, N, 2)in(x, y)forkeypoints;N = 0is accepted. 3D inputs are(D, H, W)or(B, C, D, H, W); rank 4 is rejected as ambiguous. A(B, H, W)mask is returned as(B, 1, H, W), or as(B, H, W)underkeepdim=True. A single tensor mask,(H, W),(1, H, W),(1, C, H, W)or one(C, H, W), next to a(B, C, H, W)image is repeated to batchBbefore the first child, so each sample’s own parameters apply to its copy; a 3D mask whose leading size isBis read as(B, H, W). A list of masks is not repeated. A single(1, T, C, H, W)mask is repeated the same way next to a(B, T, C, H, W)video. Next to a BTCHW video a(B, T, H, W)mask is read with one channel and returned as(B, T, 1, H, W), and a single(1, T, H, W)mask is repeated too. Any other mask rank next to a video, or a 5D mask next to a non-video image, raisesValueErrorinstead of guessing. A replay with no image (params=given, noINPUTkey) reads the batch to repeat to from the recorded params instead. A wrong input rank raisesRuntimeErrorhere rather than theValueErrorof a bare augmentation (#4424).boxes use the inclusive
xyxy_plusconvention ofBoxes. Flips mapx' = W - 1 - xandy' = H - 1 - yfor every key, ashflip()does. Labels pass through geometric steps untouched.masks are resampled with nearest interpolation by default (see
extra_args; padding can still add the fill value) and come back in their own dtype. Floating masks use the image’s working dtype; integer masks use at least float32 (float64 with a float64 image). Integer labels not exactly representable in that working dtype raiseRuntimeErrorinstead of being rounded. On accelerators an asynchronous assertion may report at the next synchronization; MPS before torch 2.13 checks on the host.a
masklist contains one tensor per image sample, in sample order. Each entry is(H, W),(C, H, W)or(1, C, H, W), with matching spatial dimensions; channel counts may differ. Each entry uses its sample’s gate, transform parameters and matrix, including in nested sequences, auto-augment policies, replay and inverse. Full-batch mask tensors must use separatemaskdata keys; a list with incompatible length or entry shape raisesValueError, also in an inverse without an image. Video, mix and 3D children, and a geometricPatchSequential, do not support mask lists and raiseNotImplementedError. Inverse warps can only approximately restore resampled pixels and cannot recover pixels moved out of the frame.the
mask, box andkeypointshandlers of a geometric child, or of a customRigidAffineAugmentationBase2Dsubclass, receive the transform of the call’sparams: the one the child recorded when it last transformed an image with those params, while no value in them has been replaced or edited in place, or else one recomputed from them, so a replay without the image, after a newer draw or after an edit followsparams. Inference tensors have no version counter, so an in-place edit made insidetorch.inference_modeis not seen; replace the value instead. The mask limitations above apply; a handler the subclass does not implement raisesNotImplementedError. A non-rigid warp child has no matrix, so the coordinate keys are left unchanged; see the warning below..inverse()undoes the 2D geometric steps and leaves intensity, custom rigid and non-rigid steps applied. Slice-mode crops and 3D geometric children raiseNotImplementedError, mix childrenRuntimeError. Tensor boxes come back as axis-aligned enclosures; passBoxesto keep rotated corners. Content lost to cropping, padding or interpolation is not recovered.same_on_batchandkeepdimdefault toNone, which keeps each child’s own setting;TrueorFalseoverrides it.Nested
AugmentationSequentialchildren contribute the matrix they record for the current call under their owntransformation_matrix_mode; one whose children are all non-rigid records none and is skipped. A plainImageSequentialchild is still omitted from the outer matrix (#4476).
Warning
A non-rigid child silently desynchronizes the coordinate data keys:
RandomElasticTransformwarps the image and amaskkey with it, but returns keypoints and boxes unchanged, andRandomThinPlateSplineandRandomFisheyereturn keypoints and boxes unchanged and raise a bareNotImplementedErroron amaskkey. Tracked in #4420.Note
A mix child (e.g. RandomMixUpV2, RandomCutMixV2, RandomMosaic) receives
mask, box andkeypointskeys with the image’s parameters; keys it does not implement raiseNotImplementedError, as in a direct call. Aclass/labelkey raisesNotImplementedErrorfrom the container.Note
See a working example here.
Examples
>>> import kornia
>>> input = torch.randn(2, 3, 5, 6)
>>> mask = torch.ones(2, 3, 5, 6)
>>> bbox = torch.tensor([[
...     [1., 1.],
...     [2., 1.],
...     [2., 2.],
...     [1., 2.],
... ]]).expand(2, 1, -1, -1)
>>> points = torch.tensor([[[1., 1.]]]).expand(2, -1, -1)
>>> aug_list = AugmentationSequential(
...     kornia.augmentation.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=1.0),
...     kornia.augmentation.RandomAffine(360, p=1.0),
...     data_keys=["input", "mask", "bbox", "keypoints"],
...     same_on_batch=False,
...     random_apply=10,
... )
>>> out = aug_list(input, mask, bbox, points)
>>> [o.shape for o in out]
[torch.Size([2, 3, 5, 6]), torch.Size([2, 3, 5, 6]), torch.Size([2, 1, 4, 2]), torch.Size([2, 1, 2])]
>>> # apply the exact augmentation again.
>>> out_rep = aug_list(input, mask, bbox, points, params=aug_list._params)
>>> [(o == o_rep).all() for o, o_rep in zip(out, out_rep)]
[tensor(True), tensor(True), tensor(True), tensor(True)]
>>> # inverse the augmentations
>>> out_inv = aug_list.inverse(*out)
>>> [o.shape for o in out_inv]
[torch.Size([2, 3, 5, 6]), torch.Size([2, 3, 5, 6]), torch.Size([2, 1, 4, 2]), torch.Size([2, 1, 2])]
This example demonstrates the integration of VideoSequential and AugmentationSequential.
>>> import kornia
>>> input = torch.randn(2, 3, 5, 6)[None]
>>> mask = torch.ones(2, 3, 5, 6)[None]
>>> bbox = torch.tensor([[
...     [1., 1.],
...     [2., 1.],
...     [2., 2.],
...     [1., 2.],
... ]]).expand(2, 1, -1, -1)[None]
>>> points = torch.tensor([[[1., 1.]]]).expand(2, -1, -1)[None]
>>> aug_list = AugmentationSequential(
...     VideoSequential(
...         kornia.augmentation.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=1.0),
...         kornia.augmentation.RandomAffine(360, p=1.0),
...     ),
...     data_keys=["input", "mask", "bbox", "keypoints"]
... )
>>> out = aug_list(input, mask, bbox, points)
>>> [o.shape for o in out]
[torch.Size([1, 2, 3, 5, 6]), torch.Size([1, 2, 3, 5, 6]), ...([1, 2, 1, 4, 2]), torch.Size([1, 2, 1, 2])]
Perform
OneOftransformation withrandom_apply=1andrandom_apply_weightsinAugmentationSequential.>>> import kornia >>> input = torch.randn(2, 3, 5, 6)[None] >>> mask = torch.ones(2, 3, 5, 6)[None] >>> bbox = torch.tensor([[ ... [1., 1.], ... [2., 1.], ... [2., 2.], ... [1., 2.], ... ]]).expand(2, 1, -1, -1)[None] >>> points = torch.tensor([[[1., 1.]]]).expand(2, -1, -1)[None] >>> aug_list = AugmentationSequential( ... VideoSequential( ... kornia.augmentation.RandomAffine(360, p=1.0), ... ), ... VideoSequential( ... kornia.augmentation.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=1.0), ... ), ... data_keys=["input", "mask", "bbox", "keypoints"], ... random_apply=1, ... random_apply_weights=[0.5, 0.3] ... ) >>> out = aug_list(input, mask, bbox, points) >>> [o.shape for o in out] [torch.Size([1, 2, 3, 5, 6]), torch.Size([1, 2, 3, 5, 6]), ...([1, 2, 1, 4, 2]), torch.Size([1, 2, 1, 2])]
Use separate full-batch mask arguments when their channel counts differ:
>>> import kornia.augmentation as K
>>> input = torch.randn(2, 3, 32, 32)
>>> mask_a = torch.ones(2, 3, 32, 32)
>>> mask_b = torch.ones(2, 2, 32, 32)
>>> aug_list = K.AugmentationSequential(
...     K.RandomHorizontalFlip(p=1.0),
...     data_keys=["input", "mask", "mask"],
... )
>>> out = aug_list(input, mask_a, mask_b)
>>> [value.shape for value in out]
[torch.Size([2, 3, 32, 32]), torch.Size([2, 3, 32, 32]), torch.Size([2, 2, 32, 32])]
With
data_keys=None, dictionary keys match data-key names case-insensitively, optionally followed by an underscore or hyphen suffix (for example,image_2orbbox_xyxy-left). The longest matching name wins, so coordinate boxes with an underscore/hyphen suffix retain their coordinate format. Without that separator,bbox_xyxy2matchesbboxand requires vertex boxes.inputandclassare aliases ofimageandlabel. Unrecognized items are returned without augmentation, and the caller’s dictionary is left intact.>>> import kornia.augmentation as K >>> img = torch.randn(1, 3, 256, 256) >>> mask = [torch.ones(1, 3, 256, 256), torch.ones(1, 2, 256, 256)] >>> bbox = [ ... torch.tensor([[28.0, 53.0, 143.0, 164.0], [254.0, 158.0, 364.0, 290.0], [307.0, 204.0, 413.0, 350.0]]), ... torch.tensor([[254.0, 158.0, 364.0, 290.0], [307.0, 204.0, 413.0, 350.0]]) ... ] >>> bbox = [Boxes.from_tensor(i).data for i in bbox] >>> aug_dict = K.AugmentationSequential( ... K.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=1.0), ... K.RandomHorizontalFlip(p=1.0), ... K.ImageSequential(K.RandomHorizontalFlip(p=1.0)), ... K.ImageSequential(K.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=1.0)), ... data_keys=None, ... same_on_batch=False, ... random_apply=10, ... ) >>> data = {'image': img, 'mask': mask[0], 'mask-b': mask[1], 'bbox': bbox[0], 'bbox-other':bbox[1]} >>> out = aug_dict(data) >>> out.keys() dict_keys(['image', 'mask', 'mask-b', 'bbox', 'bbox-other'])
- forward(*args, params=None, data_keys=None)[source]#
Compute multiple tensors simultaneously according to
self.data_keys.See the Convention block on
AugmentationSequential.
- inverse(*args, params=None, data_keys=None)[source]#
Reverse the transformation applied.
See the Convention block on
AugmentationSequential.Number of input tensors must align with the number of``data_keys``. If
data_keysis not set, useself.data_keysby default.
Augmentation Dispatchers#
Kornia supports two types of augmentation dispatching, namely many-to-many and many-to-one. The former wraps
different augmentations into one group and lets the user pass as many inputs as there are augmentations, applying
each augmentation to the corresponding input; a call with a different number of input bundles than
augmentations raises ValueError before any augmentation runs. The latter applies different augmentations to a
single input in order to obtain a list of differently transformed outputs. Its members must be
AugmentationSequential instances. With the default strict=True, their data_keys must match;
strict=False disables that construction check.
Note
The class names below keep their historical spelling (Dispather) for backward compatibility.
- class kornia.augmentation.container.ManyToManyAugmentationDispather(*augmentations)[source]#
Dispatches different augmentations to different inputs element-wisely.
See the Convention block on
AugmentationSequential.- Parameters:
augmentations (
AugmentationSequential) – a list or a sequence of kornia AugmentationSequential modules.
- Convention:
every member has to be an
AugmentationSequential; anything else is rejected at construction withValueError.the call takes one input bundle per augmentation and returns a list in that order; a different number of bundles raises
ValueErrorbefore any augmentation runs. Each augmentation draws its own parameters, so the members are independent of one another.
Examples
>>> import torch
>>> input_1, input_2 = torch.randn(2, 3, 5, 6), torch.randn(2, 3, 5, 6)
>>> mask_1, mask_2 = torch.ones(2, 3, 5, 6), torch.ones(2, 3, 5, 6)
>>> aug_list = ManyToManyAugmentationDispather(
...     AugmentationSequential(
...         kornia.augmentation.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=1.0),
...         kornia.augmentation.RandomAffine(360, p=1.0),
...         data_keys=["input", "mask",],
...     ),
...     AugmentationSequential(
...         kornia.augmentation.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=1.0),
...         kornia.augmentation.RandomAffine(360, p=1.0),
...         data_keys=["input", "mask",],
...     )
... )
>>> output = aug_list((input_1, mask_1), (input_2, mask_2))
- forward(*input)[source]#
Apply each augmentation to the matching input tuple.
- class kornia.augmentation.container.ManyToOneAugmentationDispather(*augmentations, strict=True)[source]#
Dispatches different augmentations to a single input and returns a list.
See the Convention block on
AugmentationSequential.Same datakeys must be applied across different augmentations. By default, with input (image, mask), the augmentations must not mess it as (mask, image) to avoid unexpected errors. This check can be cancelled with strict=False if needed.
- Parameters:
augmentations (
AugmentationSequential) – a list or a sequence of kornia AugmentationSequential modules.
- Convention:
the same input payload is broadcast to every augmentation, so the returned list is always as long as the list of augmentations and no input can be dropped.
with
strict=True, the default, the members must all declare the samedata_keys; a mismatch raisesRuntimeErrorat construction.
Examples
>>> import torch
>>> input = torch.randn(2, 3, 5, 6)
>>> mask = torch.ones(2, 3, 5, 6)
>>> aug_list = ManyToOneAugmentationDispather(
...     AugmentationSequential(
...         kornia.augmentation.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=1.0),
...         kornia.augmentation.RandomAffine(360, p=1.0),
...         data_keys=["input", "mask",],
...     ),
...     AugmentationSequential(
...         kornia.augmentation.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=1.0),
...         kornia.augmentation.RandomAffine(360, p=1.0),
...         data_keys=["input", "mask",],
...     )
... )
>>> output = aug_list(input, mask)
ImageSequential#
ImageSequential is a lightweight container that, in addition to augmentation modules, accepts arbitrary
image processing nn.Module instances (e.g. the modules in kornia.filters, kornia.color or
kornia.enhance), so both kinds of operations can be mixed in a single pipeline.
- class kornia.augmentation.container.ImageSequential(*args, same_on_batch=None, keepdim=None, random_apply=False, random_apply_weights=None, if_unsupported_ops='raise', disable_item_features=True, disable_sequential_features=False)[source]#
nn.Sequential for creating kornia image processing pipeline.
See the Convention block on
AugmentationBase2D.- Parameters:
*args (
Module) – a list of kornia augmentation and image operation modules.same_on_batch (
Optional[bool], optional) – apply the same transformation across the batch. If None, it will not overwrite the function-wise settings. Default:Nonekeepdim (
Optional[bool], optional) – whether to keep the output shape the same as input (True) or broadcast it to the batch form (False). If None, it will not overwrite the function-wise settings. Default:Nonerandom_apply (
Union[int,bool,Tuple[int,int]], optional) – randomly select children to apply in random order. The selection probability aligns to therandom_apply_weightsand selections may repeat when the requested count is larger than their sum. If int, a fixed number of transformations will be selected. If (a,), x number of transformations (a <= x <= len(args)) will be selected. If (a, b), x number of transformations (a <= x <= b) will be selected. If True, the whole list of args will be processed as a sequence in a random order. If False, the whole list of args will be processed as a sequence in original order. Default:Falserandom_apply_weights (
Optional[List[float]], optional) – a list of selection weights for each operation. The length shall be as same as the number of operations. By default, operations are sampled uniformly. Default:Noneif_unsupported_ops (
str, optional) – whatinversedoes on reaching a plainnn.Module, which has no inverse:'raise'raisesNotImplementedErrornaming it, before anything is inverted, and'skip'leaves it applied and inverts the other members. Any other value raisesValueError. Default:"raise"
- Convention:
this container takes image tensors only. It has no
data_keys, so masks, boxes and keypoints go throughAugmentationSequentialinstead. It also carries no.transform_matrixattribute: the chained matrix is reachable throughget_transformation_matrix, which needs the recordedparams=handed back to it. To use params from an older call, passrecompute=True.any
nn.Modulemay sit in the chain next to the augmentations – the modules ofkornia.filters,kornia.colorandkornia.enhanceamong them.random_applysamples ordinary members and mix augmentations through separate paths; a mix member’s insertion does not honor its ordinary selection weight. Each selected member is recorded in_params, but a plain module records aNonepayload: only augmentation members carry a parameter draw to replay.inversetreats a plainnn.Modulemember according toif_unsupported_ops, and a nested container according to its own setting. Augmentation children can still raise, for example a slice-mode crop or a 3D geometric augmentation, while intensity and non-rigid augmentation children are left applied; the round trip is not in general the input.
Note
Transformation matrix returned only considers the transformation applied in
kornia.augmentationmodule. Those transformations inkornia.geometrywill not be taken into account.Note
The output cache retains a detached reference to the last tensor output and is omitted when pickled. Setting
disable_features = Trueclears it.Examples
>>> _ = torch.manual_seed(77)
>>> import kornia
>>> input = torch.randn(2, 3, 5, 6)
>>> aug_list = ImageSequential(
...     kornia.color.BgrToRgb(),
...     kornia.augmentation.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=1.0),
...     kornia.filters.MedianBlur((3, 3)),
...     kornia.augmentation.RandomAffine(360, p=1.0),
...     kornia.enhance.Invert(),
...     kornia.augmentation.RandomMixUpV2(p=1.0),
...     same_on_batch=True,
...     random_apply=10,
... )
>>> out = aug_list(input)
>>> out.shape
torch.Size([2, 3, 5, 6])
Reproduce with provided params. >>> out2 = aug_list(input, params=aug_list._params) >>> torch.equal(out, out2) True
Perform
OneOftransformation withrandom_apply=1andrandom_apply_weightsinImageSequential.>>> import kornia >>> input = torch.randn(2, 3, 5, 6) >>> aug_list = ImageSequential( ... kornia.color.BgrToRgb(), ... kornia.augmentation.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=1.0), ... kornia.filters.MedianBlur((3, 3)), ... kornia.augmentation.RandomAffine(360, p=1.0), ... random_apply=1, ... random_apply_weights=[0.5, 0.3, 0.2, 0.5] ... ) >>> out= aug_list(input) >>> out.shape torch.Size([2, 3, 5, 6])
Differences Between ImageSequential and AugmentationSequential#
ImageSequential and AugmentationSequential are both pipeline containers
in Kornia, but they’re designed for fundamentally different data handling
scenarios. Understanding when to use each prevents common pitfalls in vision
pipelines.
Use ``AugmentationSequential`` when:
The task requires synchronized transformations across multiple related tensors (images, masks, bounding boxes, keypoints).
Spatial correspondence must be maintained between inputs and targets, as in semantic segmentation or object detection workflows.
Multiple data formats need to be handled automatically with consistent random parameter sampling across all targets.
Use ``ImageSequential`` when:
The pipeline only processes image tensors without auxiliary spatial targets.
The workflow combines augmentation modules with general image processing modules (Gaussian blur, edge detection, color transforms).
A lightweight container is preferred without the overhead of multi-target synchronization logic.
Example using ImageSequential:
import torch
import kornia.augmentation as K
from kornia.augmentation.container import ImageSequential
from kornia.filters import GaussianBlur2d

img = torch.rand(1, 3, 256, 256)

seq = ImageSequential(
    K.RandomHorizontalFlip(p=1.0),
    GaussianBlur2d((3, 3), (1.5, 1.5)),  # any differentiable nn.Module can be inserted
)

out = seq(img)
Example using AugmentationSequential with synchronized transforms:
import torch
import kornia.augmentation as K

img = torch.rand(1, 3, 256, 256)
mask = torch.rand(1, 1, 256, 256)

aug = K.AugmentationSequential(
    K.RandomResizedCrop((128, 128), p=1.0),
    data_keys=["input", "mask"],
)

img_out, mask_out = aug(img, mask)
# identical random parameters applied to both tensors
AugmentationSequential coordinates supported data-key handlers from one set
of recorded parameters. Its non-rigid, mask-list and dtype limitations still
apply; see the class’s Convention block. ImageSequential processes image
tensors without dispatching auxiliary annotations.
PatchSequential#
- class kornia.augmentation.container.PatchSequential(*args, grid_size=(4, 4), padding='same', same_on_batch=None, keepdim=None, patchwise_apply=True, random_apply=False, random_apply_weights=None)[source]#
Container for performing patch-level image data augmentation.
See the Convention block on
AugmentationBase2D.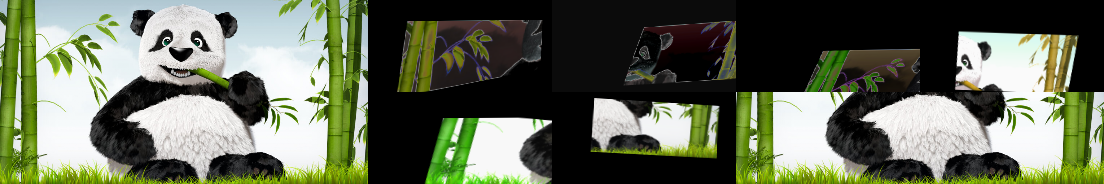
PatchSequential breaks input images into patches by a given grid size, which will be resembled back afterwards.
Different image processing and augmentation methods will be performed on each patch region as in [LYFC21].
- Parameters:
*args (
Module) – a list of processing modules.grid_size (
Tuple[int,int], optional) – positive(rows, columns)of patches in each image. Default:(4, 4)padding (
str, optional) –"same"temporarily zero-pads to a multiple ofgrid_sizeand removes the added border after augmentation, preserving the input spatial size."valid"crops the remainder before augmentation and keeps the cropped spatial size. Padding and cropping are centred; an odd extra pixel is placed on the right or bottom. Both modes preserve the batch size. Geometric transforms can move the temporary zero border into the retained image; removing the added border does not undo that movement. Default:"same"same_on_batch (
Optional[bool], optional) – apply the same transformation across the batch. If None, it will not overwrite the function-wise settings. Default:Nonekeepdim (
Optional[bool], optional) – whether to keep the output shape the same as input (True) or broadcast it to the batch form (False). If None, it will not overwrite the function-wise settings. Default:Nonepatchwise_apply (
bool, optional) – apply image processing args will be applied patch-wisely. ifTrueandrandom_apply=False, the number of args must equal the number of patches. ifFalse, the image processing args will be applied as a sequence to all patches. Default:Truerandom_apply (
Union[int,bool,Tuple[int,int]], optional) – randomly select children to apply in random order. Selections may repeat when the requested count is larger than the sum of the selection weights. Ifint(batchwise mode only), a fixed number of transformations will be selected. If(a,)(batchwise mode only), x number of transformations (a <= x <= len(args)) will be selected. If(a, b)(batchwise mode only), x number of transformations (a <= x <= b) will be selected. IfTrue, the whole list of args will be processed in a random order. IfFalseand notpatchwise_apply, the whole list of args will be processed in original order. IfFalseandpatchwise_apply, the whole list of args will be processed in original order location-wisely. Default:False
- Convention:
like
ImageSequential, this container takes image tensors only: it has nodata_keysand no.transform_matrixattribute.input images have shape
(B, C, H, W). Each image is split intoN = rows * columnspatches, ordered by row then column. Parameters index the flattenedB * Npatch batch.with
patchwise_apply=Trueandrandom_apply=False, each module processes its grid location across all images.same_on_batchcontrols parameter sharing, not which images are processed.with
patchwise_apply=False, the selected sequence is applied to every patch.an empty image batch retains the grid’s patch count and spatial sizes. Children must themselves support empty inputs; geometric patch inverses and mask transforms remain unsupported.
padding="valid"requires at least one pixel per patch in each spatial dimension. For example, an8 x 8image on a(3, 3)grid remains8 x 8with"same"and becomes6 x 6with"valid". The batch size, channel count, device and dtype are preserved.
Note
Transformation matrix returned only considers the transformation applied in
kornia.augmentationmodule. Those transformations inkornia.geometrywill not be taken into account.Note
See a working example here.
Examples
>>> import kornia.augmentation as K
>>> input = torch.randn(2, 3, 224, 224)
>>> seq = PatchSequential(
...     ImageSequential(
...         K.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=0.5),
...         K.RandomPerspective(0.2, p=0.5),
...         K.RandomSolarize(0.1, 0.1, p=0.5),
...     ),
...     K.RandomAffine(360, p=1.0),
...     ImageSequential(
...         K.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=0.5),
...         K.RandomPerspective(0.2, p=0.5),
...         K.RandomSolarize(0.1, 0.1, p=0.5),
...     ),
...     K.RandomSolarize(0.1, 0.1, p=0.1),
...     grid_size=(2,2),
...     patchwise_apply=True,
...     same_on_batch=True,
...     random_apply=False,
... )
>>> out = seq(input)
>>> out.shape
torch.Size([2, 3, 224, 224])
>>> out1 = seq(input, params=seq._params)
>>> torch.equal(out, out1)
True
Perform
OneOftransformation withrandom_apply=1andrandom_apply_weightsinPatchSequential.>>> import kornia >>> input = torch.randn(2, 3, 224, 224) >>> seq = PatchSequential( ... ImageSequential( ... K.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=0.5), ... K.RandomPerspective(0.2, p=0.5), ... K.RandomSolarize(0.1, 0.1, p=0.5), ... ), ... K.RandomAffine(360, p=1.0), ... K.RandomSolarize(0.1, 0.1, p=0.1), ... grid_size=(2,2), ... patchwise_apply=False, ... random_apply=1, ... random_apply_weights=[0.5, 0.3, 0.8] ... ) >>> out = seq(input) >>> out.shape torch.Size([2, 3, 224, 224])
Video Data Augmentation#
Video data is a special case of 3D volumetric data that contains both spatial and temporal information, which is sometimes referred to as 2.5D rather than 3D. In most applications, augmenting video data requires the same augmentation, with the same parameters, to be applied to every frame of a clip. VideoSequential does exactly that, with the same interface as nn.Sequential. It supports the \((B, C, T, H, W)\) and \((B, T, C, H, W)\) data formats.
import torch
import kornia.augmentation as K

transform = K.VideoSequential(
   K.RandomAffine(360),
   K.ColorJiggle(0.2, 0.3, 0.2, 0.3),
   data_format="BCTHW",
   same_on_frame=True,
)
clip = torch.rand(2, 3, 8, 64, 64)  # 2 clips of 8 RGB frames
out = transform(clip)
- class kornia.augmentation.container.VideoSequential(*args, data_format='BTCHW', same_on_frame=True, random_apply=False, random_apply_weights=None, if_unsupported_ops='raise')[source]#
VideoSequential for processing 5-dim video data like (B, T, C, H, W) and (B, C, T, H, W).
See the Convention block on
AugmentationBase2D.VideoSequential is used to replace nn.Sequential for processing video data augmentations. By default, VideoSequential enabled same_on_frame to make sure the same augmentations happen across temporal dimension. Meanwhile, it will not affect other augmentation behaviours like the settings on same_on_batch, etc.
- Parameters:
*args (
Module) – a list of augmentation module.data_format (
str, optional) – only BCTHW and BTCHW are supported. Default:"BTCHW"same_on_frame (
bool, optional) – apply the same transformation across the channel per frame. Default:Truerandom_apply (
Union[int,bool,Tuple[int,int]], optional) – randomly select a sublist (order agnostic) of args to apply transformation. If int, a fixed number of transformations will be selected. If (a,), x number of transformations (a <= x <= len(args)) will be selected. If (a, b), x number of transformations (a <= x <= b) will be selected. If None, the whole list of args will be processed as a sequence. Default:Falseif_unsupported_ops (
str, optional) – whatinversedoes on reaching a plainnn.Module, as inImageSequential:'raise'or'skip'. Default:"raise"
- Convention:
the input is 5-dimensional and the layout is named by
data_format, which accepts"BTCHW"(the default) and"BCTHW", case-insensitively; any other spelling raisesAssertionError. The output keeps the input layout.same_on_frameisTrueby default, so one draw is shared by every frame of a clip and the clip stays temporally consistent. Withsame_on_frame=Falseeach frame is drawn independently.like
ImageSequential, this container takes image tensors only: it has nodata_keysand no.transform_matrixattribute. Register aVideoSequentialas a child ofAugmentationSequentialto augment video masks, boxes and keypoints alongside the clip. For video boxes, usebboxvertices with shape(B, T, N, 4, 2); coordinate keysbbox_xyxyandbbox_xywhdo not accept(B, T, N, 4)tensors.
Note
Transformation matrix returned only considers the transformation applied in
kornia.augmentationmodule. Those transformations inkornia.geometrywill not be taken into account.Example
If set same_on_frame to True, we would expect the same augmentation has been applied to each timeframe.
>>> import kornia
>>> input = torch.randn(2, 3, 1, 5, 6).repeat(1, 1, 4, 1, 1)
>>> aug_list = VideoSequential(
...     kornia.augmentation.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=1.0),
...     kornia.color.BgrToRgb(),
...     kornia.augmentation.RandomAffine(360, p=1.0),
...     random_apply=10,
...     data_format="BCTHW",
...     same_on_frame=True)
>>> output = aug_list(input)
>>> (output[0, :, 0] == output[0, :, 1]).all()
tensor(True)
>>> (output[0, :, 1] == output[0, :, 2]).all()
tensor(True)
>>> (output[0, :, 2] == output[0, :, 3]).all()
tensor(True)
If set same_on_frame to False:
>>> aug_list = VideoSequential(
...     kornia.augmentation.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=1.0),
...     kornia.augmentation.RandomAffine(360, p=1.0),
...     kornia.augmentation.RandomMixUpV2(p=1.0),
... data_format="BCTHW",
... same_on_frame=False)
>>> output = aug_list(input)
>>> output.shape
torch.Size([2, 3, 4, 5, 6])
>>> (output[0, :, 0] == output[0, :, 1]).all()
tensor(False)
Reproduce with provided params. >>> out2 = aug_list(input, params=aug_list._params) >>> torch.equal(output, out2) True
Perform
OneOftransformation withrandom_apply=1andrandom_apply_weightsinVideoSequential.>>> import kornia >>> input, label = torch.randn(2, 3, 1, 5, 6).repeat(1, 1, 4, 1, 1), torch.tensor([0, 1]) >>> aug_list = VideoSequential( ... kornia.augmentation.ColorJiggle(0.1, 0.1, 0.1, 0.1, p=1.0), ... kornia.augmentation.RandomAffine(360, p=1.0), ... kornia.augmentation.RandomMixUpV2(p=1.0), ... data_format="BCTHW", ... same_on_frame=False, ... random_apply=1, ... random_apply_weights=[0.5, 0.3, 0.8] ... ) >>> out = aug_list(input) >>> out.shape torch.Size([2, 3, 4, 5, 6])