

Pinhole Camera#
PinholeCamera holds a batch of cameras, with (B, 4, 4) intrinsics and world-to-camera extrinsics, and
projects world points to pixels and back. pixel2cam() and cam2pixel() are the two halves of a dense
reprojection with the same (B, 4, 4) matrices: a depth map to camera-frame points, and those to the pixels of a
camera. For camera-frame points and a 3x3 K, see perspective.
In computer vision, we can map between the 3D world and a 2D image using projective geometry. The module implements the simplest camera model, the pinhole camera, which is the most basic model for general projective cameras from the finite cameras group.
The Pinhole Camera model is shown in the following figure:
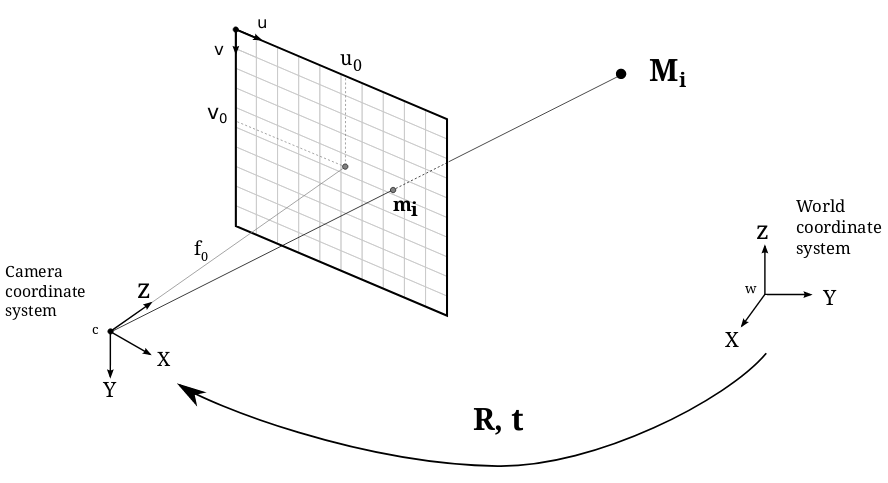
Using this model, a scene view can be formed by projecting 3D points into the image plane using a perspective transformation.
or
- where:
\(M'\) is a 3D point in space with coordinates \([X,Y,Z]^T\) expressed in a Euclidean coordinate frame known as the world coordinate system.
\(m'\) is the projection of the 3D point \(M'\) onto the image plane with coordinates \([u,v]^T\) expressed in pixel units.
\(K\) is the camera calibration matrix, also referred to as the intrinsic matrix.
\(C\) is the principal point offset with coordinates \([u_0, v_0]^T\) at the origin of the image plane.
\(f_x, f_y\) are the focal lengths expressed in pixel units.
The camera rotation and translation are expressed in terms of a Euclidean coordinate frame known as the world coordinate system. These terms are usually expressed by the joint rotation-translation matrix \([R|t]\), also known as the extrinsic matrix. It describes the camera pose around a static scene and transforms the coordinates of a 3D point \((X,Y,Z)\) from the world coordinate system to the camera coordinate system.
The PinholeCamera expects the intrinsic matrices and the extrinsic matrices
to be of shape (B, 4, 4) such that each intrinsic matrix has the following format:
And each extrinsic matrix has the following format:
- class kornia.geometry.camera.pinhole.PinholeCamera(intrinsics, extrinsics, height, width)[source]#
Model a batch of pinhole cameras with extrinsics: world points to pixels and back.
cam = PinholeCamera(intrinsics, extrinsics, height, width)storesBcameras:(B, 4, 4)intrinsics,(B, 4, 4)world-to-camera extrinsics and the(B,)image height and width.uv = cam.project(points)takes world points(B, N, 3), camerabprojectingpoints[b], and returns their pixels(B, N, 2);points = cam.unproject(uv, depth)takes pixels(B, N, 2)and their camera-frame depths(B, N, 1)and returns world points(B, N, 3). For camera-frame points and a3x3Kwithout extrinsics, useproject_points()andunproject_points()instead.- Convention:
intrinsicsis the(B, 4, 4)calibration matrix whose top-left \(3 \times 3\) block is[[fx, 0, cx], [0, fy, cy], [0, 0, 1]], andextrinsicsthe(B, 4, 4)world-to-camera transform[R | t](OpenCV / COLMAP semantics):project()computesK (R X + t)of world points, andunproject()returns world points. The functional API takes a3x3Kand no extrinsics, so it works in the camera frame.a caller’s autocast region does not change
project()andunproject(); in it, intrinsics and extrinsics that mix float32 and half dtypes run in float32. Undertorch.compileon MPS it still does (torch ignores the nested guard there).with
B > 1cameras the points ofproject(),(B, N, 3)or(B, H, W, 3), and the pixels ofunproject(),(B, N, 2)or(B, H, W, 2), need a leading axis of sizeBand at least three dimensions:(N, 3)and(1, N, 3)points, or(N, 2)and(1, N, 2)pixels, raiseValueError. A single camera (B = 1) takes any(*, N, 3)points or(*, N, 2)pixels with at least two dimensions.pixel coordinates are
(u, v)= (column, row) with integer pixel centres: pixel(0, 0)is centred at(0, 0), ascreate_meshgrid()enumerates, so a centred image hascx = (W - 1) / 2,cy = (H - 1) / 2. COLMAP’s half-pixel convention reports the same principal point half a pixel larger.kornia.geometry.camera,kornia.geometry.depthandkornia.geometry.calibrationall use this convention; see Camera and world conventions across the ecosystem.depthis the camera-framez, except where anormalize/normalize_pointsflag reads it as the Euclidean ray length.the class owns copies of the tensors it is constructed from:
scale_()and thetx/ty/tzsetters update only the camera, andscale()andclone()return independent cameras.
Warning
scale()andscale_()rescale the principal point ascx' = s * cx(the half-pixel rule), which disagrees with the integer pixel centres above: #4263.(B, N, 4, 4)storage is deprecated and will be rejected in a future release: #4266. Theintrinsicsform is not validated, butproject(),unproject(),intrinsics_inverse()andDepthWarperread only the top-left \(3 \times 3\) block, so a zero-paddedKbehaves like its homogeneous embedding.- Parameters:
intrinsics (
Tensor) – torch.Tensor with shape(B, 4, 4)containing the full 4x4 camera calibration matrix. Pass(B, 4, 4):(B, N, 4, 4)is deprecated, andproject()andunproject()never supported it.PinholeCamerasListstill stores that layout internally.extrinsics (
Tensor) – torch.Tensor with shape(B, 4, 4)containing the full 4x4 rotation-translation matrix, checked by the same predicate.height (
Tensor) – torch.Tensor with shape(B)containing the image height.width (
Tensor) – torch.Tensor with shape(B)containing the image width.
Note
We assume that the class attributes are in batch form in order to take advantage of PyTorch parallelism to boost computing performance.
See also
project_points(): camera-frame points and a(*, 3, 3)K, with no extrinsics.unproject_points(): pixels at given depths to camera-frame points with a(*, 3, 3)K.pixel2cam(),cam2pixel(): the two halves of a dense reprojection, a depth map to camera-frame points and those to another camera’s pixels, with this class’s(B, 4, 4)matrices.DepthWarper: warps an image between two of these cameras by depth.StereoCamera: a rectified stereo pair, from its two(B, 3, 4)projection matrices.CameraModel: the experimental camera-model API, with lens distortion and flat parameter vectors but no extrinsics.
- property batch_size: int#
Return the batch size of the storage.
- Returns:
scalar with the batch size.
- property camera_matrix: Tensor#
Return the 3x3 camera matrix containing the intrinsics.
- Returns:
torch.Tensor of shape
(B, 3, 3).
- clone()[source]#
Return a deep copy of the current object instance.
See the Convention block on
PinholeCamera.- Return type:
- property cx: Tensor#
Return the x-coordinate of the principal point.
- Returns:
torch.Tensor of shape
(B).
- property cy: Tensor#
Return the y-coordinate of the principal point.
- Returns:
torch.Tensor of shape
(B).
- device()[source]#
Return the device for camera buffers.
- Return type:
- Returns:
the
torch.deviceof the stored intrinsics.
- property extrinsics: Tensor#
The full 4x4 extrinsics matrix.
- Returns:
torch.Tensor of shape
(B, 4, 4).
- classmethod from_parameters(fx, fy, cx, cy, height, width, tx, ty, tz, batch_size, device, dtype)[source]#
Construct a batched pinhole camera from scalar parameter tensors.
See the Convention block on
PinholeCamera.This helper allocates batched \(4 \times 4\) intrinsic and extrinsic matrices, fills focal lengths/principal point/translation, and wraps them into a
PinholeCamerainstance.- Convention:
every parameter, including
heightandwidth, is broadcast overbatch_size.heightandwidthare stored as floating-point tensors of the requesteddtype, so the camera it builds can be scaled in place.
- Parameters:
fx (
Tensor) – Horizontal focal length per batch element.fy (
Tensor) – Vertical focal length per batch element.cx (
Tensor) – Principal point x-coordinate per batch element.cy (
Tensor) – Principal point y-coordinate per batch element.height (
int) – Image height in pixels.width (
int) – Image width in pixels.tx (
Tensor) – Camera translation along x per batch element.ty (
Tensor) – Camera translation along y per batch element.tz (
Tensor) – Camera translation along z per batch element.batch_size (
int) – Number of cameras in the batch.device (
Union[str,device,None]) – Target device for the created tensors.dtype (
dtype) – Target floating-point dtype for the created tensors.
- Return type:
- Returns:
Batched
PinholeCameraconfigured from the provided intrinsic and translation parameters.
- property fx: Tensor#
Return the focal length in the x-direction.
- Returns:
torch.Tensor of shape
(B).
- property fy: Tensor#
Return the focal length in the y-direction.
- Returns:
torch.Tensor of shape
(B).
- property intrinsics: Tensor#
The full 4x4 intrinsics matrix.
- Returns:
torch.Tensor of shape
(B, 4, 4).
- intrinsics_inverse()[source]#
Return the homogeneous 4x4 embedding of the inverse camera matrix.
Only the top-left 3x3 block of
intrinsicsis inverted. The remaining entries are ignored, so zero-padded intrinsics are supported. The result has a zero last row and column except for the homogeneous component at[..., 3, 3], which is one. See the Convention block onPinholeCamera.- Return type:
- Returns:
torch.Tensor of shape
(B, 4, 4).
- project(point_3d)[source]#
Project a 3d point in world coordinates onto the 2d camera plane.
See the Convention block on
PinholeCamera.- Convention:
point_3dmust be at least rank 2. An unbatched(3,)point raisesValueError. An empty point set returns an empty result.a point whose camera-frame
zis 0 does not raise:Kis applied first and the perspective divide is then skipped, so the result is the undividedK (R X + t).
Warning
This
z = 0answer differs fromproject_points(), which appliesKafter the skipped divide: #4267.- Parameters:
point_3d (
Tensor) – torch.Tensor containing the 3d points to be projected to the camera plane. The shape of the torch.Tensor can be(*, 3)with at least two dimensions; withB > 1cameras,(B, *, N, 3), camerabprojectingpoint_3d[b].- Return type:
- Returns:
torch.Tensor of (u, v) pixel coordinates with shape
(*, 2).
Example
>>> _ = torch.manual_seed(0)
>>> X = torch.rand(1, 3)
>>> K = torch.eye(4)[None]
>>> E = torch.eye(4)[None]
>>> h = torch.ones(1)
>>> w = torch.ones(1)
>>> pinhole = kornia.geometry.camera.PinholeCamera(K, E, h, w)
>>> pinhole.project(X)
tensor([[5.6088, 8.6827]])
- property rotation_matrix: Tensor#
Return the 3x3 rotation matrix from the extrinsics.
- Returns:
torch.Tensor of shape
(B, 3, 3).
- property rt_matrix: Tensor#
Return the 3x4 rotation-translation matrix.
- Returns:
torch.Tensor of shape
(B, 3, 4).
- scale(scale_factor)[source]#
Scale the pinhole model.
- Convention:
returns a new camera whose focal lengths, principal point and image size are multiplied by
scale_factor:fx' = s * fxandcx' = s * cx.height/widthtake the promoted dtype ofscale_factor * height.
Warning
The
cx' = s * cxrule disagrees with kornia’s integer pixel centres: #4263.- Parameters:
scale_factor (
Tensor) – a torch.Tensor with the scale factor. It has to be broadcastable with class members. The expected shape is(B)or(1).- Return type:
- Returns:
the camera model with scaled parameters.
- scale_(scale_factor)[source]#
Scale the pinhole model in-place.
- Convention:
applies the rescaling of
scale()in place and returnsself; the tensors passed to the constructor are not modified.
- property translation_vector: Tensor#
Return the translation vector from the extrinsics.
- Returns:
torch.Tensor of shape
(B, 3, 1).
- property tx: Tensor#
Return the x-coordinate of the translation vector.
- Returns:
torch.Tensor of shape
(B).
- property ty: Tensor#
Return the y-coordinate of the translation vector.
- Returns:
torch.Tensor of shape
(B).
- property tz: Tensor#
Returns the z-coordinate of the translation vector.
- Returns:
torch.Tensor of shape
(B).
- unproject(point_2d, depth)[source]#
Unproject a 2d point in 3d.
Transform coordinates in the pixel frame to the world frame.
See the Convention block on
PinholeCamera.- Parameters:
point_2d (
Tensor) – torch.Tensor containing the 2d to be projected to world coordinates. The shape of the torch.Tensor can be(*, 2)with at least two dimensions; withB > 1cameras,(B, *, N, 2), camerabunprojectingpoint_2d[b].depth (
Tensor) – torch.Tensor containing the depth value of each 2d points. The torch.Tensor shape must be equal to point2d(*, 1).
- Return type:
- Returns:
torch.Tensor of (x, y, z) world coordinates with shape
(*, 3).
Example
>>> _ = torch.manual_seed(0)
>>> x = torch.rand(1, 2)
>>> depth = torch.ones(1, 1)
>>> K = torch.eye(4)[None]
>>> E = torch.eye(4)[None]
>>> h = torch.ones(1)
>>> w = torch.ones(1)
>>> pinhole = kornia.geometry.camera.PinholeCamera(K, E, h, w)
>>> pinhole.unproject(x, depth)
tensor([[0.4963, 0.7682, 1.0000]])
- kornia.geometry.camera.pinhole.cam2pixel(cam_coords_src, dst_proj_src, eps=1e-12)[source]#
Project a map of camera-frame points to pixels through a 4x4 projection matrix.
uv = cam2pixel(cam_coords_src, dst_proj_src)takes a(B, H, W, 3)map of points in the source camera frame and the(B, 4, 4)projectiondst_proj_src, which moves a source-frame point into the destination camera frame and applies the destination intrinsics, and returns their(u, v)pixel coordinates in the destination camera,(B, H, W, 2). It is the second half of the dense warp ofDepthWarper, afterpixel2cam(). For points already in a camera’s frame and a3x3K, useproject_points().- Convention:
dst_proj_srcis a(B, 4, 4)projection matrix (thePinholeCameralayout, not a3x3K), and the result is(u, v)pixel coordinates in the destination frame, with integer pixel centres; see the Convention block onPinholeCamera.the batch of
dst_proj_srcis that ofcam_coords_srcor 1. A point behind the camera is divided like any other and is not flagged.float16andbfloat16points return their dtype. Half-precision points and matrices are projected and divided infloat32and the pixels rounded once, so a numeratorfx * x + cx * zbeyond thefloat16range does not overflow.
Warning
The perspective division is
x / (z + eps)rather than a guarded divide, soz = 0givesx / eps, huge for a nonzerox(infwhereepsunderflows), andepsbiases every small depth: #4267.- Parameters:
cam_coords_src (
Tensor) – (x, y, z) coordinates defined in the first camera coordinates system. Shape must be(B, H, W, 3).dst_proj_src (
Tensor) – the projection matrix between the reference and the non reference camera frame. Shape must be(B, 4, 4).eps (
float, optional) – small value to avoid division by zero error. Default:1e-12
- Return type:
- Returns:
torch.Tensor of shape
(B, H, W, 2)with (u, v) pixel coordinates.
See also
pixel2cam(): the first half of the warp, a depth map to camera-frame points.PinholeCamera: the camera model whose(B, 4, 4)matrices composedst_proj_src.project_points(): camera-frame points to pixels with a3x3K, skipping the divide atz = 0instead of addingeps.
- kornia.geometry.camera.pinhole.pixel2cam(depth, intrinsics_inv, pixel_coords)[source]#
Unproject a depth map to camera-frame points through a 4x4 inverse intrinsics matrix.
points = pixel2cam(depth, intrinsics_inv, pixel_coords)takes a(B, 1, H, W)depth map, the(B, 4, 4)inverse intrinsics thatPinholeCamera.intrinsics_inverse()returns and the homogeneous pixel grid(B, H, W, 3)of(u, v, 1), and returns the camera-frame pointdepth * K^-1 (u, v, 1)of every pixel as(B, H, W, 3). It is the first half of the dense warp ofDepthWarper;cam2pixel()is the second. For a3x3K, usedepth_to_3d_v2(), which builds the pixel grid itself.- Convention:
intrinsics_invis a(B, 4, 4)inverse calibration matrix (thePinholeCameralayout, not a3x3K), anddepthis the camera-framezat each pixel of the(u, v, 1)grid. Pixel centres are integers; see the Convention block onPinholeCamera.a
depththat is not(B, 1, H, W), anintrinsics_invthat is not(B, 4, 4)or apixel_coordsthat is not(B, H, W, 3)raisesValueError. Thatpixel_coordsmatches theHandWofdepthis not checked up front: the two broadcast, so a mismatch raises a broadcastingRuntimeErrorunless one of the sizes is 1.the batch of
intrinsics_invis that ofpixel_coordsor 1, anddepthbroadcasts against the result: one camera and one grid serve a batch of depth maps.
- Parameters:
- Return type:
- Returns:
torch.Tensor of shape
(B, H, W, 3)with (x, y, z) cam coordinates.
See also
cam2pixel(): the second half of the warp, camera-frame points to the pixels of a camera.PinholeCamera: the camera model whose(B, 4, 4)matrices this function takes.depth_to_3d_v2(): the same points from a3x3K, without a grid to pass.unproject_points(): selected pixels at given depths, with a3x3K.