

MobileViT#
Image classification Detection Segmentation
MobileViT interleaves MobileNetV2 blocks with small transformer blocks that treat patches as tokens, giving a
light-weight backbone with a global receptive field. MobileViT implements the
xxs, xs and s variants as an architecture only (random initialisation, no classification head) and
returns a stride-32 feature map.
Run it#
import torch
from kornia.models.vit_mobile import MobileViT

mvit = MobileViT(mode="xxs")  # 'xxs', 'xs' or 's'; random init

image = torch.rand(1, 3, 256, 256)
features = mvit(image)  # (1, 320, 8, 8) feature map, stride 32
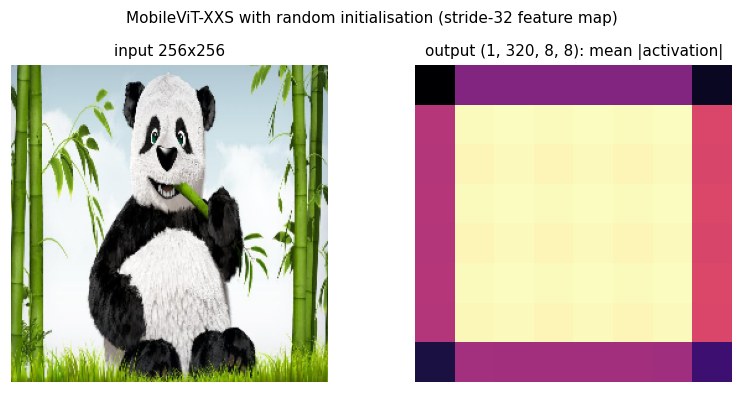
The 256×256 input and the mean absolute activation of the (320, 8, 8) output of MobileViT-XXS. With random
weights the map is not meaningful yet; train the model or load your own checkpoint.#
Add a head#
Pool the feature map and add a linear layer for classification; the output channel count is 320 for xxs,
384 for xs and 640 for s:
import torch
import torch.nn as nn
from kornia.models.vit_mobile import MobileViT

classifier = nn.Sequential(
    MobileViT(mode="xxs"),
    nn.AdaptiveAvgPool2d(1),
    nn.Flatten(),
    nn.Linear(320, 1000),
)

logits = classifier(torch.rand(1, 3, 256, 256))  # (1, 1000)
Paper#
MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer
Abstract: Light-weight convolutional neural networks (CNNs) are the de-facto for mobile vision tasks. Their spatial inductive biases allow them to learn representations with fewer parameters across different vision tasks. However, these networks are spatially local. To learn global representations, self-attention-based vision trans-formers (ViTs) have been adopted. Unlike CNNs, ViTs are heavy-weight. In this paper, we ask the following question: is it possible to combine the strengths of CNNs and ViTs to build a light-weight and low latency network for mobile vision tasks? Towards this end, we introduce MobileViT, a light-weight and general-purpose vision transformer for mobile devices. MobileViT presents a different perspective for the global processing of information with transformers, i.e., transformers as convolutions. Our results show that MobileViT significantly outperforms CNN- and ViT-based networks across different tasks and datasets. On the ImageNet-1k dataset, MobileViT achieves top-1 accuracy of 78.4% with about 6 million parameters, which is 3.2% and 6.2% more accurate than MobileNetv3 (CNN-based) and DeIT (ViT-based) for a similar number of parameters. On the MS-COCO object detection task, MobileViT is 5.7% more accurate than Mo-bileNetv3 for a similar number of parameters.
Tasks: Image Classification, Object Detection, Semantic Segmentation
Datasets: ImageNet, MS-COCO, PASCAL VOC
