

Visual Prompting#
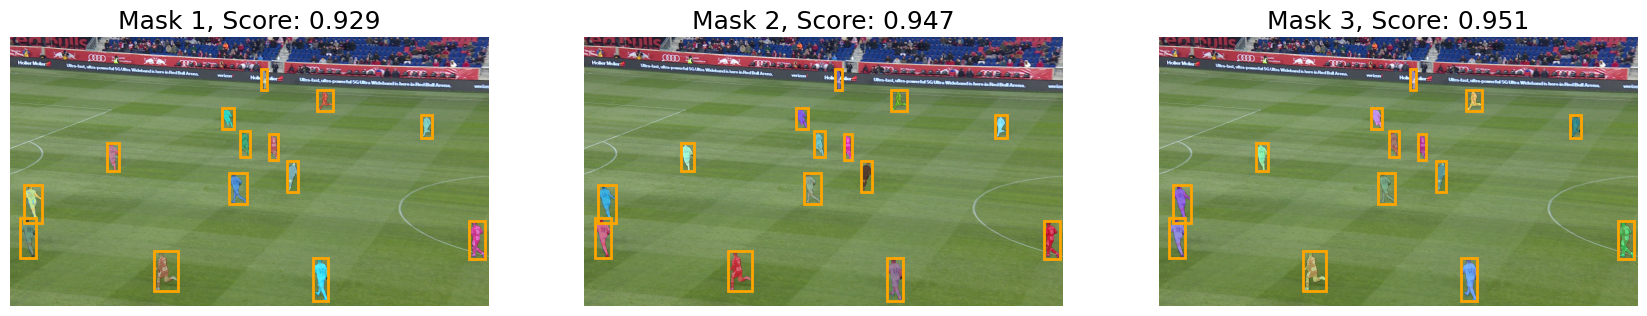
Visual Prompting is the task of streamlining computer vision processes by harnessing the power of prompts, inspired by the breakthroughs of text prompting in NLP. This innovative approach involves using a few visual prompts to swiftly convert an unlabeled dataset into a deployed model, significantly reducing development time for both individual projects and enterprise solutions.
By leveraging large pre-trained vision transformers, Visual Prompting not only eliminates the need for extensive data labeling but also facilitates the “teaching” of smaller AI systems.
How Kornia leverages Visual Prompting#
Kornia leverages the Visual Prompting task through the VisualPrompter API, which integrates powerful models like
the Segment Anything Model (SAM) into its computer vision toolkit. By incorporating SAM and the VisualPrompter API,
developers can harness the efficiency of Visual Prompting for faster segmentation tasks and improved computer vision workflows. This seamless integration allows users to utilize pre-trained vision transformers, significantly reducing manual data labeling efforts and enabling the “teaching” of smaller AI systems. As a result, Kornia users can take advantage of the versatility and adaptability offered by Visual Prompting, unlocking new possibilities for various computer vision applications.
How to use with Kornia#
import torch
from kornia.contrib.visual_prompter import VisualPrompter
from kornia.geometry.keypoints import Keypoints
from kornia.io import load_image, ImageLoadType

device = torch.device("cuda:0" if torch.cuda.is_available() else "cpu")

# load an image
image = load_image('./example.jpg', ImageLoadType.RGB32, device)

# Load the prompter (downloads the default SAM ViT-H checkpoint on first use)
prompter = VisualPrompter(device=device)

# set the image: This will preprocess the image and already generate the embeddings of it
prompter.set_image(image)

# Generate the prompts
keypoints = Keypoints(torch.tensor([[[500, 375]]], device=device, dtype=torch.float32)) # BxNx2

# For the keypoints label: 1 indicates a foreground point; 0 indicates a background point
keypoints_labels = torch.tensor([[1]], device=device) # BxN

# Runs the prediction with the keypoint prompts
prediction = prompter.predict(
   keypoints=keypoints,
   keypoints_labels=keypoints_labels,
   multimask_output=True,
)
You can also go through our full tutorial using Colab, found here.
Integration with other libraries, fine-tuning and more examples are coming soon.